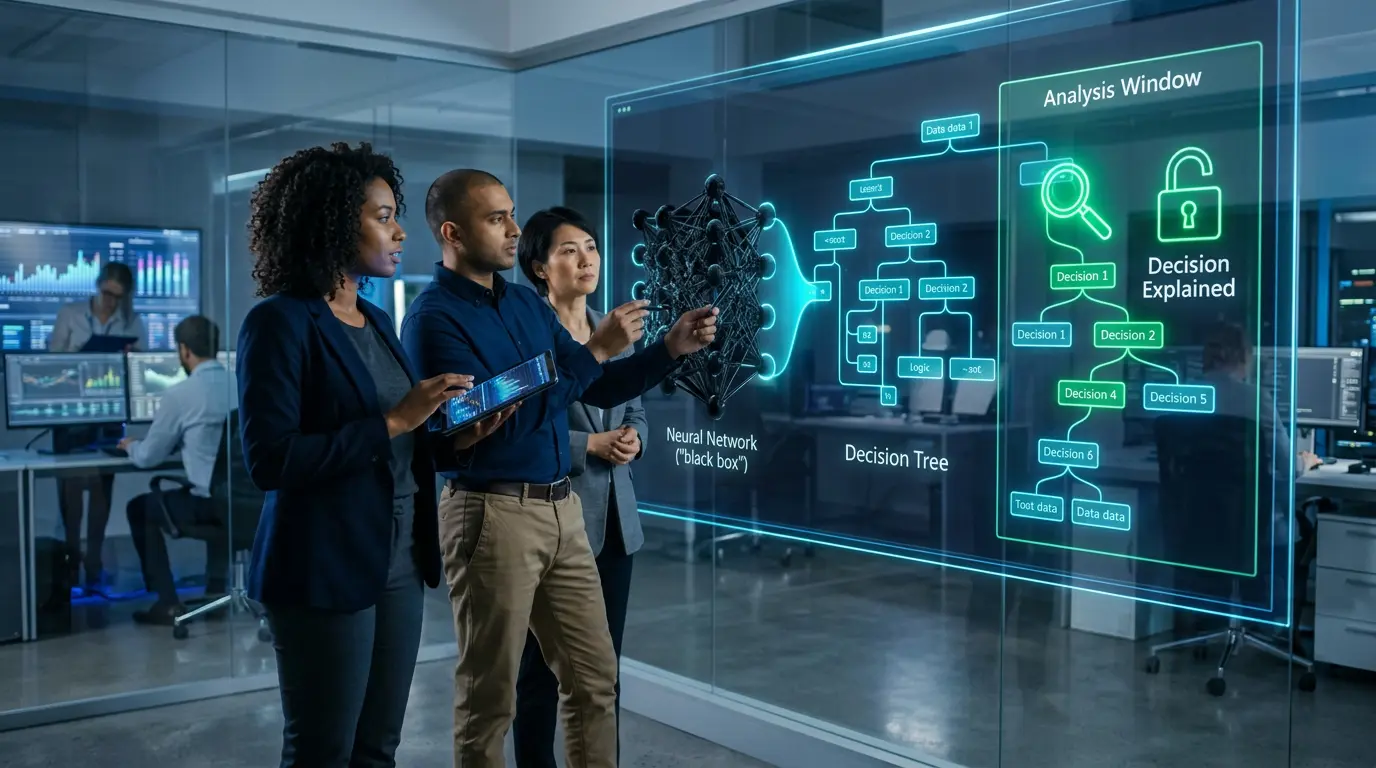
🔍 AI decisions are only trustworthy when you can explain them — and in 2026, the EU AI Act makes that a legal obligation. This guide covers the complete XAI landscape: how LIME, SHAP, DALEX, InterpretML, and attention visualization work in plain English; a side-by-side tool comparison with ease-of-use ratings; what EU AI Act Articles 13 and 14 now legally require organizations to document; real-world deployments from finance, healthcare, and HR; and a practical 12-step XAI checklist for compliance and data teams.
Last Updated: September 17, 2026
Explainable AI (XAI) has crossed a threshold in 2026 that transforms it from a technical best practice into a legal obligation. The EU AI Act’s transparency provisions are now in force, with organizations deploying high-risk AI systems for credit scoring, hiring, medical diagnostics, or other consequential decisions required to demonstrate traceability and explainability to regulators — or face penalties up to €35 million or 7% of global annual turnover. When a credit model declines a loan application, when a diagnostic AI flags a patient for elevated cancer risk, or when an HR screening tool ranks candidates, the organizations deploying those systems are now expected to explain why. Not just in plain language to the affected individual, but in documented technical detail to auditors, regulators, and oversight bodies. IBM’s research on explainable AI identifies this accountability gap — the distance between a model’s internal logic and a human’s ability to understand it — as the central challenge in deploying AI responsibly at enterprise scale. Closing that gap is no longer optional.
This guide is built for data scientists, compliance officers, risk managers, and technical leaders who need to understand both the mechanics of XAI and its regulatory implications. It covers the four primary XAI techniques — LIME, SHAP, attention visualization, and rule extraction — with honest assessments of where each works and where each falls short. It covers the six leading XAI tools and frameworks compared side-by-side with ease-of-use and suitability ratings, the definitive LIME vs SHAP vs DALEX comparison that data science teams consistently need, the exact regulatory requirements from EU AI Act Articles 13 and 14 and NIST AI RMF’s Explainability subcategory, and three documented real-world use cases showing what production XAI looks like in finance, healthcare, and HR. It includes a practical 12-step implementation checklist designed to move your organization from awareness to documented compliance.
The 2026 consensus among AI governance practitioners is clear: explainability is not a single technique or a checkbox on an audit form. It is a design principle that must be embedded into the AI development lifecycle from the moment a use case is scoped — not retrofitted after deployment when a regulator asks questions. Organizations that have not yet mapped their AI systems to their explainability obligations have a narrow window to act. For a broader overview of the governance landscape, see our guide to AI Governance. For the documentation standards that house XAI evidence, our guide to AI Model Cards covers the transparency documentation that regulators and auditors use to evaluate your explainability program.
📖 New to AI terminology? Visit the AI Buzz AI Glossary — 65+ essential AI terms explained in plain English, each linking to a full in-depth guide.
🔍 1. What Is Explainable AI (XAI) — And Why It Matters in 2026
Explainable AI refers to a set of methods, techniques, and practices that make the outputs and internal reasoning of AI models understandable to humans. The core problem it addresses is what researchers call the “black box” problem: most high-performing machine learning models — gradient boosted trees, deep neural networks, large language models — are structurally opaque. They take inputs, apply billions of mathematical operations, and produce outputs. But the path from input to output is not legible to the humans reviewing those outputs or acting on them.
The distinction between explainability and interpretability is worth establishing early, because compliance and governance teams encounter both terms — and NIST carefully distinguishes them. Explainability is the technical capacity to describe the mechanism by which the AI system produced an output — which features influenced the decision, by how much, and in which direction. Interpretability refers to the human capacity to understand what that explanation means in context — why a loan was denied, what it would take to get a different outcome, and whether the reasoning reflects the intended policy. A decision tree is interpretable by design — its logic is readable as a flowchart. A neural network is not inherently interpretable, but XAI techniques can make individual neural network predictions explainable after the fact. NIST identifies “explainable and interpretable” as one of its seven AI trustworthiness characteristics that every AI system should satisfy — treating them as complementary, not interchangeable.
XAI defined: Explainable AI encompasses the methods and processes by which the inputs, logic, and outputs of an AI system can be communicated in terms understandable to a specific audience — whether that audience is a data scientist debugging a model, a regulator auditing a deployment, or a customer asking why their application was declined.
In 2026, the business case for XAI operates on three parallel tracks. The first is regulatory compliance: the EU AI Act, GDPR Article 22, the Colorado AI Act (effective February 2026), and the US Federal Reserve’s SR 26-2 guidance on AI model risk in banking all impose explainability requirements on high-stakes AI systems. The second is operational trust: deployment teams that cannot explain model behavior cannot debug it effectively, cannot catch systematic bias, and cannot build justified confidence in model outputs among the clinicians, underwriters, or officers who must act on them. The third is competitive positioning: organizations that can demonstrate explainable, auditable AI are increasingly preferred by enterprise buyers, regulators, and partners over those that cannot. The choice between building interpretable models and applying post-hoc explainability tools is itself a governance decision that EU AI Act Article 13 influences: for high-risk AI, the simpler and more inherently interpretable the model, the lower the explainability overhead required for compliance.
🛠️ 2. XAI Techniques Explained — LIME, SHAP, Attention Visualization, and Rule Extraction
No single XAI technique works for every model type, every use case, or every audience. The right choice depends on what question you are trying to answer — whether you need to explain a single prediction, understand which features matter globally, debug unexpected model behavior, or produce documentation for a regulator. The four techniques below cover the most widely deployed XAI approaches in 2026, with practical guidance on when to use each and where each has real limitations.
A critical mistake made by most teams new to XAI is choosing LIME or SHAP because they are well-known, then figuring out how to use the output afterward. The right sequence is the reverse: identify the question you actually need answered, then select the technique that answers it.
LIME (Local Interpretable Model-Agnostic Explanations)
LIME works by creating a simplified, interpretable approximation of a complex model’s behavior in the local neighborhood of a specific prediction. When you ask LIME to explain why a particular loan application was declined, it generates a set of slightly varied versions of that application, runs them through the original model, and then fits a simple linear model to the pattern of results. The linear model approximates what the complex model was doing for that specific case. The output is a ranked list of features that contributed most to the prediction, with their relative weights.
LIME is model-agnostic, meaning it works with any machine learning model regardless of architecture. This makes it highly versatile for organizations running heterogeneous model portfolios. LIME generates explanations in approximately 100–500ms per prediction, making it fast enough for interactive use cases and customer-facing explanation interfaces. In practice, it is most valuable for explaining individual predictions to non-technical audiences — a customer asking why their claim was denied, or a clinician asking why the diagnostic model flagged a specific patient.
The critical limitation of LIME is consistency: research documents only 65–75% feature ranking overlap across independent runs on the same instance. Because the surrogate is fit stochastically, running LIME on the same instance twice may produce different explanations. For compliance applications where reproducibility is required, LIME’s stochastic variability is a material limitation that must be addressed through averaging or ensemble approaches. Use LIME for initial exploration and customer communication — never as the primary method for regulatory audit documentation.
SHAP (SHapley Additive exPlanations)
SHAP is grounded in cooperative game theory. It calculates each feature’s contribution to a specific prediction by computing the average marginal contribution of that feature across all possible combinations of other features — satisfying three fundamental mathematical axioms (efficiency, symmetry, and dummy) that provide theoretical guarantees about explanation consistency. The result is a SHAP value for each input feature — a signed number that tells you how much that feature increased or decreased the prediction compared to the model’s average prediction.
SHAP provides both local explanations (why did this specific prediction happen?) and global explanations (which features matter most across the entire model?). In practice, SHAP delivers explanations for each row using waterfall or force plots indicating how features move the prediction away from the baseline, plus global summaries using bee swarm and bar plots revealing the overall most important features and their relationship with the target. This dual capability makes SHAP the preferred technique for audit documentation, model risk management reviews, and regulatory submissions.
The limitation is computational cost. Kernel SHAP requires approximately 1–5 seconds per explanation — prohibitively slow for real-time customer-facing applications at scale. Tree SHAP, a specialized variant for tree-based models including XGBoost, LightGBM, and Random Forest, reduces this to approximately 10–50ms per explanation by exploiting the model’s tree structure. For organizations running tree-based models in high-volume environments — credit scoring, fraud detection, insurance underwriting — Tree SHAP is the practical production solution. For organizations embedding SHAP into formal risk management documentation, see how it connects to the AI Risk Assessment framework.
Attention Visualization (for Transformer Models)
Attention visualization is the primary XAI technique for large language models and other transformer-based neural networks. In a transformer model, the attention mechanism determines how much weight the model gives to each part of the input when generating each part of the output. Attention visualization surfaces these weights as a heatmap or ranked list, showing which input tokens — words, sentences, or document sections — the model attended to most strongly when producing a specific output.
The practical applications of attention visualization in 2026 are concentrated in NLP-heavy domains: legal AI reviewing contracts for risk clauses, clinical AI summarizing patient notes, and content moderation systems flagging policy violations. This technique is native to the model architecture, meaning no external library is needed — most transformer implementations expose attention weights directly through their APIs. The important limitation is that attention weights do not always correspond to causal importance — attention visualization should be treated as an evidence-generating tool that supports human review, not as a definitive causal explanation.
Rule Extraction Methods
Rule extraction methods take a trained complex model and distill its decision logic into a set of human-readable IF-THEN rules. An example output for a credit risk model might read: “IF debt-to-income ratio > 0.45 AND number of recent credit inquiries > 3 THEN high-risk classification.” Rule extraction is the preferred XAI technique for regulated industry contexts where explainability must be communicated to non-technical regulators, lawyers, or executives who cannot read SHAP plots or attention heatmaps.
The US Federal Reserve’s SR 26-2 guidance on AI and machine learning model risk management (effective April 2026) explicitly requires that model documentation include human-interpretable descriptions of model logic — and rule extraction is one of the primary mechanisms for satisfying that requirement for complex classification models. The trade-off is fidelity: a random forest with 500 trees makes decisions that cannot be perfectly captured by a 10-rule surrogate without significant approximation error. Rule extraction is best used alongside SHAP for a complete documentation package — SHAP provides the technically rigorous quantitative explanation; rule extraction provides the human-readable narrative. For guidance on incorporating rule extraction output into formal AI documentation, see our guide to AI Model Cards.
📊 3. XAI Tools and Frameworks Compared: The 2026 Landscape
The XAI tool landscape in 2026 has matured into a well-differentiated ecosystem where each major framework occupies a distinct position — and where choosing the wrong tool for the wrong problem is the most common practitioner mistake. The tools below are organized from the most widely deployed (SHAP, LIME) through to enterprise platforms (IBM AI Fairness 360, Google What-If Tool) and the underutilized R-ecosystem powerhouse (DALEX). Each profile covers what the tool actually does, where it works best, and where it falls short.
DALEX (Descriptive mAchine Learning EXplanations) is the most powerful and least widely deployed of the three major XAI frameworks — primarily because it originated in the R ecosystem and has only more recently developed robust Python support. DALEX excels at model-agnostic, framework-agnostic model diagnostics that go beyond feature attribution to model comparison and performance evaluation. Its Fairness Module (part of the fairmodels package) is particularly strong for regulatory bias analysis — providing conditional demographic parity checks and counterfactual explanations that address GDPR and EU AI Act bias obligations more directly than SHAP or LIME. DALEX’s local breakdown plots and Ceteris Paribus profiles are especially useful for high-stakes applications where understanding the step-by-step reasoning behind an individual prediction matters as much as the feature attribution. Comparing DALEX’s global importance rankings with SHAP’s global summary plot as a consistency check is a documented best practice for production compliance deployments.
InterpretML (Microsoft) is Microsoft’s open-source XAI toolkit that provides both glassbox (inherently interpretable) and black-box explanation methods. Its signature contribution is the Explainable Boosting Machine (EBM) — an interpretable model that achieves performance comparable to gradient boosted trees while remaining directly readable, eliminating the need for post-hoc explanation entirely for many use cases. InterpretML integrates naturally into Azure ML workflows and supports Python-native development, making it the strongest choice for organizations on the Microsoft Azure AI stack who want to build interpretable-by-design models alongside post-hoc explainability for legacy black-box models.
Google What-If Tool is a visual, no-code XAI interface designed for non-technical stakeholders — model behavior exploration, fairness evaluation, and counterfactual analysis through an interactive UI rather than Python code. It integrates with TensorFlow models and Google Cloud’s AI Platform, making it most useful for organizations in the Google Cloud ecosystem who need to communicate model behavior to non-technical decision-makers, compliance reviewers, or auditors who cannot interpret code-based SHAP outputs. The What-If Tool’s strength is accessibility; its limitation is that it is primarily exploratory rather than audit-grade — suitable for investigation and communication but not as the primary evidence artifact for regulatory compliance.
IBM AI Fairness 360 (AIF360) is specifically designed for bias detection and fairness analysis. AIF360 implements 75+ fairness metrics and 10+ bias mitigation algorithms, making it the most comprehensive open-source toolkit for the bias assessment requirements that the Colorado AI Act, EU AI Act Article 10, and GDPR Article 22 impose on high-risk AI. For organizations deploying AI in employment, credit, or healthcare contexts, AIF360 is not an alternative to SHAP or LIME — it is a complement that addresses the specific fairness dimension that those tools do not prioritize.
| Tool / Framework | XAI Method | Best For | Open Source? | Ease of Use / Key Limitation |
|---|---|---|---|---|
| SHAP | Shapley values (game theory); global + local feature attribution | Production ML explanations; compliance evidence; consistent, auditable feature attribution for any model type | ✅ Yes (MIT) | ⭐⭐⭐ Moderate — requires Python; KernelSHAP slow on large datasets; assumes feature independence |
| LIME | Local surrogate model; perturbs inputs around specific instance; local explanations only | Fast local explanations; NLP and image classification; exploratory analysis where speed > consistency | ✅ Yes (BSD) | ⭐⭐⭐⭐ Easy — fast and intuitive; 65–75% run-to-run consistency is a compliance risk; no global explanations |
| DALEX | Model-agnostic diagnostics; local breakdown plots; Ceteris Paribus; fairness via fairmodels package | High-stakes regulated applications; bias and fairness compliance; model comparison and benchmarking | ✅ Yes (GPL-2) | ⭐⭐⭐ Moderate — strongest in R; Python support improving; best for regulatory fairness analysis |
| InterpretML (Microsoft) | EBM (glassbox + interpretable by design); black-box explanation via SHAP/LIME integration | Microsoft Azure ML teams; building interpretable-by-design models; avoiding post-hoc explanation overhead | ✅ Yes (MIT) | ⭐⭐⭐⭐ Easy — well-documented; EBM performance matches XGBoost on many tasks |
| Google What-If Tool | Visual model exploration; counterfactual analysis; fairness slices; no-code interactive UI | Non-technical stakeholder communication; Google Cloud / TensorFlow environments; exploratory fairness investigation | ✅ Yes (Apache 2.0) | ⭐⭐⭐⭐⭐ Very easy — no coding required; primarily exploratory (not audit-grade); TensorFlow dependency |
| IBM AIF360 | 75+ fairness metrics; 10+ bias mitigation algorithms; demographic parity; equalized odds | Bias and fairness compliance in employment, credit, and healthcare AI; EU AI Act Article 10 and Colorado AI Act bias assessments | ✅ Yes (Apache 2.0) | ⭐⭐⭐ Moderate — extensive but requires understanding of fairness metrics; complements SHAP/LIME |
🔬 4. LIME vs SHAP vs DALEX: The Definitive 2026 Comparison
The three dominant open-source XAI frameworks are frequently misunderstood as interchangeable alternatives when they are actually fundamentally different approaches that address different aspects of the explainability problem. LIME answers “what affected this decision?” by fitting a local surrogate model. SHAP answers “by how much did each feature affect this decision?” by computing marginal contributions using game theory. DALEX answers “what would change this decision?” through a comprehensive diagnostic lens that includes local breakdown, Ceteris Paribus profiles, and fairness evaluation. Understanding which question is most important for your deployment determines which tool to prioritize.
The production XAI tool selection rule for compliance-sensitive deployments: Use SHAP as your primary feature attribution tool for its mathematical consistency and audit-grade reproducibility. Use LIME for fast local explanations in development and exploratory analysis where speed matters more than statistical rigor. Use DALEX when regulatory fairness analysis — specifically bias across demographic groups — is the primary compliance requirement. The best production XAI programs in 2026 use all three in different roles, not one exclusively.
| Comparison Dimension | SHAP | LIME | DALEX |
|---|---|---|---|
| Underlying Method | Game theory Shapley values — evaluates feature contribution across all possible feature combinations | Local surrogate modeling — fits a simple linear model around the instance being explained | Model-agnostic diagnostics — local breakdown, Ceteris Paribus, PDP, accumulated local effects |
| Explanation Scope | ✅ Both global and local — strongest at both levels | ⚠️ Local explanations only — no global model explanations available natively | ✅ Both global and local — particularly strong on local breakdown with step-by-step reasoning chains |
| Consistency / Reproducibility | ✅ High — deterministic given fixed model and data; TreeSHAP is fully deterministic | ⚠️ Low — 65–75% feature ranking overlap across independent runs; stochastic by design | ✅ High — deterministic breakdown plots; reproducible across runs |
| Computational Cost | ⚠️ Medium–High — KernelSHAP slow on large feature sets; TreeSHAP fast for tree models (10–50ms) | ✅ Low — fast local approximation (100–500ms); suitable for real-time customer-facing interfaces | ⚠️ Medium — breakdown plots efficient; Ceteris Paribus more computationally demanding |
| Handles Non-linear Relationships | ✅ Yes — TreeSHAP captures nonlinear patterns for tree-based models natively | ⚠️ Limited — fits a local linear model; cannot capture nonlinear associations by design | ✅ Yes — Ceteris Paribus profiles and ALE explicitly capture feature response curves including non-linearities |
| Regulatory Compliance Suitability | ✅ High — deterministic, documented mathematical foundation; widely accepted by regulators as audit evidence | ⚠️ Lower — stochastic variability is a compliance risk; requires averaging across runs for stable explanations | ✅ High — fairmodels package specifically addresses EU AI Act and GDPR demographic fairness requirements |
| Primary Strength | Mathematically rigorous, consistent feature attribution; the gold standard for compliance-grade feature importance evidence | Speed and accessibility; intuitive interface; best for NLP and image models where SHAP is computationally expensive | Fairness analysis; model comparison; stepwise breakdown of individual predictions; regulatory bias evidence generation |
| Primary Weakness | Computationally expensive for large feature sets; assumes feature independence which is often violated | No global explanations; stochastic variability limits compliance use without aggregation | Less mature Python support than SHAP/LIME; requires more setup investment; less widely known outside R community |
| Best Use Case in 2026 | Credit scoring, HR screening, any high-stakes application requiring audit-grade feature attribution evidence | Development-stage exploration, NLP models, image classification, rapid prototyping of explanations | Regulatory fairness audits, demographic bias compliance (Colorado AI Act, EU AI Act Art. 10), high-stakes individual prediction explanations |
🔒 Building an AI governance framework? Browse the AI Buzz Governance & Security Hub — 30+ in-depth guides covering OWASP, NIST, ISO 42001, AI risk management, and enterprise AI security frameworks.
⚖️ 5. Explainable AI and Regulatory Requirements — What the Law Now Requires
The regulatory landscape for AI explainability shifted decisively in 2025 and 2026. Organizations that were treating XAI as a technical best practice now face legal obligations with documented penalties. The most significant frameworks are the EU AI Act (particularly Articles 13 and 14), GDPR Article 22, the Colorado AI Act (effective February 2026), and the US Federal Reserve’s SR 26-2 guidance for banking institutions. Understanding what each actually requires — not just in principle, but in documented practice — is the starting point for a compliant XAI implementation.
EU AI Act Articles 13 and 14. Article 13 mandates that high-risk AI systems “shall be designed and developed in such a way as to ensure that their operation is sufficiently transparent to enable deployers to interpret a system’s output and use it appropriately.” In plain terms: if your organization deploys a high-risk AI system — in employment, credit, healthcare, education, or law enforcement — you are legally required to ensure that the people using it can actually interpret its outputs and act on them correctly. Article 13 further specifies that deployers must receive information covering the system’s characteristics, capabilities, limitations, performance metrics, and expected accuracy. For any AI system making or influencing credit decisions, hiring decisions, insurance pricing, or medical triage — all Annex III high-risk categories — Article 13 compliance requires that SHAP values, LIME outputs, or equivalent explanations can be generated, stored, and presented on demand for each individual decision.
Article 14 adds the human oversight dimension: high-risk AI systems must include “effective human oversight” mechanisms that allow deployers to understand and monitor the AI’s behavior, detect operational failures, and intervene when outputs appear inappropriate. An explanation that satisfies a data scientist but not a credit officer is not Article 14 compliant — because the credit officer is the human oversight actor the article is designed to empower. Organizations deploying high-risk AI without satisfying Articles 13 and 14 face fines up to €35 million or 7% of global annual turnover.
The 2026 XAI compliance checklist that satisfies both EU AI Act and NIST simultaneously:
☐ XAI method documented and tested before deployment (SHAP for feature attribution, AIF360 for fairness)
☐ Global and local explanations available on demand for every model in production
☐ Explanation quality tested across demographic subgroups — equal explanation coverage required
☐ Explanation outputs stored as immutable audit logs with timestamps and version references
☐ Human-readable explanation format available for oversight personnel (not just data scientists)
☐ Contestability mechanism documented — how can an affected individual challenge an AI decision?
☐ Model card and AI system card include XAI methodology, evaluation metrics, and known limitations
☐ Post-deployment monitoring of explanation consistency — drift in explanation patterns signals model drift
GDPR Article 22 grants individuals the right not to be subject to solely automated decisions that produce legal or similarly significant effects — and when automated decision-making does occur, organizations must provide “meaningful information about the logic involved.” The emerging interpretation in 2026 is that a general statement about model type is insufficient — the explanation must be specific to the individual’s case. SHAP-generated explanations at the individual prediction level satisfy this requirement more reliably than LIME outputs, because SHAP values are more consistent and reproducible across similar cases. For a comprehensive overview of the EU AI Act compliance framework, see our guide to the EU AI Act.
NIST AI RMF Explainability Requirements. NIST’s seven AI trustworthiness characteristics place “explainable and interpretable” as one of the core properties that every trustworthy AI system should satisfy. For NIST AI RMF compliance, the Measure function (MEASURE.2.5) requires that “AI system explainability and interpretability are assessed” using appropriate methods — with SHAP, LIME, and DALEX all being accepted methods for satisfying this subcategory. The NIST AI 600-1 Generative AI Profile (July 2024) extends these requirements to LLM-based systems, identifying confabulation, explainability, and data privacy as the top trustworthiness risks for generative AI — requiring organizations to document how they address each before deploying generative AI in high-stakes contexts.
US state and federal requirements. The Colorado AI Act (effective February 2026) requires developers and deployers of high-risk AI systems — covering employment, healthcare, housing, and financial services — to document their systems’ intended outputs and their basis for high-stakes decisions, with consumer-facing disclosure requirements when automated decisions affect individuals. The US Federal Reserve’s SR 26-2 guidance (effective April 2026) extends model risk management requirements explicitly to AI and machine learning models in banking, requiring that model documentation include human-interpretable descriptions of model logic and that explanation outputs are tested for consistency and reliability before production deployment.
💼 6. Real-World XAI Use Cases: Finance, Healthcare, and HR
Abstract XAI frameworks become meaningful when anchored to the specific decision types where explainability failures have produced the most costly regulatory and operational consequences. The three use cases below document what production-grade XAI looks like in the three industries with the highest regulatory explainability exposure in 2026.
Finance: Explainable Credit Scoring Under SR 26-2 and EU AI Act
A major European bank deploying an XGBoost credit scoring model is required under EU AI Act Article 13 to provide applicants with meaningful information about any automated decision that significantly affects them. The bank’s compliance architecture uses TreeSHAP — the tree-specific variant of SHAP — to generate individual explanation reports for every declined application. Each report includes a waterfall chart showing the five features with the greatest positive and negative impact on the credit decision, alongside a plain-language sentence for each feature: “Your recent payment history reduced your score by 34 points primarily due to two missed payments in the past six months.”
The compliance validation challenge was ensuring that SHAP explanations were equally informative across demographic groups — because an explanation that is technically available but consistently less informative for minority applicants fails the fairness requirement even if the model is technically accurate. The bank used AIF360’s demographic parity metrics alongside SHAP to verify that explanation coverage and quality were consistent across age groups, nationalities, and gender — generating the bias impact assessment documentation that SR 26-2 and EU AI Act Article 10 require. For credit risk models, SHAP demonstrates that a loan application was pushed toward high risk mainly due to a high debt-to-income ratio and recent delinquencies, whereas stable income helped to lower the risk — the format that satisfies both the ECOA adverse action notice requirement and the SR 26-2 model risk documentation standard.
Healthcare: Explainable AI Triage with Human Oversight Documentation
A large hospital system deploying an AI triage priority scoring model uses SHAP and DALEX together: SHAP generates the overall feature attribution (vital sign patterns, chief complaint classification, historical case similarity score), while DALEX’s Ceteris Paribus profiles show clinicians how the triage score would change if specific vitals were different. The DALEX Ceteris Paribus output is displayed directly in the clinical dashboard alongside the triage recommendation: “If systolic blood pressure increased to 160 (vs current 142), priority would increase from Level 3 to Level 2.” This format provides the human oversight mechanism that EU AI Act Article 14 requires — the clinician is not simply presented with a recommendation but with a structured explanation that supports informed decision-making.
The system documents every explanation generated alongside the clinician’s follow-on decision, creating the audit trail that NIST MEASURE.2.5 and hospital accreditation bodies require. Healthcare regulators demand explainable triage systems that doctors can validate — and the Ceteris Paribus visualization is specifically designed to provide that validation capability at the point of clinical decision.
HR: Explainable Candidate Screening Under Colorado AI Act and EU AI Act
A recruitment platform using a gradient boosted model to rank candidates for software engineering roles uses SHAP for feature attribution (which resume elements drive the ranking score) and DALEX’s fairmodels package for demographic parity testing (whether the ranking score distribution differs significantly across gender, ethnicity, or age groups). The compliance documentation package for each hiring round includes: SHAP global feature importance showing that relevant technical skills drive the highest-weight features rather than demographic proxies; DALEX fairness plots showing demographic parity across four protected groups with acceptable tolerance bands; and per-candidate SHAP waterfall charts available for any candidate who requests explanation of their ranking under GDPR Article 22 or Colorado AI Act contestability rights. The SHAP + DALEX architecture is the technical implementation of the bias testing obligations that the Colorado AI Act (February 2026) and EU AI Act Annex III impose — and the model card documenting the XAI methodology is the evidence artifact that regulators request during audits.
🏭 7. XAI in Practice — Applications by Industry
XAI is not a generic capability applied uniformly across all AI deployments. Each industry has a distinct set of stakeholders who need explanations — regulators, clinicians, lawyers, HR teams, customers — and each requires a different format, level of technical detail, and regulatory framing.
Financial Services: Credit scoring models have been subject to adverse action notice requirements under ECOA and FCRA for decades. SHAP — specifically TreeSHAP — is the production standard for tabular credit and fraud models, producing consistent, case-specific feature attributions that satisfy both adverse action notice requirements and SR 26-2 model risk documentation. Fraud detection models present a different challenge: the speed requirement means real-time Kernel SHAP is not feasible, but Tree SHAP at 10–50ms is fast enough for post-decision explanation generation in fraud case management workflows.
Healthcare: For clinical decision support systems processing structured patient data — lab values, vital signs, medication history — SHAP provides the most practically useful explanation format. A clinical team reviewing an AI-generated sepsis risk alert can see that the model was primarily driven by a white blood cell count of 18.3 (high), a respiratory rate of 26 (elevated), and a recent temperature spike — specific, interpretable, actionable information that supports independent clinical judgment. For medical imaging AI, attention visualization and gradient-based saliency maps highlight the specific regions in a medical image that most influenced a classification.
Legal: Attention visualization applied to contract analysis LLMs surfaces which specific clauses, phrases, or provisions the model weighted most heavily when generating a risk classification — providing attorneys with a traceable audit trail supporting professional accountability. Rule extraction adds value by converting the model’s implicit logic into IF-THEN rules that attorneys and compliance teams can read and challenge.
Insurance: The XAI implementation pattern that works best in insurance is a layered approach: SHAP values for technical model documentation and regulatory submissions, with a natural language generation layer that converts SHAP output into plain-language customer notices. This approach — technical fidelity at the SHAP level, accessible communication at the customer notice level — is increasingly the standard architecture for compliant AI decisioning in insurance.
✅ 8. XAI Implementation Checklist for Organizations
The gap between understanding XAI conceptually and implementing it in a way that satisfies regulators, auditors, and customers is significant. The checklist below is structured for data and compliance teams beginning to implement explainability across their AI portfolio. It covers the full lifecycle from initial audit through ongoing monitoring, and maps to the requirements of the EU AI Act, GDPR Article 22, and SR 26-2. The right implementation order: identify the obligation → define the required explanation format → select the technique → implement and validate.
| # | Action | Why It Matters | Priority |
|---|---|---|---|
| 1 | Inventory all AI systems making high-stakes decisions in your organization | Cannot implement XAI for systems you haven’t mapped | 🔴 Critical |
| 2 | Classify each system by risk level — does it meet EU AI Act Annex III high-risk criteria? | High-risk classification triggers full Article 13 transparency obligations | 🔴 Critical |
| 3 | Define who needs the explanation (regulator, customer, clinician, lawyer) and in what format | XAI technique selection must match the audience and format requirement | 🔴 Critical |
| 4 | Select the appropriate XAI technique per model type: SHAP for tabular/tree models, attention visualization for LLMs, rule extraction for regulatory narratives | Wrong technique for the model type produces unreliable explanations | 🔴 Critical |
| 5 | Generate and store XAI outputs at the time of each high-stakes decision — not retroactively | Model drift makes retroactive explanation unreliable and legally problematic | 🔴 Critical |
| 6 | Integrate XAI outputs into model documentation: model cards, system cards, and technical documentation | EU AI Act Article 13 requires instructions for use to include output interpretation guidance | 🟠 High |
| 7 | Test explanation quality: do XAI outputs accurately reflect what the model actually does? Run sanity checks against known-outcome cases | Misleading explanations are worse than no explanations — they create false confidence | 🟠 High |
| 8 | Test explanation quality across demographic subgroups — equal explanation coverage across protected groups is required | A system producing lower-quality explanations for minority groups fails EU AI Act Article 10 fairness requirements | 🟠 High |
| 9 | Establish a documented process for generating explanations on demand for regulators, auditors, or customers | GDPR Article 22 and the Colorado AI Act require on-demand individual-level explanations | 🟠 High |
| 10 | Train decision-makers — clinicians, underwriters, HR managers — to interpret XAI outputs correctly | Article 14 human oversight requires that human reviewers can actually act on the explanation | 🟠 High |
| 11 | Include XAI capability requirements in AI vendor due diligence — before signing any contract for high-risk AI systems | Third-party AI vendors must satisfy your Article 13 obligations — not just their own product requirements | 🟠 High |
| 12 | Monitor SHAP value distributions over time — unexpected shifts in feature importance signal model drift; review XAI outputs for bias signals | XAI monitoring is an early-warning system for model degradation; SHAP global feature importance is a primary bias detection mechanism | 🟡 Medium |
📊 9. XAI Technique Selection Guide — Choosing the Right Method
| Technique | Best Model Type | Best Audience | Speed | Best For |
|---|---|---|---|---|
| LIME | Any (model-agnostic) | Customers, non-technical stakeholders | ✅ Fast (100–500ms) | Individual prediction explanation, early exploration |
| SHAP (Kernel) | Any (model-agnostic) | Data scientists, auditors, regulators | ⚠️ Slower (1–5s) | Audit documentation, bias detection, model debugging |
| SHAP (Tree) | XGBoost, LightGBM, Random Forest | Data scientists, auditors, regulators | ✅ Fast (10–50ms) | Production credit/fraud/insurance decisions at scale |
| DALEX + fairmodels | Any (model-agnostic) | Compliance officers, regulators, data scientists | ⚠️ Medium | Fairness audits, demographic bias compliance, Ceteris Paribus clinical decision support |
| Attention Visualization | Transformer/LLM models | Clinicians, lawyers, NLP practitioners | ✅ Fast (native) | Document classification, clinical NLP, contract review |
| Rule Extraction | Any (surrogate model) | Regulators, executives, legal teams | ⚠️ Offline (batch) | Regulatory submissions, audit narrative, model governance docs |
| SHAP + Rule Extraction (combined) | Tabular models in regulated industries | Full compliance stack (technical + narrative) | ⚠️ Mixed | Banking (SR 26-2), insurance, healthcare compliance |
🏁 10. Conclusion — XAI Is Now an Organizational Capability, Not a Data Science Tool
In 2026, explainable AI is no longer a research area or an optional enhancement. It is a documented legal requirement for any organization deploying AI in high-stakes domains — employment, credit, healthcare, education, insurance, or law enforcement — in the EU, and increasingly in US jurisdictions with the Colorado AI Act and Federal Reserve SR 26-2 guidance adding formal teeth to what were previously guidelines. Organizations that treat XAI as a data science problem to be solved at the model level are missing the organizational requirement: XAI must be embedded in governance processes, vendor procurement, documentation standards, decision workflows, and staff training. The data science techniques — LIME, SHAP, DALEX, attention visualization, rule extraction — are the tools. The governance framework is the requirement.
The organizations that will navigate the 2026–2027 AI regulatory environment successfully are those building XAI as an organizational capability rather than a point solution. That means inventorying their AI systems now, classifying their regulatory obligations, selecting the right techniques for each model and audience, generating and storing explanations at decision time, and training the humans who rely on AI outputs to interpret those explanations meaningfully. The 12-step checklist in Section 8 is the starting point. The regulation is the deadline. The financial and reputational risk of getting it wrong — fines up to €35 million or 7% of global annual turnover under the EU AI Act — is the business case for acting now rather than waiting for a regulator to ask the first question. For the full AI governance framework, see our guide to AI Governance. For the human oversight architecture that makes XAI actionable in production, see our guide to Human-in-the-Loop AI.
📌 Key Takeaways
| ✅ | Takeaway |
|---|---|
| ✅ | EU AI Act Article 13 legally requires high-risk AI systems to be “sufficiently transparent to enable deployers to interpret a system’s output” — case-specific explanation mechanisms are required; general model descriptions do not satisfy this obligation. Penalties up to €35 million or 7% of global annual turnover apply for non-compliance. |
| ✅ | SHAP is the most compliant XAI technique for regulated tabular models — Tree SHAP runs in 10–50ms per explanation and produces consistent, reproducible feature attributions suitable for audit documentation and individual-level GDPR Article 22 responses. LIME’s 65–75% run-to-run consistency is a compliance risk for regulatory documentation without aggregation. |
| ✅ | LIME answers “what affected this decision?”, SHAP answers “by how much?”, and DALEX answers “what would change this decision?” — three structurally different questions serving different compliance audiences. The strongest XAI programs in 2026 use all three in different roles rather than choosing one exclusively. |
| ✅ | DALEX’s fairmodels package and IBM AIF360 (75+ fairness metrics, 10+ bias mitigation algorithms) address the demographic fairness dimension that general-purpose XAI tools treat as secondary — providing the demographic parity tests and equalized odds analysis that Colorado AI Act (February 2026) and EU AI Act Article 10 bias impact assessments require. |
| ✅ | XAI outputs must be generated and stored at the time of each high-stakes decision — retroactive explanation generation after model updates is technically unreliable and legally problematic under GDPR Article 22 and EU AI Act Article 13. This is the most frequently missed XAI implementation requirement. |
| ✅ | NIST MEASURE.2.5 requires assessed explainability and interpretability using appropriate methods — SHAP, LIME, and DALEX all satisfy this subcategory. The NIST AI 600-1 Generative AI Profile extends these requirements to LLM-based systems, requiring organizations to document how they address confabulation and explainability before deploying generative AI in high-stakes contexts. |
| ✅ | Microsoft InterpretML’s Explainable Boosting Machine (EBM) builds interpretability into the model architecture — achieving performance comparable to gradient boosted trees while remaining directly readable, eliminating the need for post-hoc SHAP or LIME explanation for compliant deployments where model architecture is flexible. |
| ✅ | The most effective XAI compliance architecture for regulated industries combines SHAP (technical, reproducible feature attribution) with rule extraction (human-readable IF-THEN narrative for regulators) — neither alone is sufficient for the full compliance stack required by SR 26-2 and EU AI Act Articles 13 and 14. |
| ✅ | XAI vendor due diligence is non-negotiable for high-risk AI procurement — third-party AI systems must satisfy your Article 13 obligations with case-specific, on-demand explanations. Include XAI capability requirements in every vendor evaluation before procurement. |
🔗 Related Articles
- 📖 EU AI Act Explained: A Beginner-Friendly Compliance Guide + Practical Checklist
- 📖 AI Model Cards Explained: How to Document an AI System for Transparency
- 📖 AI Governance Explained: How to Build an AI Policy Framework
- 📖 AI Risk Assessment 101: How to Evaluate AI Use Cases Before You Deploy Them
- 📖 Human-in-the-Loop AI Explained: How to Use AI Safely with Approval Gates
❓ Frequently Asked Questions: Explainable AI (XAI), LIME, SHAP, and Compliance
1. What is the difference between LIME and SHAP, and which should I use for compliance?
SHAP is generally the right choice for regulatory compliance — it produces consistent, reproducible, case-specific feature attributions grounded in game theory mathematics, making it more reliable for audit documentation than LIME. LIME is faster and more accessible for customer-facing explanations but generates local approximations that can vary across similar cases. For EU AI Act Article 13 documentation, use SHAP; for customer explanation interfaces, LIME is often sufficient. Our AI Model Risk Management guide covers how to embed both into formal model governance.
2. Does the EU AI Act require organizations to use a specific XAI technique like SHAP or LIME?
No — the EU AI Act does not prescribe specific XAI techniques. Article 13 requires that high-risk AI systems be “sufficiently transparent to enable deployers to interpret outputs and use them appropriately.” The choice of technique — SHAP, LIME, attention visualization, or rule extraction — is yours, as long as the output genuinely supports interpretation and human oversight as required by Article 14. See our full EU AI Act compliance guide for the complete transparency obligation framework.
3. What counts as a “high-risk AI system” for XAI compliance purposes under the EU AI Act?
High-risk AI systems are defined in EU AI Act Annex III and include AI used in employment and HR (CV screening, candidate ranking), credit scoring, healthcare diagnostic support, education, biometric identification, law enforcement, and critical infrastructure. If your AI system makes decisions affecting individuals in these domains, it likely qualifies as high-risk and triggers full Article 13 transparency and Article 14 human oversight requirements. Use our AI Vendor Due Diligence Checklist to evaluate whether your current tools satisfy these obligations.
4. Can I use SHAP with large language models (LLMs) like GPT or Claude?
Kernel SHAP can be applied to LLMs but is computationally expensive for long-context inputs. The more practical approach for LLM-based systems is attention visualization — which is native to transformer architectures and surfaces which input tokens the model weighted most heavily in generating its output. For document classification, contract review, and clinical NLP tasks, attention visualization is the primary XAI mechanism. For AI systems using RAG (retrieval-augmented generation), source attribution — showing which retrieved documents contributed to a response — is also an important complement to attention visualization.
5. What is the minimum XAI requirement for satisfying GDPR Article 22 for automated decisions?
GDPR Article 22 requires “meaningful information about the logic involved” in automated decisions that produce legal or similarly significant effects. In 2026, EU data protection authorities interpret “meaningful” as case-specific — a generic description of the model type is insufficient. The practical minimum is an individual-level explanation naming the specific factors that influenced the decision for that specific individual and their relative weight. SHAP values converted to plain language (e.g., “your application was declined primarily due to your debt-to-income ratio of 48% and three credit inquiries in the past 90 days”) satisfy this standard more reliably than LIME outputs due to SHAP’s greater consistency across similar cases. Our AI Attribution and Explainability guide covers how to structure these responses.
📧 Get the AI Buzz Weekly Digest
Weekly AI insights, tools, and strategies — delivered every Monday. Free.
Leave a Reply