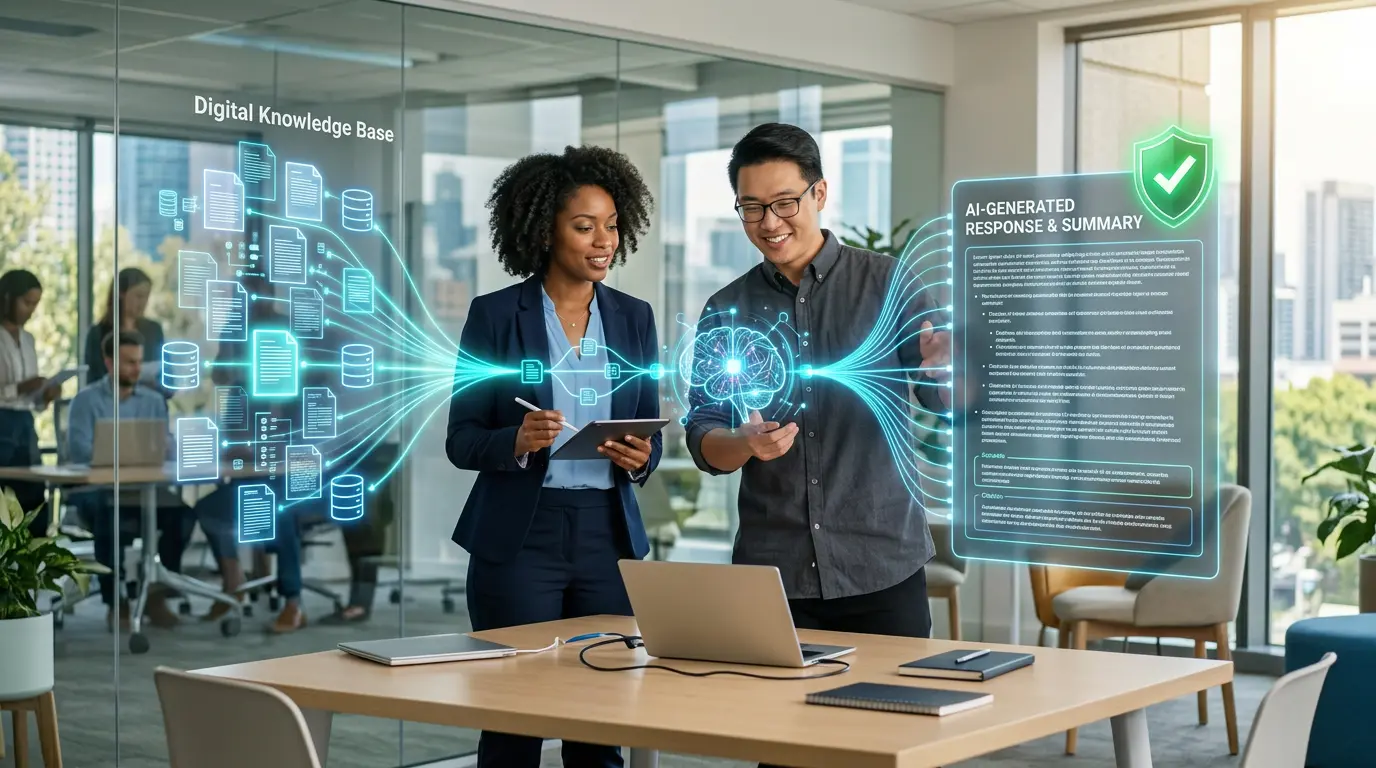
🔍 RAG reduces hallucinations by 70–90% and Microsoft reports $3.70 ROI for every $1 invested in RAG-enabled AI — yet most organizations are still building RAG pipelines without the security controls that make them safe to deploy with real data. This guide covers everything you need: plain-English RAG architecture, the best frameworks and tools in 2026, the RAG vs fine-tuning vs prompt engineering decision matrix, and the secure RAG checklist every production deployment needs before go-live.
Last Updated: October 10, 2026
When ChatGPT was released in late 2022, it immediately demonstrated a fundamental limitation: it could only answer questions based on its training data, which had a knowledge cutoff date and contained no knowledge of your organization’s proprietary information. You could not ask it about your company’s internal policies, the latest research papers, or events that happened last week. Retrieval-Augmented Generation (RAG) was developed specifically to solve this problem — and it has become the dominant architecture for enterprise AI in 2026 as a result. The global RAG market reached $3.33 billion in 2026, growing at a 42.7% compound annual rate toward a projected $81.51 billion by 2035. RAG framework adoption has surged 400% since 2024, and 60% of production LLM applications now use retrieval-augmented generation as their core architecture. Mordor Intelligence’s 2026 RAG market analysis confirms that regulated industries — healthcare, finance, legal, and government — are leading adoption precisely because RAG provides the explainability and source attribution that pure LLM generation cannot.
The core promise of RAG is compelling and delivers on its claims when properly implemented. RAG reduces hallucinations by 70–90% compared to pure LLM generation by grounding responses in retrieved source documents rather than relying solely on the model’s training memory. McKinsey’s AI research and the Mordor Intelligence analysis both cite Microsoft’s finding that organizations report $3.70 in value for every $1 invested in generative AI programs that embed retrieval pipelines — making RAG one of the most commercially validated AI architectures available. Organizations implementing RAG report 25–30% reductions in operational costs and 40% faster information discovery compared to traditional search. For enterprises dealing with confidential data, RAG also addresses the data privacy problem that pure cloud LLM deployment creates: rather than fine-tuning a model on sensitive data — which embeds that data permanently into model weights — RAG keeps your proprietary data in controlled storage and retrieves only what each query needs.
This upgraded guide covers RAG comprehensively for 2026. You will find a plain-English explanation of how RAG works with a step-by-step architecture walkthrough, the best RAG frameworks and tools compared across five dimensions, a decision matrix for when RAG is the right choice versus fine-tuning or prompt engineering, and the secure RAG pipeline checklist that identifies the security vulnerabilities most commonly exploited in production deployments. For the vector database layer that powers RAG retrieval, our guide to embeddings and vector databases covers the retrieval infrastructure in depth. For the full three-way comparison of RAG, fine-tuning, and domain-specific language models as strategic choices, our guide to Fine-Tuning vs RAG vs DSLMs covers the decision framework across more dimensions than the comparison table in this article. For the security-specific deep dive, our dedicated guide to Secure RAG for Beginners covers the OWASP LLM08 vulnerabilities and hardening checklist in full.
📖 New to AI terminology? Visit the AI Buzz AI Glossary — 100+ essential AI terms explained in plain English, each linking to a full in-depth guide.
🆚 RAG vs Standard LLM Responses: What Actually Changes
To understand why RAG matters, it helps to understand exactly what a standard LLM cannot do on its own — and what RAG adds at the moment a query is processed.
A standard LLM operates entirely from knowledge encoded in its weights during training. When training ends, the model’s knowledge freezes. Ask it about a regulation that was updated last month, a document your organization published last week, or a policy that changed last quarter — and it will either confess ignorance or, more dangerously, confidently hallucinate an answer based on patterns from its training data. This is not a flaw in the model’s reasoning — it is a structural limitation. The model was never given access to that information.
RAG changes this by connecting the LLM to an external knowledge base at inference time — at the moment a user submits a query, not at training time. When a query arrives, the RAG pipeline retrieves the most relevant documents from your knowledge store and includes them in the model’s context window alongside the original question. The model then generates a response grounded in those retrieved documents. It can read them, reason about them, synthesize across them, and cite them as sources. The model’s reasoning capability is unchanged — what changes is that it now has relevant, current, specific information to reason about.
Why do hallucination rates drop so dramatically (70–90% in well-implemented RAG)? Because the model has actual source material to work from rather than relying on patterns in its training memory. When a retrieved document contains the answer, the model quotes and cites it rather than fabricating one. When no retrieved document addresses the query, a well-designed RAG system is instructed to say so — rather than confidently inventing an answer. The hallucination risk does not disappear entirely (the model can still misread, misinterpret, or synthesize incorrectly across retrieved chunks), but the primary hallucination driver — generation without grounding — is directly addressed.
Analogy for beginners: A standard LLM is like a very well-read expert who finished reading in 2024 and has been in isolation since. RAG gives that expert access to a live library — they can look things up before answering. The quality of the answer depends on both the expert’s reasoning AND the quality of the library.
The table below shows how the major 2026 AI models support RAG — and what that means in practice for teams evaluating their architecture options.
| AI Model | RAG Support | Native Knowledge Cutoff | Beginner Note |
|---|---|---|---|
| Claude Sonnet 4.5 | ✅ Via API | Early 2024 | Best for document Q&A; strong at reading and citing long retrieved passages |
| GPT-5.x | ✅ Native + API | Early 2024 | ChatGPT Plus supports file upload RAG; API supports full custom RAG pipeline integration |
| Gemini 3.1 Pro | ✅ Google Search grounding | Real-time | Built-in retrieval via Google Search grounding; Vertex AI Search provides enterprise document RAG |
| Llama 4 | ✅ Via custom pipeline | Early 2024 | Open source — self-hosted RAG keeps all data on your infrastructure; no data leaves your environment |
| DeepSeek V4 Pro | ✅ Via API | Early 2024 | Cost-effective for high-volume RAG workloads; evaluate data residency requirements before deployment |
1. 🤔 What Is RAG? The Plain-English Explanation
The best analogy for understanding RAG is the open-book exam versus the closed-book exam. A standard LLM operates like a student taking a closed-book exam — it can only answer based on what it memorized during training. RAG operates like a student taking an open-book exam — it can look up relevant passages in a reference library before formulating its answer. The student’s intelligence (the LLM’s reasoning capability) combines with authoritative source material (your retrieval corpus) to produce an answer that is more accurate, more current, and more grounded than either alone could produce.
More precisely: RAG is an architecture that enhances an LLM by connecting it to an external knowledge source at query time. When a user asks a question, the RAG system retrieves the most relevant documents from a knowledge store and includes them in the LLM’s context alongside the original question. The LLM then generates a response informed by both its trained knowledge and the retrieved content — and can cite the retrieved documents as sources. The result is an AI system that can answer questions about your proprietary documents, the latest news, or any other information that did not exist when the model was trained, while still leveraging the LLM’s language understanding and reasoning capabilities.
The RAG Architecture: Step-by-Step Walkthrough
Understanding RAG requires understanding its five-stage pipeline — the sequence of operations that transforms a user query into a grounded, source-attributed response. Each stage is distinct, can be optimized independently, and has its own failure modes that contribute to RAG quality issues.
Stage 1: Document Ingestion and Preprocessing. Before any user query can be answered, the knowledge source must be prepared. Documents — PDFs, Word files, web pages, database records, Slack messages, SharePoint pages — are loaded, cleaned, and split into chunks. Chunking strategy is one of the most consequential RAG design decisions: chunks that are too small lose context; chunks that are too large dilute relevance. The standard approach is 256–512 token chunks with 10–20% overlap between adjacent chunks to preserve context at boundaries. Metadata — document title, source, date, section, author — is attached to each chunk for later filtering. Naive chunking that ignores document structure (splitting mid-sentence, mid-table, or mid-code block) is identified as the cause of 80% of RAG quality failures in 2026 practitioner research.
Stage 2: Embedding Generation. Each chunk is converted into a vector embedding — a dense numerical representation that captures the semantic meaning of the text. Semantically similar chunks produce numerically similar embeddings, which is what enables similarity search in Stage 4. The embedding model is separate from the LLM that generates responses: common choices include OpenAI’s text-embedding-3-small, Cohere’s embed-v4, or open-weight models like BGE-large or E5-mistral for self-hosted deployments. Embedding model choice affects retrieval quality, cost, and latency — with open-weight models offering data privacy advantages for sensitive corpora.
Stage 3: Vector Storage and Indexing. The chunk embeddings and their associated metadata are stored in a vector database — a specialized data store optimized for fast similarity search across high-dimensional vectors. Popular options include Pinecone, Weaviate, Qdrant, and pgvector (for PostgreSQL-based deployments). The vector index enables approximate nearest-neighbor search, finding the K most similar embeddings to any query embedding in milliseconds across corpora containing millions of chunks. Hybrid search — combining vector similarity with keyword-based BM25 search — consistently outperforms pure vector search by catching exact-match queries that vector embeddings sometimes miss.
Stage 4: Retrieval. When a user submits a query, the same embedding model converts the query text into a query embedding. The vector database finds the K chunks with the highest embedding similarity to the query embedding and returns them as candidate context documents. Retrieval quality is the most critical determinant of RAG output quality — LlamaIndex benchmarks place its retrieval accuracy at approximately 92% versus LangChain’s approximately 85% for comparable tasks, a gap that compounds at scale. Re-ranking — passing the initial retrieval candidates through a cross-encoder model that scores each candidate’s actual relevance to the query — significantly improves the precision of the final context set.
Stage 5: Generation with Augmented Context. The retrieved chunks are assembled into a prompt alongside the user’s original query and submitted to the LLM. A typical prompt structure places system instructions first, retrieved context next (with source attribution embedded), and the user query last. The LLM generates a response grounded in the retrieved content — and can be prompted to cite its sources, express uncertainty when retrieved context is incomplete, and refuse to answer when retrieved content does not address the query rather than hallucinating from training memory. The response and its source citations are returned to the user.
The single most important RAG design insight: The LLM cannot retrieve better information than the retrieval stage provides. Every quality problem in RAG output ultimately traces back to one of two places: the data you fed in (chunk quality, document selection, metadata completeness), or the retrieval strategy (embedding model, chunking, re-ranking, hybrid search). The LLM generation stage is rarely the bottleneck in a RAG system. Fix the pipeline before blaming the model.
⚠️ When RAG Gets It Wrong: Retrieval Failures and Hallucination Risks
RAG dramatically improves AI accuracy — but it does not make AI infallible. Understanding where RAG fails is as important as understanding what it enables, because the failure modes are specific and often invisible to users who assume that a cited answer is necessarily a correct one.
The 70–90% hallucination reduction that well-implemented RAG delivers is real — but the phrase “well-implemented” carries significant weight. Poorly chunked documents, vague queries, outdated knowledge bases, and synthesis errors across multiple retrieved chunks can all produce confident, plausible, wrong answers with source citations attached. A citation is evidence that the model retrieved something — it is not evidence that the answer is correct.
Always verify RAG-generated answers against the source document before acting on them — especially for legal, medical, or financial information. If the cited source does not support the claim in the RAG output, the system has either retrieved the wrong chunk, misread the retrieved content, or synthesized an answer that goes beyond what the sources actually say.
The four main RAG failure modes — and how to identify and address each — are mapped in the table below.
| Failure Mode | What Causes It | How to Spot It | What to Do |
|---|---|---|---|
| Wrong chunk retrieved | Poor embedding quality or vague query | Answer is plausible but off-topic; source citation is from an unrelated document section | Rephrase query to be more specific; review embedding model quality; check source citation directly |
| Context window overflow | Document too long for chunk size; too many chunks retrieved simultaneously | Answer cuts off mid-thought or contradicts itself within the same response | Reduce chunk size; reduce K (number of retrieved chunks); use hierarchical retrieval |
| Synthesis hallucination | Model fills gaps between retrieved chunks using training memory rather than retrieved content | A specific claim in the output has no matching source citation; the cited source does not contain the stated information | Require citation for every factual claim in the system prompt; instruct the model to say “the documents do not address this” rather than synthesizing |
| Stale knowledge base | Retrieved document has not been updated since the underlying information changed | Date on source document is older than the decision or regulation being referenced; answer contradicts known recent developments | Audit knowledge base freshness quarterly; attach last-updated metadata to every chunk; surface document date in responses |
RAG does not make AI truthful — it makes AI better informed. A RAG system that retrieves the wrong document will produce a confidently wrong answer. Always treat RAG outputs as a first draft requiring verification, not a final source of truth.
2. 🛠️ Best RAG Frameworks and Tools in 2026
The RAG framework landscape has matured significantly in 2026, and framework selection is now recognized as a strategic decision rather than a purely technical one. AlphaCorp’s 2026 RAG framework analysis identifies the key selection principle: start with your problem shape, not the framework’s popularity. Many production teams use LlamaIndex for ingestion and retrieval alongside LangChain for orchestration — the frameworks are complementary rather than mutually exclusive, and the most sophisticated enterprise deployments deliberately combine them. The table and profiles below cover the leading frameworks across every major use case category.
LangChain is the most widely adopted RAG and LLM application framework — the Swiss Army knife of the ecosystem. Its strength is orchestration and ecosystem breadth: 50,000+ integrations covering virtually every LLM provider, vector database, embedding model, and data source available. LangChain’s LCEL (LangChain Expression Language) enables composable chain construction, and LangGraph (its agentic extension) handles stateful multi-step reasoning workflows. The trade-off is complexity: a 2–3 week onboarding curve for teams new to the framework, and higher token overhead (~2.40K average tokens per query versus Haystack’s ~1.57K in comparative benchmarks). Best for teams building complex agentic workflows where retrieval is one capability among many.
LlamaIndex is the retrieval-specialist framework — purpose-built for the ingestion, indexing, and querying of complex document corpora. Its 150+ data connectors cover SharePoint, Slack, Notion, Google Drive, PDFs, databases, and essentially every location where enterprise knowledge lives. LlamaIndex’s multiple index types (vector, keyword, tree, knowledge graph) let teams match index strategy to data shape. Third-party benchmarks place LlamaIndex retrieval accuracy at approximately 92% versus LangChain’s 85% — a gap that compounds in high-volume deployments. The onboarding curve is 2–3 days for a basic RAG system. Best for teams whose primary requirement is accurate retrieval from large, complex document collections rather than complex orchestration logic.
Haystack is the enterprise governance framework — designed for regulated industries where pipelines must be auditable, testable, and maintainable under compliance scrutiny. Its modular component architecture (typed, reusable @component decorators with explicit I/O contracts) makes every pipeline step inspectable and replaceable. The lowest token overhead in comparative benchmarks (~1.57K average), first-class per-step instrumentation, and enterprise support from deepset make it the strongest choice for finance, healthcare, legal, and government deployments. The trade-off is the steepest upfront design investment — Haystack’s explicit pipeline architecture requires more initial configuration than LangChain’s rapid-prototyping-friendly defaults.
Vertex AI Search (Google Cloud) is the zero-ops managed RAG service for Google Cloud users. It bundles document ingestion, chunking, embedding, vector storage, retrieval, and generation into a single managed pipeline — no infrastructure to configure or maintain. Gemini models are natively integrated. Data residency controls satisfy GDPR requirements for EU deployments. The trade-off is the least pipeline control of any option: Vertex AI Search abstracts the retrieval mechanics away, making debugging and customization harder than open-source frameworks. Best for organizations whose data already lives in Google Cloud and whose engineering teams lack dedicated ML engineering capacity for a self-hosted pipeline.
Azure AI Search is the equivalent zero-ops managed RAG service for Microsoft Azure users — the most mature cloud-native RAG platform given Microsoft’s extensive enterprise customer base and its deep integration with OpenAI models via Azure OpenAI Service. Azure AI Search provides semantic ranking, integrated vectorization, a comprehensive built-in security model satisfying enterprise compliance requirements, and native integration with Azure’s broader data ecosystem (Azure Data Factory, Azure SQL, SharePoint Online). For organizations already committed to the Microsoft Azure stack, Azure AI Search offers the fastest path from enterprise data to RAG-powered application with the least infrastructure overhead.
| Framework / Tool | Best For | Ease of Use | Cost | Notable Feature (2026) |
|---|---|---|---|---|
| LangChain | Complex agentic workflows; teams needing maximum integration flexibility | ⭐⭐⭐ Moderate (2–3 week ramp) | Free (MIT); LangSmith observability from $39/mo | 50K+ integrations; LangGraph for agentic workflows; LangSmith for production tracing |
| LlamaIndex | High-accuracy document retrieval from large, complex corpora; knowledge base Q&A | ⭐⭐⭐⭐ Easy (2–3 days to basic RAG) | Free (MIT); LlamaCloud managed service from $97/mo | ~92% retrieval accuracy; 150+ data connectors; multiple index types; query routing |
| Haystack | Regulated industries (finance, health, legal, government); audit-ready pipelines | ⭐⭐⭐ Moderate (1 week; requires pipeline design thinking) | Free (Apache 2.0); deepset Cloud from $99/mo | Lowest token overhead (~1.57K/query); inspectable component pipelines; enterprise support from deepset |
| Vertex AI Search | Google Cloud orgs wanting zero-ops managed RAG with Gemini integration | ⭐⭐⭐⭐⭐ Very easy (no infra management) | Pay-per-query; ~$2.50/1K queries at standard tier; enterprise pricing available | Fully managed ingestion-to-generation pipeline; native Gemini; GDPR data residency controls |
| Azure AI Search | Microsoft Azure orgs; GPT-5.x integration; enterprise compliance (HIPAA, SOC 2, ISO 27001) | ⭐⭐⭐⭐⭐ Very easy (within Azure stack) | From $245.74/mo (S1 tier); scales with index size and query volume | Semantic ranking; integrated vectorization; native Azure OpenAI; comprehensive built-in security model |
3. 📊 RAG vs Fine-Tuning vs Prompt Engineering: When to Use Each
The most important strategic question when building an AI application that needs specific knowledge or behavior is not “how do I build a RAG pipeline?” — it is “is RAG even the right approach for this problem?” RAG, fine-tuning, and prompt engineering are three distinct tools that address three different knowledge and behavior challenges. Choosing the wrong one wastes time, money, and engineering resources. The decision matrix below maps specific use case characteristics to the approach that best addresses them.
Before the decision matrix, a brief orientation on what each approach actually does. Prompt engineering shapes LLM behavior through carefully crafted instructions, examples, and context in the input prompt — no model changes, no external knowledge required. It is the fastest, cheapest approach and the correct starting point for most teams. RAG connects an LLM to an external knowledge source at query time — giving it access to information that is not in its training data without modifying the model’s weights. It is the right approach when the primary challenge is knowledge: having access to specific, current, or private information. Fine-tuning modifies the LLM’s weights by continuing its training on a domain-specific dataset — changing the model’s internal knowledge, writing style, or behavioral patterns. It is the right approach when the primary challenge is style, format, behavior, or deep domain fluency that prompt engineering cannot achieve.
| Use Case / Requirement | Best Approach | Why | When to Add the Other Approaches |
|---|---|---|---|
| Answering questions about your internal documents and knowledge base | ✅ RAG | The knowledge does not exist in the model’s training data; it is private and changes over time; source attribution is required | Add prompt engineering to improve response format; add fine-tuning only if the document domain requires terminology the base model does not understand |
| Answering questions about current events or real-time data | ✅ RAG | The model’s training data has a cutoff date; the information changes faster than any retraining cycle could address | Consider function calling or tool use as an alternative to RAG for truly real-time data (APIs, live feeds) |
| Teaching the model a specific writing style, brand voice, or output format | ✅ Fine-tuning (or few-shot prompt engineering) | Style and format are behavioral properties encoded in weights, not knowledge in documents; few-shot examples in the prompt are the fast first attempt; fine-tuning is the robust solution when prompt engineering is insufficient | Add RAG if the styled output also needs to reference specific documents or current information |
| Building a domain-expert assistant (medical, legal, financial) | ✅ RAG + fine-tuning combined | RAG provides access to current, specific knowledge (patient records, case files, regulations); fine-tuning provides the base model fluency in domain terminology and reasoning patterns that the general model lacks | Start with RAG-only; add fine-tuning when the model’s terminology comprehension or reasoning patterns in the domain are producing errors that better documents cannot fix |
| Customer service chatbot that needs company-specific knowledge | ✅ RAG + prompt engineering | Product knowledge, policies, and FAQs belong in a retrieval corpus — they change frequently and must be attributable; tone and persona belong in the system prompt | Consider fine-tuning on successful resolved conversations only if prompt engineering cannot achieve the target tone consistency |
| Reducing hallucinations on factual tasks | ✅ RAG | RAG reduces hallucinations by 70–90% by grounding responses in retrieved source material; fine-tuning does not reliably reduce hallucination and can introduce new failure modes | Combine with self-reflective RAG (model evaluates retrieved content before generating) for the lowest hallucination rates |
| Keeping training data private and avoiding weight embedding of sensitive data | ✅ RAG | Fine-tuning embeds data permanently into model weights — raising data extraction risk and regulatory concerns for PII, PHI, and confidential IP; RAG keeps data in controlled storage under existing access controls | Ensure the retrieval infrastructure itself is secured — RAG moves the data risk from the model to the vector database and retrieval pipeline |
| Simple, well-defined task within the model’s existing capabilities | ✅ Prompt engineering | RAG and fine-tuning add complexity and cost; if the base model with a well-crafted system prompt delivers acceptable quality, do not over-engineer | Add RAG when the task requires information the model does not have; add fine-tuning when style/behavior cannot be achieved through prompting alone |
The RAG vs fine-tuning decision rule that saves months of misaligned engineering work: If the problem is “the model doesn’t know this information,” the answer is almost always RAG. If the problem is “the model doesn’t behave this way,” the answer is fine-tuning or prompt engineering. These are different problems with different solutions — and treating them as the same question produces solutions that address neither effectively.
🔒 Building an AI governance framework? Browse the AI Buzz Governance & Security Hub — 30+ in-depth guides covering OWASP, NIST, ISO 42001, AI risk management, and enterprise AI security frameworks.
🏢 RAG in Practice: 2026 Business Use Cases by Industry
RAG is not an abstract architectural pattern — it is a production technology deployed across every major industry to solve specific, high-stakes information retrieval problems. The use cases below represent the most mature and commercially validated RAG deployments as of October 2026, along with the regulatory context that shapes how each industry must implement its retrieval infrastructure.
The privacy surface in RAG is industry-specific but universally important: any RAG knowledge base that contains personal data must be governed under applicable data protection law. For EU deployments, GDPR Article 5’s data minimisation principle applies directly to the retrieval layer — only the personal data necessary for each specific query should ever be retrieved and included in the model’s context. For a comprehensive framework governing AI and personal data across the full data lifecycle, our guide to AI and data privacy covers the GDPR, CCPA, and HIPAA obligations that apply to RAG knowledge bases in detail. For regulated industries where the retrieval infrastructure itself must be protected from infrastructure-level exposure — particularly healthcare and financial services — confidential computing provides the Trusted Execution Environment (TEE) architecture that enables RAG retrieval to run inside hardware-isolated enclaves, preventing even cloud infrastructure operators from accessing query content or retrieved documents. For building the broader AI governance framework that RAG deployments sit within, our AI Governance guide covers the policy, risk, and compliance foundation every enterprise RAG program needs.
| Industry | RAG Use Case | Knowledge Base Source | Key Compliance Consideration |
|---|---|---|---|
| Legal | Contract review and clause extraction; case law research; due diligence Q&A | Internal contract library; case law databases; regulatory filings | ⚠️ Legal professional privilege — knowledge base access controls are mandatory; attorney-client privileged documents must be isolated from general retrieval corpus |
| Healthcare | Clinical decision support; drug interaction checking; patient record summarisation | Medical literature; clinical guidelines; formularies; patient records (PHI) | ⚠️ HIPAA BAA required with every vendor that processes PHI in the retrieval pipeline — including the embedding model provider, vector database, and LLM provider |
| Financial Services | Regulatory Q&A for compliance teams; policy interpretation; audit trail generation | Regulatory text; internal policy library; supervisory guidance (SR letters) | ⚠️ SR 26-2 documentation requirements apply — AI systems used in regulated decisions must have documented retrieval sources and human oversight mechanisms |
| HR / People Teams | Employee policy Q&A; benefits explanation; onboarding assistance | Employee handbook; HR policies; benefits documentation | ⚠️ GDPR Article 5 data minimisation — only retrieve personal data fields strictly necessary for the query; employee personal data in the knowledge base requires DPA with all processing vendors |
| Customer Support | Product and FAQ Q&A; troubleshooting guide retrieval; ticket deflection | Product documentation; support ticket history; FAQ library | ⚠️ CCPA — PII in historical support tickets requires explicit access controls at the retrieval layer; customer data must not be retrievable by agents serving other customers |
Across all five industries, the compliance pattern is consistent: the regulatory obligation sits with the deploying organization, not the RAG framework or the LLM provider. Building a RAG pipeline on a compliant framework does not make the deployment compliant — the knowledge base governance, vendor agreements, access controls, and audit logging must all be implemented explicitly. For the complete vendor due diligence framework that covers RAG infrastructure providers across security, compliance, and data handling dimensions, the AI audit checklist provides the 50-question evaluation framework and 100-point vendor scorecard your organization needs before any production RAG deployment.
4. 🔒 Secure RAG: How to Build a Safe RAG Pipeline
RAG pipelines introduce security risks that standard LLM deployments do not have — because RAG connects an AI model to your organization’s actual data, gives it the ability to retrieve and include that data in responses, and creates attack surfaces at every stage of the pipeline. The most dangerous RAG security failure mode is treating the retrieval pipeline as a data access layer without the same security controls you would apply to any other data access layer. Organizations that deploy RAG without explicit security architecture are not just creating AI quality risks — they are creating data access, data leakage, and compliance risks that affect their entire data estate.
Indirect Prompt Injection Through Retrieved Content. The most severe RAG-specific security vulnerability is indirect prompt injection: an attacker embeds malicious instructions in a document in your retrieval corpus, your RAG system retrieves it in response to a legitimate query, and the LLM executes the embedded instructions as if they were legitimate system commands. Unlike direct prompt injection (which requires the attacker to interact with your system directly), indirect prompt injection can be delivered through any content your RAG pipeline retrieves — a malicious website your system scrapes, a poisoned document uploaded by an attacker who has write access to your knowledge base, or a manipulated public document your pipeline indexes. OWASP’s LLM08 (Vector and Embedding Weaknesses) specifically addresses this attack vector. Our dedicated guide to Secure RAG for Beginners covers the full OWASP LLM08 vulnerability taxonomy, the attack patterns, and the mitigation controls that the OWASP foundation recommends for production RAG deployments.
Data Leakage Through Cross-Tenant Retrieval. In multi-tenant RAG deployments — where multiple users or organizations share the same vector database — improper access control at the retrieval layer can allow User A to retrieve documents that belong to User B’s corpus. Unlike traditional database access control where row-level security is well-understood and widely implemented, vector database access control is a newer problem that many organizations have not fully solved. The technical control is metadata filtering: embedding tenant ID and access level into chunk metadata and applying hard filters at retrieval time before returning candidates to the LLM. Any RAG deployment where users have different document access rights must implement metadata-level access control at the retrieval stage — not just at the application level.
Sensitive Data in Embeddings. Embedding models convert text to vectors — but those vectors encode semantic information about the source text in ways that can be partially reversed through inversion attacks. Medical diagnoses, financial records, or other sensitive PII embedded into a shared vector store represent a data exposure risk even if the source documents are never directly returned. For highly sensitive data, consider whether embedding that data in a shared vector store is appropriate, or whether it should be handled through encrypted, isolated storage with stricter access controls than a general-purpose vector database provides.
The Secure RAG Checklist Before Production Deployment:
☐ Input validation and sanitization: Sanitize user queries before embedding; reject or escape inputs containing common injection patterns (system prompt overrides, role-switching instructions, jailbreak patterns).
☐ Metadata-level access control: Every chunk in the vector database carries access control metadata (user ID, role, tenant, classification level); apply hard filters at retrieval time — never post-retrieval.
☐ Source content validation: Validate the integrity of documents entering the ingestion pipeline; flag unexpected sources, unusual embedding drift, or content that was not in the original approved corpus.
☐ Output filtering: Apply a safety layer to RAG outputs before returning to users; screen for PII leakage, sensitive document verbatim reproduction, and embedded instruction execution.
☐ Immutable audit logging: Log every retrieval event — what query was submitted, what chunks were retrieved, from which documents, with what access context — for compliance, debugging, and incident investigation.
☐ Knowledge base write access controls: Apply least-privilege controls to who can add, modify, or delete documents in the retrieval corpus; treat corpus poisoning as a real attack vector.
☐ Data classification alignment: Confirm that the security classification of documents in your corpus matches the security controls of your vector database and retrieval infrastructure; do not store classified documents in unclassified infrastructure.
☐ GDPR and data residency compliance: For EU personal data in the retrieval corpus, confirm that the vector database, embedding model, and LLM all process data within compliant jurisdictions under appropriate data processing agreements.
🔧 Choosing the Right RAG Architecture: Naive vs Advanced vs Modular
Not all RAG implementations are architecturally equivalent. The term “RAG” covers a spectrum from a single-step retrieval pipeline you can prototype in an afternoon to a sophisticated modular system with query routing, re-ranking, federated knowledge bases, and hardware-level privacy protections. Choosing the wrong architecture tier creates two predictable failure patterns: teams that start with advanced RAG on a problem that naive RAG would solve waste weeks of engineering effort; teams that start with naive RAG on a problem that requires modular RAG spend months debugging failures that the architecture cannot fix.
The Bottleneck-First principle applies directly here: identify the specific failure your architecture needs to solve before choosing the architecture. If you do not yet have a specific failure to solve — because you have not yet shipped a RAG system — start with naive RAG. Get it working, measure its failure modes, and then add exactly the architectural complexity that addresses the specific bottleneck you have found.
For teams where knowledge base data spans multiple organizations or jurisdictions — where one party should not have access to another party’s documents even for retrieval purposes — federated RAG applies the same privacy-preserving principle as federated learning: each organization hosts its own knowledge base and retrieval infrastructure, with query results aggregated without any party’s raw documents ever leaving their controlled environment. This architecture is particularly relevant for healthcare consortia, multi-party legal engagements, and cross-border regulatory intelligence programs where data sovereignty requirements prevent centralized knowledge base consolidation.
| If Your Biggest Problem Is… | Best RAG Architecture | Why |
|---|---|---|
| Getting started quickly with a small, well-defined document set | Naive RAG | Single retrieval step, simple pipeline, minimal infrastructure — works well for basic Q&A on a curated corpus of under 10,000 documents |
| Answers missing context that spans multiple documents or sections | Advanced RAG with re-ranking | A cross-encoder re-ranker selects the highest-relevance chunks from the initial retrieval pool — significantly improves precision when the best answer requires synthesising across multiple sources |
| Knowledge base is very large, unstructured, or spans multiple topics | Modular RAG with query routing | A query router classifies the incoming question and sends it to the relevant sub-index only — reduces noise from irrelevant retrieval and improves both accuracy and latency at scale |
| Multiple organizations need to contribute to a shared knowledge base without exposing their data to each other | Federated RAG | Each party hosts its own knowledge base and retrieval node; query results are aggregated centrally without raw documents leaving any party’s controlled environment |
| Sensitive data must not be exposed to cloud infrastructure operators or third parties at the retrieval layer | TEE-protected RAG | Retrieval runs inside a Trusted Execution Environment — hardware-isolated enclave prevents even the cloud provider from accessing query content or retrieved documents |
| Every factual claim in the output must be traceable to a specific source passage | Advanced RAG with citation layer | Chunk IDs are mapped back to source documents and passage locations in the output — every claim is attributable and verifiable against the original source without manual searching |
For most teams deploying RAG for the first time: start with naive RAG on a small, well-curated knowledge base. Get your chunking strategy right, test retrieval quality on real queries, and only add architectural complexity when you have identified the specific failure mode that complexity solves. Every hour spent debugging a naive RAG pipeline teaches you something that makes the advanced architecture decision clearer.
5. 🏁 Conclusion: RAG Is Now the Default Architecture — Security and Data Quality Are What Differentiate Results
The RAG adoption story of 2026 is a story of mainstreaming: 60% of production LLM applications now use retrieval-augmented generation, framework adoption has surged 400% since 2024, and the $3.33 billion market is growing toward $81.51 billion by 2035. RAG has crossed from an advanced architectural pattern into the standard approach for any AI application that needs access to specific, current, or private knowledge. The decision is no longer whether to use RAG — it is which framework, which vector database, which embedding model, and which security controls to deploy with it.
The organizations generating the strongest RAG results share two characteristics that the market data consistently confirms. First, they invest in data quality before framework selection: 80% of RAG failures trace to poor chunking, inconsistent metadata, or inadequate document preprocessing — not to framework choice or model capability. Second, they treat the retrieval pipeline as a security surface from day one: indirect prompt injection, cross-tenant leakage, and corpus poisoning are documented attack vectors that require explicit architectural controls rather than afterthought security layers added after a production incident. The frameworks in this guide are ready. The vector databases are production-grade. The LLMs are capable. The variable that determines whether a RAG deployment succeeds is whether the organization treats data quality and pipeline security as first-class engineering requirements — not as operational details to address later.
📌 Key Takeaways
| Key Takeaway | |
|---|---|
| ✅ | RAG reduces hallucinations by 70–90% compared to pure LLM generation by grounding responses in retrieved source documents — and Microsoft reports $3.70 in value for every $1 invested in generative AI programs that embed retrieval pipelines, confirming it as the most commercially validated AI architecture in 2026. |
| ✅ | The global RAG market reached $3.33 billion in 2026, growing at 42.7% CAGR toward $81.51 billion by 2035 — with 60% of production LLM applications now using RAG and adoption surging 400% since 2024. RAG is no longer an advanced pattern; it is the default architecture for enterprise AI. |
| ✅ | 80% of RAG failures trace to data quality problems — naive chunking that splits context, duplicate content that confuses retrieval, and missing metadata that prevents filtering — not to framework choice or model capability. Fix the pipeline data quality before blaming the model. |
| ✅ | LlamaIndex leads on retrieval accuracy (~92% vs LangChain’s ~85%) and is the best starting point for pure RAG; LangChain leads on orchestration flexibility and ecosystem breadth for agentic applications; Haystack leads for regulated industries needing auditable, testable pipelines. Many production teams combine LlamaIndex for ingestion and LangChain for orchestration. |
| ✅ | The core RAG vs fine-tuning decision rule: if the problem is “the model doesn’t know this information,” use RAG. If the problem is “the model doesn’t behave this way,” use fine-tuning or prompt engineering. These are structurally different problems requiring structurally different solutions. |
| ✅ | Indirect prompt injection through retrieved content — where attackers embed malicious instructions in documents that your RAG system retrieves — is the most severe RAG-specific security vulnerability, classified as OWASP LLM08 (Vector and Embedding Weaknesses). Input sanitization, source content validation, and output filtering are the three primary mitigations. |
| ✅ | Multi-tenant RAG deployments require metadata-level access control at the retrieval stage — not just at the application layer — to prevent cross-tenant data leakage where User A retrieves documents that belong to User B’s corpus through vector similarity search. |
| ✅ | RAG keeps sensitive data in controlled storage under existing access controls — unlike fine-tuning, which embeds data permanently into model weights and raises data extraction and regulatory concerns for PII, PHI, and confidential IP. For privacy-sensitive deployments, RAG is the architecturally safer choice between the two. |
| ✅ | RAG reduces but does not eliminate hallucination — retrieval failure, chunk boundary problems, synthesis errors, and stale knowledge bases can all produce confident, wrong answers with source citations attached. Always verify RAG-generated answers against the cited source document before acting on them, particularly for legal, medical, or financial decisions. |
| ✅ | RAG knowledge bases containing personal data must be governed under applicable data protection law — GDPR Article 5’s data minimisation principle applies directly to the retrieval layer, requiring that only the personal data strictly necessary for each query is retrieved and included in model context. Compliance is the deploying organization’s responsibility, not the framework’s. |
🔗 Related Articles
- 📖 AI and Data Privacy: What Your AI Tools Are Doing With Your Data
- 📖 Confidential Computing Explained: How TEEs Protect AI Workloads
- 📖 Federated Learning Explained: How AI Learns Without Sharing Your Data
- 📖 What Is a Large Language Model? A Plain-English Guide
- 📖 AI Governance Explained: How to Build an AI Policy Framework
❓ Frequently Asked Questions: Retrieval-Augmented Generation (RAG) Explained
1. What is the difference between RAG and fine-tuning?
RAG connects an LLM to an external knowledge source at query time — solving the “model doesn’t know this information” problem. Fine-tuning modifies the model’s weights by training on new data — solving the “model doesn’t behave this way” problem. RAG is better for accessing private, current, or proprietary knowledge; fine-tuning is better for instilling writing styles, domain fluency, or behavioral patterns. RAG also keeps sensitive data in controlled storage rather than embedding it into model weights, making it the safer choice for PII and confidential IP. Our Fine-Tuning vs RAG vs DSLMs guide covers the full three-way decision framework.
2. How much does RAG reduce hallucinations?
Field studies record hallucination reductions of 70–90% when well-implemented RAG pipelines are introduced, according to Mordor Intelligence’s 2026 RAG market analysis citing the Makebot AI Research enterprise benchmarks. The actual reduction depends heavily on retrieval quality — naive chunking, poor metadata, and inadequate re-ranking all reduce the hallucination benefit. Self-reflective RAG configurations — where the model evaluates retrieved content before generating — achieve the lowest hallucination rates. Our AI hallucinations guide covers why hallucinations occur and the full spectrum of mitigation strategies.
3. Which RAG framework should I start with in 2026?
Start with LlamaIndex if your primary requirement is accurate retrieval from a document corpus — it has the simplest on-ramp (2–3 days to basic RAG) and the highest documented retrieval accuracy (~92%). Start with LangChain if you are building a complex agentic application where retrieval is one capability among many. Use Haystack if you are in a regulated industry where pipeline auditability is a compliance requirement. Use Azure AI Search or Vertex AI Search if your data already lives in the respective cloud ecosystem and you need a zero-ops managed solution. Our embeddings and vector databases guide covers the retrieval infrastructure that all these frameworks depend on.
4. What are the biggest security risks of RAG deployments?
Three security risks are specific to RAG and require explicit architectural controls: (1) Indirect prompt injection, where attackers embed malicious instructions in retrieved documents that the LLM then executes — classified as OWASP LLM08; (2) Cross-tenant data leakage in multi-tenant deployments, where inadequate access control at the retrieval layer allows users to retrieve documents from other tenants’ corpora; (3) Corpus poisoning, where write-access attackers inject malicious documents into the knowledge base to manipulate future retrievals. All three require architectural controls rather than application-level mitigations. Our Secure RAG for Beginners guide covers the OWASP LLM08 taxonomy and the full hardening checklist.
5. Can RAG work with any LLM or is it model-specific?
RAG is model-agnostic — the retrieval stage (document storage, embedding, similarity search) is completely independent of which LLM generates the final response. You can use RAG with GPT-5.5, Claude Opus 4.7, Gemini 3.1, Llama 4, Mistral, or any other LLM that accepts a text prompt. The embedding model used to convert documents and queries to vectors can also be different from the generation LLM. The only LLM-specific consideration is context window size — larger context windows allow more retrieved chunks to be included, which generally improves answer quality for complex multi-document questions. Models with 128K+ context windows provide significantly more headroom for retrieved context than earlier models with 8K limits.
📧 Get the AI Buzz Weekly Digest
Weekly AI insights, tools, and strategies — delivered every Monday. Free.
Leave a Reply