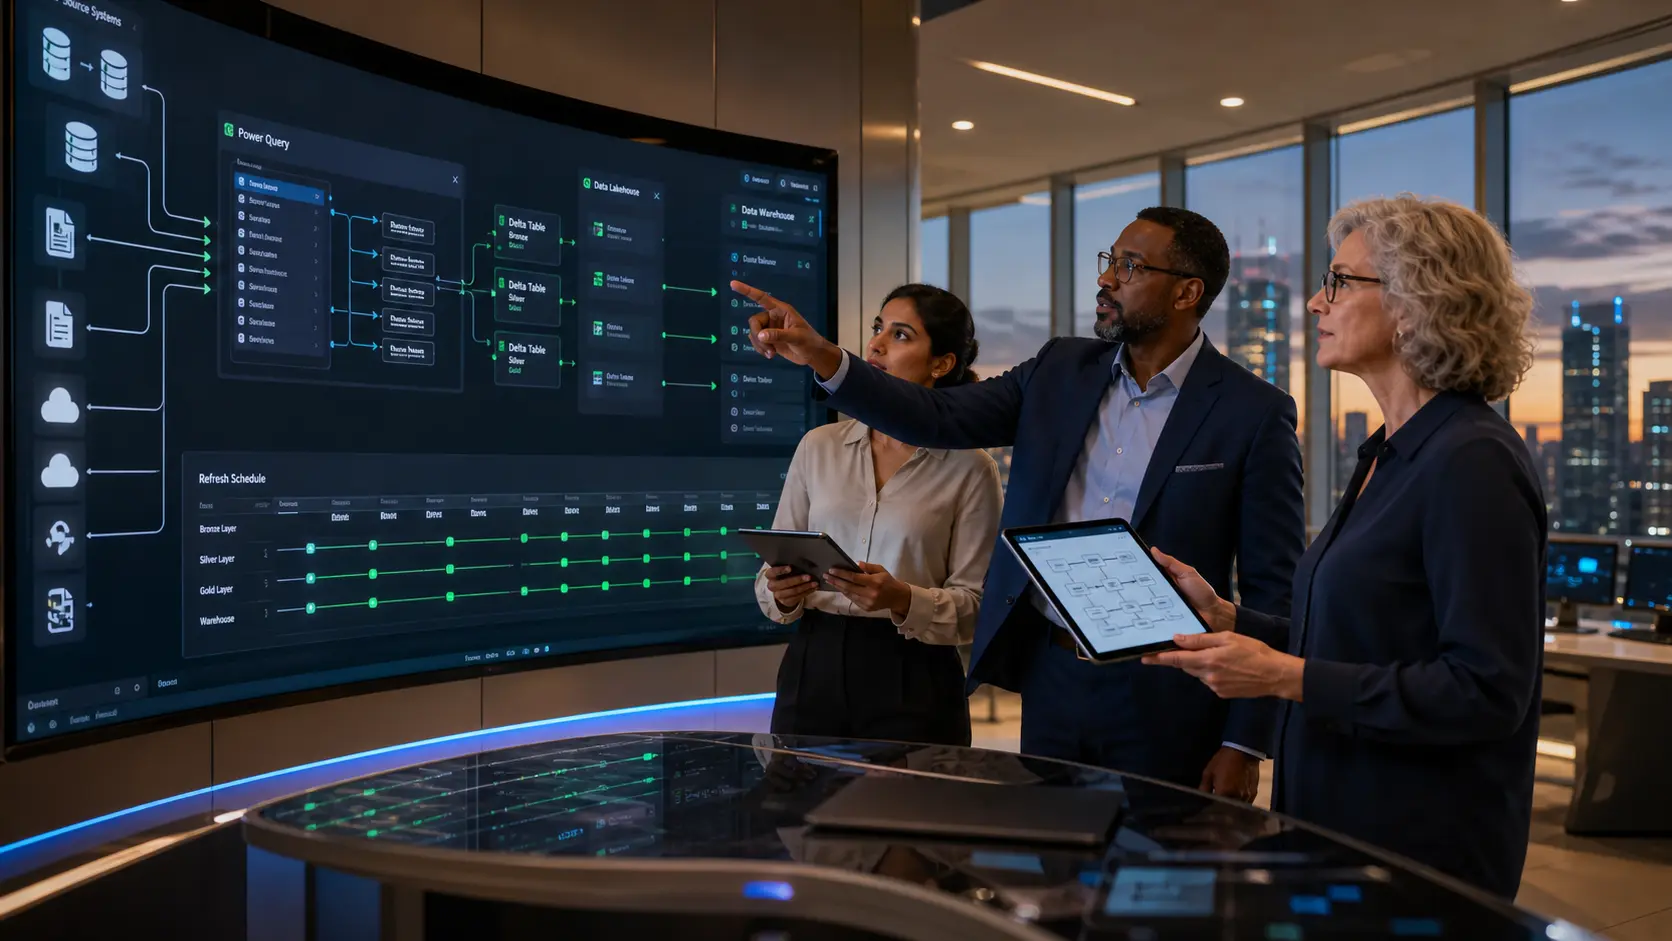
⚙️ Still copying the same Power Query steps into every report? Power BI Dataflows solve that problem — and in 2026, with Gen1 now in legacy status and Gen2 reshaping the platform, understanding which version to use and when could save your team hundreds of hours a year.
Last Updated: October 13, 2026
Power BI Dataflows are one of the most underused features in the entire Power BI ecosystem — and one of the most valuable. At their core, a dataflow is a reusable, cloud-based data preparation layer: you build your data transformation logic once, schedule it to refresh automatically, and connect as many reports and semantic models as you like. If you have ever found yourself rebuilding the same Power Query steps in three different .pbix files, or discovered that two dashboards show different numbers because they calculate “revenue” differently, Dataflows are the architectural fix you have been looking for. According to Microsoft Power BI, the platform now holds nearly 30% of the global BI market share — and Dataflows are a core reason enterprise teams stay inside the ecosystem rather than moving to separate ETL tooling.
In 2026, the Dataflows story has changed significantly. Microsoft officially moved Dataflow Gen1 into legacy status in April 2026, redirecting all future product investment to Dataflow Gen2 — a substantially more powerful version built on the Microsoft Fabric runtime. This is not just a naming update. Gen2 changes where your data lands, how fast it refreshes, and which teams can consume it. For organizations still running Gen1 in Pro workspaces, this shift raises real planning questions. For teams already on Fabric or Premium capacity, Gen2 opens up a data architecture that goes well beyond Power BI reporting. This guide explains exactly what Dataflows are, how Gen1 and Gen2 differ, when to use each, and how to decide whether your organization should migrate — with the real-world detail that generic documentation leaves out.
Whether you are a Power BI beginner trying to understand why your reports keep going out of sync, a BI developer evaluating whether to centralize your ETL layer, or a data team lead planning a Fabric migration in 2026, this article gives you everything you need. You will leave with a clear mental model of how Dataflows work, a practical comparison of Gen1 versus Gen2, specific use cases where Dataflows deliver the highest return, and the honest limitations that every guide forgets to mention. Organizations that implement centralized dataflow architectures consistently report a 40–60% reduction in dataset development time and a 70%+ reduction in data inconsistencies across reports — but only when they choose the right version and architecture for their environment.
📘 New to Power BI or data terminology? Before diving in, bookmark the AI Buzz Glossary — 100+ essential AI terms explained in plain English, including ETL, semantic models, lakehouses, and Delta tables.
🔍 1. What Are Power BI Dataflows? The Plain-English Explanation
A Power BI Dataflow is the Power Query element of Power BI running as a separate, cloud-based service. When you transform data inside Power BI Desktop — connecting to a source, cleaning columns, merging tables — that logic lives inside your .pbix file. It only runs on your machine, and nobody else can reuse it. A Dataflow takes that same Power Query logic and moves it to the Power BI Service, where it becomes shareable, schedulable, and completely independent of any individual user’s machine or installation.
Think of a Dataflow as a central kitchen for your organization’s data. Instead of every report author preparing their own raw ingredients from scratch — connecting directly to source systems, applying their own cleaning rules, calculating their own metrics — a Dataflow prepares a clean, governed batch of ingredients on a schedule, and every report simply serves from that shared supply. The result is consistent data, less redundant work, and a single place to fix a transformation error rather than hunting through twenty .pbix files.
Technically, a Dataflow executes Power Query M code in the cloud, connects to your data sources via an on-premises data gateway (for local sources) or directly (for cloud sources), applies your defined transformations, and writes the prepared output to storage — either internal Power BI storage, Azure Data Lake Storage, a Fabric Lakehouse, or a Fabric Warehouse, depending on which generation of Dataflows you are using. That output is then available to semantic models, other dataflows, Excel, notebooks, pipelines, and SQL-based consumers — making it a genuine shared data layer rather than just a report-level pre-processing step.
The problem Dataflows solve
The most common symptom that signals a team needs Dataflows is the “three numbers problem”: the CEO asks why the sales dashboard shows $4.2M for Q3, the finance report shows $4.05M, and the board deck shows $3.98M. Nobody can explain the discrepancy because each number was calculated by a different analyst, using slightly different transformation logic, buried inside a different .pbix file. Dataflows centralize that logic in one place with one definition, so every downstream consumer uses the same calculation every time.
A second symptom is refresh performance degradation. When multiple reports all query the same source system directly, your data gateway becomes a bottleneck and your source database takes a hammering during peak refresh windows. A Dataflow queries the source once, stores the prepared output, and all downstream semantic models refresh from that stored output — dramatically reducing gateway load and source system pressure. Organizations using this pattern typically report refresh times dropping from 35+ minutes to under 5 minutes for individual semantic models.
The third symptom is duplicated development effort. If three developers have independently built the logic to calculate “net revenue after returns” in three different reports, any change to that business rule — a new product category, an updated returns policy — requires three separate fixes, each with its own risk of introducing inconsistency. Dataflows eliminate this: the calculation lives in one place, maintained by one team, inherited automatically by all downstream consumers.
⚡ 2. Dataflow Gen1 vs Gen2: What Changed in 2026 and Why It Matters
The most important thing to understand about Dataflows in 2026 is that Microsoft has drawn a clear line in the road. In April 2026, Microsoft officially announced that Dataflow Gen1 had entered legacy status. Existing Gen1 dataflows continue to work — Microsoft has not set a retirement date — but all future product innovation, performance improvements, and new feature development is happening exclusively in Gen2. If you are starting anything new today, you should be building in Gen2. The question is whether your current licensing allows it.
The 2026 Dataflows Reality: Gen1 is in legacy status as of April 2026. Existing flows continue working, but Microsoft has confirmed that all future innovation belongs to Gen2. New dataflows should be built in Gen2 — subject to the Fabric or Premium capacity licensing requirement.
The differences between Gen1 and Gen2 go much deeper than a version number. They represent genuinely different architectural philosophies — Gen1 was designed to prepare data for Power BI workloads, while Gen2 is designed to prepare data for an entire data platform. Understanding these differences is essential before making any migration or architecture decisions.
Output destination: the most important difference
In Gen1, your transformed data always lands in one place: Azure Data Lake Storage, stored as CDM (Common Data Model) folders in CSV format. This is a Power BI-specific format that works well when your only consumer is a Power BI semantic model, but requires additional processing to be useful for anything else. In Gen2, you choose where the data lands. Current destination options include Fabric Lakehouse (stored as Delta tables in OneLake), Fabric Warehouse, Fabric Database, KQL Database for real-time scenarios, Azure SQL Database, and Snowflake (in preview). This destination flexibility is not a minor feature addition — it is a fundamental architectural change that turns Dataflows from a Power BI preparation tool into a shared data engineering layer usable by the entire organization.
The storage format change matters just as much as the destination flexibility. Gen1 stores data as CSV files in CDM folders — a row-based format that works but has significant performance limitations at scale. Gen2 stores data as Delta tables, which use columnar storage, built-in indexes, and transaction logs optimized for faster reads of selective columns, incremental updating, and sharing across Fabric and Power BI simultaneously. When a Gen2 Dataflow writes to a Fabric Lakehouse, Power BI can read that data via Direct Lake mode — meaning reports update without a separate dataset refresh step, reducing capacity consumption by 50–70% compared to import mode.
Licensing: the catch that catches most teams
Gen1 Dataflows are available in Power BI Pro workspaces ($10/user/month), making them accessible to virtually any Power BI team. Advanced Gen1 features — including the Enhanced Compute Engine, DirectQuery to dataflows, incremental refresh, and computed/linked entities — require Power BI Premium Per User (PPU at $20/user/month), Fabric capacity, or Power BI Premium capacity. Gen2 Dataflows require Fabric capacity or Power BI Premium capacity as a minimum — Pro and PPU alone are not sufficient. The minimum Fabric capacity is the F2 SKU at $262.80/month. If a Gen2 Dataflow is created and run inside a Fabric workspace assigned to your capacity SKU, there is no additional per-use charge — it is covered under the capacity cost.
| Feature | Dataflow Gen1 | Dataflow Gen2 (CI/CD) | Verdict |
|---|---|---|---|
| Minimum license | Power BI Pro ($10/user/mo) | Fabric / Premium (from $262.80/mo) | Gen1 wins on accessibility |
| Output storage | CDM folders (CSV) in ADLS Gen2 | Delta tables in OneLake / Lakehouse | Gen2 wins decisively |
| Destinations | Power BI storage only | Lakehouse, Warehouse, Azure SQL, Snowflake, KQL DB | Gen2 wins decisively |
| DirectQuery support | ✅ Yes (Premium/PPU) | ⚠️ Not yet available | Gen1 retains advantage here |
| Pipeline integration | ❌ No | ✅ Yes — orchestrate with Data Pipelines | Gen2 wins decisively |
| Git / CI/CD | ❌ No | ✅ Yes (Gen2 CI/CD variant) | Gen2 wins for dev teams |
| Copilot / AI assist | ⚠️ Limited | ✅ Full Copilot integration | Gen2 wins |
| Status | 🔴 Legacy (April 2026) | ✅ Active — all new investment | Gen2 is the future |
Gen2 CI/CD: the version you should always create
Within Gen2, there are two variants worth understanding. The standard Gen2 and the Gen2 CI/CD variant. As of April 2026, the option to create new Dataflow Gen2 items without CI/CD and Git integration support — previously known as Dataflow Gen2 Classic — is no longer available. All new Dataflow Gen2 items are now created with CI/CD and Git integration support by default. This is a significant improvement for enterprise teams: Git integration means your dataflow definitions can live in source control, deployments can be managed through DevOps pipelines, and parameter passing from external pipelines becomes possible — none of which existed in Gen1 or the earlier Gen2 Classic variant.
📋 3. When Should You Use Power BI Dataflows? 6 Scenarios That Justify Them
Dataflows are not always the right tool. For small teams building a single report from a clean data source, the added complexity of a separate ETL layer creates overhead without proportional benefit. But there are six specific scenarios where Dataflows deliver clear, measurable value — and recognizing them will help you make the architecture decision correctly the first time.
Scenario 1: Multiple reports using the same data source
If more than two reports in your organization connect to the same source system — whether that is Salesforce, SQL Server, SharePoint, or a REST API — a Dataflow is almost always the right call. Without one, every report author writes their own connection, their own transformations, and maintains their own refresh schedule. Your data gateway handles duplicate queries. Your source system absorbs duplicate load. And the moment a source schema changes, every report breaks independently. A Dataflow centralizes the connection and transformation into one maintainable unit, and all downstream consumers inherit the fix automatically when the source changes.
Scenario 2: Inconsistent business metrics across reports
When different teams define the same metric differently — “active customers,” “gross margin,” “hours worked” — the result is conflicting dashboards and eroding trust in your BI platform. Dataflows enforce a single definition by centralizing the calculation logic. Once “active customers” is defined in a Dataflow, every report that connects to it uses the same definition. Business logic changes happen in one place and propagate downstream automatically. This is the single most valuable governance benefit Dataflows provide, and it is the reason Microsoft’s Power BI documentation describes Dataflows as a “self-service data prep” layer for exactly this use case.
Scenario 3: Large datasets requiring incremental refresh
If your reports refresh slowly because they process large historical datasets in full on every cycle, Dataflows with incremental refresh can cut that time dramatically. Incremental refresh works by defining RangeStart and RangeEnd Power Query parameters that filter source data by a date column — only new or changed records are processed on each refresh cycle rather than the entire table. EPC Group’s implementation data across 150+ organizations shows incremental refresh reducing average enterprise Dataflow refresh times from 35 minutes to 4 minutes — an 88% reduction — while reducing source system query load by 90%. This feature requires Premium Per User, Fabric, or Premium capacity for both Gen1 and Gen2.
Scenario 4: Self-service data prep for non-technical teams
Dataflows use the same Power Query Online interface that millions of Excel and Power BI Desktop users already know — no SQL, no Python, no coding required. This makes them genuinely accessible to business analysts, finance teams, and operations staff who need to prepare their own data without IT involvement. The Gen2 version adds full Copilot integration, allowing users to create calculated columns, generate transformation steps, and explain existing M code using natural language prompts. For organizations pursuing data democratization, Dataflows are the practical mechanism that makes self-service data preparation governable rather than chaotic.
Scenario 5: Multi-team data sharing across the Fabric platform (Gen2 only)
For organizations on Microsoft Fabric, Gen2 Dataflows solve a data sharing problem that Gen1 cannot touch. When a Gen2 Dataflow writes to a Fabric Lakehouse, the transformed data is immediately available to Power BI semantic models via Direct Lake, to data scientists via Spark notebooks, to SQL analysts via the SQL Analytics Endpoint, and to downstream pipelines — all from the same Delta table, with no duplication. Gen1 dataflows can only serve Power BI semantic models and other dataflows via the dataflows connector. Gen2 turns the same transformation into a platform-wide data asset accessible to your entire data organization.
Scenario 6: Medallion architecture implementation
Organizations implementing a medallion data architecture — the Bronze/Silver/Gold layered pattern for organizing data pipelines — can use Dataflows to power each layer without writing custom code. Layer 1 Dataflows extract raw data from source systems (Bronze). Layer 2 Dataflows use linked entities to reference Layer 1 output and apply business transformation rules (Silver). Layer 3 Dataflows use computed entities to build final, consumption-ready metrics and aggregations (Gold). EPC Group reports this three-layer pattern reduces total processing time by 60–70% compared to embedding all transformation logic inside individual semantic models, while dramatically improving maintainability.
📊 Building your Power BI skills? Explore the full Power BI & Data Analytics Hub — practical guides on dashboards, DAX, data modelling, Microsoft Fabric, and AI-powered analytics for business teams.
🚫 4. When NOT to Use Power BI Dataflows: Honest Limitations
Every guide on Dataflows focuses on what they can do. This section covers what they cannot — because using the wrong tool for your situation creates more complexity, not less. Dataflows are the right answer for many teams, but they are genuinely the wrong answer for others, and the distinction matters before you build an architecture that becomes expensive to unwind.
Limitation 1: DirectQuery is not available in Gen2
If your reporting requirement is real-time data — dashboards that must reflect changes in the source system within seconds or minutes — Dataflows are the wrong architecture. Dataflows are a batch processing tool: they pull data, transform it, store it, and serve it until the next scheduled refresh. Gen1 Dataflows supported DirectQuery to dataflows (with Premium or PPU capacity), which allowed reports to query the dataflow output in near-real-time without a fixed refresh cycle. Gen2 does not currently offer this capability. Teams migrating from Gen1 to Gen2 who rely on DirectQuery need to plan carefully and validate that their refresh schedule can serve their latency requirements before committing to the migration.
Limitation 2: Gen2 requires Fabric or Premium — Pro teams are left behind
The most significant limitation in 2026 is licensing. Gen1 Dataflows run in Pro workspaces, making them available to the majority of Power BI teams on standard licensing. Gen2 requires Fabric capacity (minimum F2 at $262.80/month) or Power BI Premium capacity — costs that are a significant jump from a per-user Pro license. For small teams or organizations not yet on Fabric, the Gen1-to-Gen2 migration is a licensing decision as much as a technical one. Microsoft has acknowledged this friction and indicated plans to introduce new Gen2 paths for Pro and PPU scenarios, but as of October 2026, no general availability date has been confirmed. Teams on Pro licenses who need the most advanced Dataflow features are currently in a holding pattern.
Limitation 3: Two refresh layers to coordinate
Introducing a Dataflow creates a two-stage refresh dependency: the Dataflow must refresh successfully before the downstream semantic model can refresh. This adds operational complexity — you now have two refresh schedules to monitor, two failure points to handle, and a coordination problem that does not exist when Power Query runs inside the semantic model directly. For small environments with one or two reports, this overhead can outweigh the benefit of centralizing the transformation. The rule of thumb: if three or more reports share a data source, the coordination overhead is justified. If only one report uses a given source, embed the Power Query in the semantic model and skip the Dataflow entirely.
Limitation 4: Not a replacement for dedicated data engineering
Dataflows suit low-code data ingestion and transformation: they are Power Query in the cloud, and Power Query has real limits. They are not Spark notebooks. They cannot perform complex Python or R transformations, process streaming data at scale, or handle the kind of custom engineering logic that large data teams build in Azure Databricks or Synapse. For organizations where data engineering complexity matters more than self-service accessibility, Fabric notebooks or dedicated data engineering platforms are the better tool. Dataflows and notebooks are genuinely complementary — Dataflows for self-service and low-code scenarios, notebooks for heavier engineering requirements — but they should not be treated as interchangeable.
🗺️ 5. How to Decide: A Practical Dataflows Decision Framework
With the use cases and limitations clearly defined, the remaining question is how to apply this to your specific situation. The decision has three layers: whether to use Dataflows at all, which generation to use, and how to structure your Dataflow architecture once you commit. The framework below answers each layer in sequence.
Layer 1: Should you use Dataflows?
Start with this test: count how many separate .pbix files or semantic models connect to the same data source. If the answer is one, skip Dataflows — embed Power Query in the model. If the answer is two or more, Dataflows become worth evaluating. Then ask whether any of these scenarios apply: multiple reports must agree on a business metric definition; your refreshes are slow due to large historical datasets; analysts outside IT need self-service data preparation access; your organization is building a shared data platform across multiple teams and tools. If one or more applies, Dataflows are the right direction. If none applies and you have a single report environment, Power Query in the semantic model is simpler and equally effective.
Layer 2: Gen1 or Gen2?
The answer is almost always Gen2 if you have the licensing for it. Gen1 is in legacy status and will not receive new features. If you are starting anything new and your workspace is on Fabric capacity or Power BI Premium, build in Gen2. The one exception is if your architecture depends on DirectQuery to Dataflows — Gen1 retains that capability and Gen2 does not yet. If you are on a Pro license without plans to move to Fabric or Premium in the next 12 months, Gen1 remains your only option for now — build in Gen1 and plan for migration when your licensing situation changes.
| Your Situation | Use Dataflows? | Which Gen? | Priority |
|---|---|---|---|
| Single report, one data source, Pro license | ❌ Skip — use Power Query in model | N/A | Low |
| 3+ reports sharing same source, Pro license | ✅ Yes | Gen1 (only option) | High |
| Any scenario, Fabric or Premium capacity | ✅ Yes | Gen2 CI/CD (always) | High |
| Real-time dashboard requirement | ⚠️ Caution — evaluate latency needs | Gen1 if DirectQuery needed | Medium |
| Multi-team Fabric platform, data sharing needed | ✅ Yes — Gen2 mandatory | Gen2 CI/CD | Critical |
| Heavy Spark / custom Python engineering | ❌ Use Fabric notebooks instead | N/A | Low |
Layer 3: How to structure your Dataflow architecture
Once you decide to use Dataflows, the most common architectural mistake is building a single flat Dataflow that does everything — connects to the source, cleans data, applies business logic, and produces final output — all in one step. This becomes a maintenance problem the moment any single transformation needs to change. The recommended pattern is the three-layer architecture: separate your extraction logic (Layer 1) from your business transformation logic (Layer 2) from your final consumption-ready output (Layer 3). Each layer refreshes in sequence, failures are isolated to the affected layer, and changes to one layer do not ripple unpredictably into others.
🏗️ 6. Power BI Dataflows and Microsoft Fabric: The 2026 Integration Story
For organizations evaluating or already operating on Microsoft Fabric, Dataflows Gen2 are not just a Power BI feature — they are a first-class Fabric citizen. Understanding how they integrate with the broader Fabric platform determines whether you get the full architectural value or use them as a slightly better version of Gen1.
Direct Lake: the performance unlock
The most significant integration benefit between Gen2 Dataflows and Fabric is Direct Lake mode. When a Gen2 Dataflow writes transformed data to a Fabric Lakehouse as Delta tables, Power BI can read that data without importing it into a separate dataset. Direct Lake reads directly from the Delta files in OneLake, eliminating the dataset refresh step entirely for reporting consumers. The practical impact is a 50–70% reduction in capacity consumption compared to import mode, and report data that is current within minutes of the Dataflow refresh completing — without the overhead of a separate semantic model refresh cycle.
Medallion architecture alignment
Gen2 Dataflows align naturally with the medallion (Bronze/Silver/Gold) architecture pattern that Microsoft recommends for Fabric data platforms. Bronze-layer Dataflows extract raw data from source systems exactly as-is and land it in a lakehouse — no transformation, maximum fidelity to the source. Silver-layer Dataflows apply cleaning, standardization, and business rule transformations to the Bronze output. Gold-layer Dataflows or semantic models produce the final, consumption-ready aggregations and metrics that reports and dashboards consume. This separation makes each layer independently testable, replaceable, and maintainable — a significant advantage for teams scaling from a handful of reports to a full organizational data platform. For a deeper look at the data modelling foundation underneath this architecture, the Power BI Star Schema guide explains how to structure your consumption-layer models correctly.
Pipeline orchestration
Gen2 Dataflows integrate natively with Fabric Data Pipelines, enabling orchestration that Gen1 never supported. A pipeline can trigger a Dataflow refresh, pass parameters to control date ranges or target folders, wait for the Dataflow to complete, and conditionally trigger downstream refreshes only on success. This turns Dataflows from an isolated scheduled refresh into a coordinated step in a fully managed data pipeline — complete with error handling, retry logic, and monitoring through the Fabric Monitoring Hub. For teams running multiple dependent Dataflows, this orchestration capability eliminates the manual scheduling coordination that made multi-layer Gen1 architectures fragile.
Power BI Dataflows Gen2 in one line: Self-service ETL for teams who know Power Query — now writing Delta tables to OneLake, integrating with Fabric pipelines, and serving the entire data platform rather than just Power BI reports. The trade-off: Fabric or Premium capacity required, and DirectQuery is not yet available.
🔄 7. Migrating from Gen1 to Gen2: What to Know Before You Start
With Gen1 in legacy status and all future investment in Gen2, most organizations running Gen1 Dataflows will eventually migrate. The technical path is manageable — Gen2 uses the same Power Query Online interface, and Microsoft provides a Save As feature to convert existing classic dataflows. But the migration involves more than copy-pasting transformation logic, and several critical pre-migration checks will save significant post-migration rework.
Step 1: Inventory your Gen1 Dataflows and dependencies
Before moving anything, document every Gen1 Dataflow in your organization: which workspace it lives in, which reports and semantic models depend on it, what its refresh schedule is, and whether it uses any Gen1-specific features that Gen2 does not yet support — particularly DirectQuery and native AI Insights. Rank each Dataflow by business impact: high-impact flows (executive dashboards, financial reporting) should migrate last, after you have validated the process on lower-stakes flows first. Microsoft recommends testing migrated flows in a Fabric workspace before switching production refreshes.
Step 2: Resolve licensing before you build
Gen2 requires Fabric capacity or Power BI Premium. Confirm your workspace assignment and capacity SKU before building any Gen2 Dataflow. If your organization is on Pro licensing without a Fabric or Premium subscription, you cannot create Gen2 Dataflows today — and migrating prematurely will result in flows that cannot be published. Review workspace placement and capacity sizing carefully to avoid surprises during migration, particularly for organizations with multiple workspaces across different capacity assignments.
Step 3: Validate refresh behavior and feature compatibility
Not every Gen1 feature has a direct Gen2 equivalent. DirectQuery to Dataflows — available in Gen1 with Premium or PPU — is not currently available in Gen2. Gen1’s native AI Insights features (Azure ML integration, Cognitive Services) have different implementation paths in Gen2 within the Fabric ecosystem. Validate refresh behavior, output schema compatibility, and downstream connector behavior for each migrated flow before decommissioning the Gen1 source. Flows that feed Excel workbooks or Power Platform items via the dataflow connector may behave differently when the output format changes from CDM folders to Delta tables in OneLake.
For a broader understanding of how Power BI licensing tiers interact with Dataflows and other advanced features, the Power BI Premium vs Pro comparison guide covers the decision framework in detail. And for teams managing multiple data consumers across Fabric, the Power BI Service vs Desktop guide explains where Dataflows fit in the broader workspace architecture.
🏁 8. Conclusion: Dataflows Are the Foundation Your Power BI Environment Is Missing
Power BI Dataflows are not a feature for advanced users — they are the architectural foundation that separates a collection of reports from a governed, scalable BI platform. If your organization has more than two reports sharing a data source, inconsistent metrics across dashboards, or analysts spending hours rebuilding the same data preparation work, a Dataflow layer will solve those problems more reliably than any dashboard redesign or training program. The ROI is documented: 40–60% reduction in dataset development time, 70%+ reduction in data inconsistencies, and refresh time improvements of 80–88% with incremental refresh — these are the numbers consistently reported across enterprise implementations.
The 2026 context adds urgency to the architectural decision. With Gen1 in legacy status and Gen2 now the sole focus of Microsoft’s product investment, the right time to build or migrate is now — subject to your licensing readiness for Fabric or Premium capacity. If you are on Pro today, Gen1 remains a valid production tool; plan your migration timeline as your licensing evolves. If you are already on Fabric or Premium, there is no reason to build new Dataflows in anything other than Gen2 CI/CD. The destination flexibility, pipeline integration, Direct Lake compatibility, and Copilot authoring assistance make Gen2 a substantially better tool — and the Delta table output format ensures your data preparation investment is reusable across the entire Fabric platform, not just Power BI reports.
📌 Key Takeaways
| ✅ | Takeaway |
|---|---|
| ✅ | Power BI Dataflows centralize data transformation logic in the cloud, making it reusable across multiple reports and semantic models — eliminating duplicated Power Query work and inconsistent business metrics. |
| ✅ | Dataflow Gen1 entered legacy status in April 2026 — existing flows continue working, but all new development should be built in Gen2, which requires Fabric or Power BI Premium capacity (minimum F2 SKU at $262.80/month). |
| ✅ | Gen2 writes to Delta tables in OneLake rather than CSV CDM folders, enabling Direct Lake mode in Power BI and reducing capacity consumption by 50–70% compared to import mode while serving the entire Fabric platform. |
| ✅ | Incremental refresh in Dataflows reduces average enterprise refresh times from 35 minutes to 4 minutes (88% reduction) and cuts source system query load by 90%, according to EPC Group implementation data across 150+ organizations. |
| ✅ | DirectQuery to Dataflows is available in Gen1 (with Premium or PPU) but is not yet available in Gen2 — teams with real-time reporting requirements that depend on DirectQuery must plan carefully before migrating. |
| ✅ | The three-layer Dataflow architecture (Bronze extraction, Silver transformation, Gold consumption) aligns with the Fabric medallion pattern and reduces total processing time by 60–70% compared to embedding all logic inside individual semantic models. |
| ✅ | Organizations implementing centralized Dataflow architectures consistently report 40–60% reduction in dataset development time and 70%+ reduction in data inconsistencies across reports — the clearest ROI signal for justifying the investment. |
| ✅ | As of April 2026, all new Gen2 Dataflow items are created with CI/CD and Git integration by default — enabling DevOps-managed deployments, parameter passing from pipelines, and workspace folder organization that Gen1 never provided. |
🔗 Related Articles
- 📖 Power BI Star Schema Explained: How to Build a Fast, Correct Data Model (2026)
- 📖 Power BI Premium vs Pro: Which Plan Does Your Business Need in 2026?
- 📖 Power BI Service vs Desktop: Which Do You Need? (2026)
- 📖 What Is Microsoft Fabric? How It Changes Power BI for Business Teams (2026)
- 📖 Power BI + AI: The Beginner’s Guide to Smarter Business Dashboards in 2026
⚙️ Frequently Asked Questions: Power BI Dataflows
1. What is the difference between Power BI Dataflows and Power Query?
Power Query runs inside your .pbix file on your local machine and only serves that one report. A Dataflow runs Power Query logic as a cloud service in the Power BI Service — it is shareable, schedulable, and can feed multiple reports and semantic models simultaneously. Think of Power Query as a single kitchen for one cook; a Dataflow is a central kitchen serving the whole team. For teams with multiple reports sharing a source, our Power BI Star Schema guide explains how to structure the data model underneath your Dataflow output correctly.
2. Can I use Power BI Dataflows on a Pro license in 2026?
Yes — but with significant limitations. Dataflow Gen1 is available on Pro workspaces ($10/user/month), but Gen1 entered legacy status in April 2026 and will receive no new features. Advanced Gen1 features like incremental refresh and computed entities require Premium Per User or higher. Dataflow Gen2 — the version with all current and future investment — requires Fabric capacity or Power BI Premium as a minimum. Our Power BI Premium vs Pro guide covers the licensing decision in detail.
3. Will Power BI Dataflow Gen1 be shut down?
Microsoft has officially moved Gen1 to legacy status as of April 2026, meaning existing Gen1 Dataflows continue to work but no new features will be added. Microsoft has not announced a specific retirement date as of October 2026. On April 20, 2026, Microsoft revised its announcement to indicate it would “introduce new Dataflow Gen2 paths for Pro/PPU scenarios” — but no general availability date for this has been confirmed. Organizations on Pro should continue using Gen1 but begin planning migration timelines.
4. What is the difference between Dataflow Gen2 and Dataflow Gen2 CI/CD?
As of April 2026, the distinction is largely historical — all new Dataflow Gen2 items are now created with CI/CD and Git integration by default. The older “Gen2 Classic” (without CI/CD) is no longer available for new creation. The CI/CD variant adds Git/DevOps integration, parameter passing from external pipelines, workspace folder organization, and a Save-Close-and-Run authoring experience. Existing Gen2 Classic flows continue to work; use the Save As feature to convert them to the CI/CD variant.
5. How do Power BI Dataflows fit into a Microsoft Fabric architecture?
In Fabric, Gen2 Dataflows are a first-class data engineering tool. They write transformed data as Delta tables to a Fabric Lakehouse via OneLake, making that data immediately available to Power BI in Direct Lake mode (no separate dataset refresh required), to data scientists via Spark notebooks, to SQL analysts via the SQL Analytics Endpoint, and to downstream pipelines. This is the core architectural advantage of Gen2 over Gen1: the same transformation serves the entire data platform rather than just Power BI reports. See our Microsoft Fabric explainer for the full platform context.
📧 Get the AI Buzz Weekly Digest
Weekly AI insights, tools, and strategies — delivered every Monday. Free.
Leave a Reply