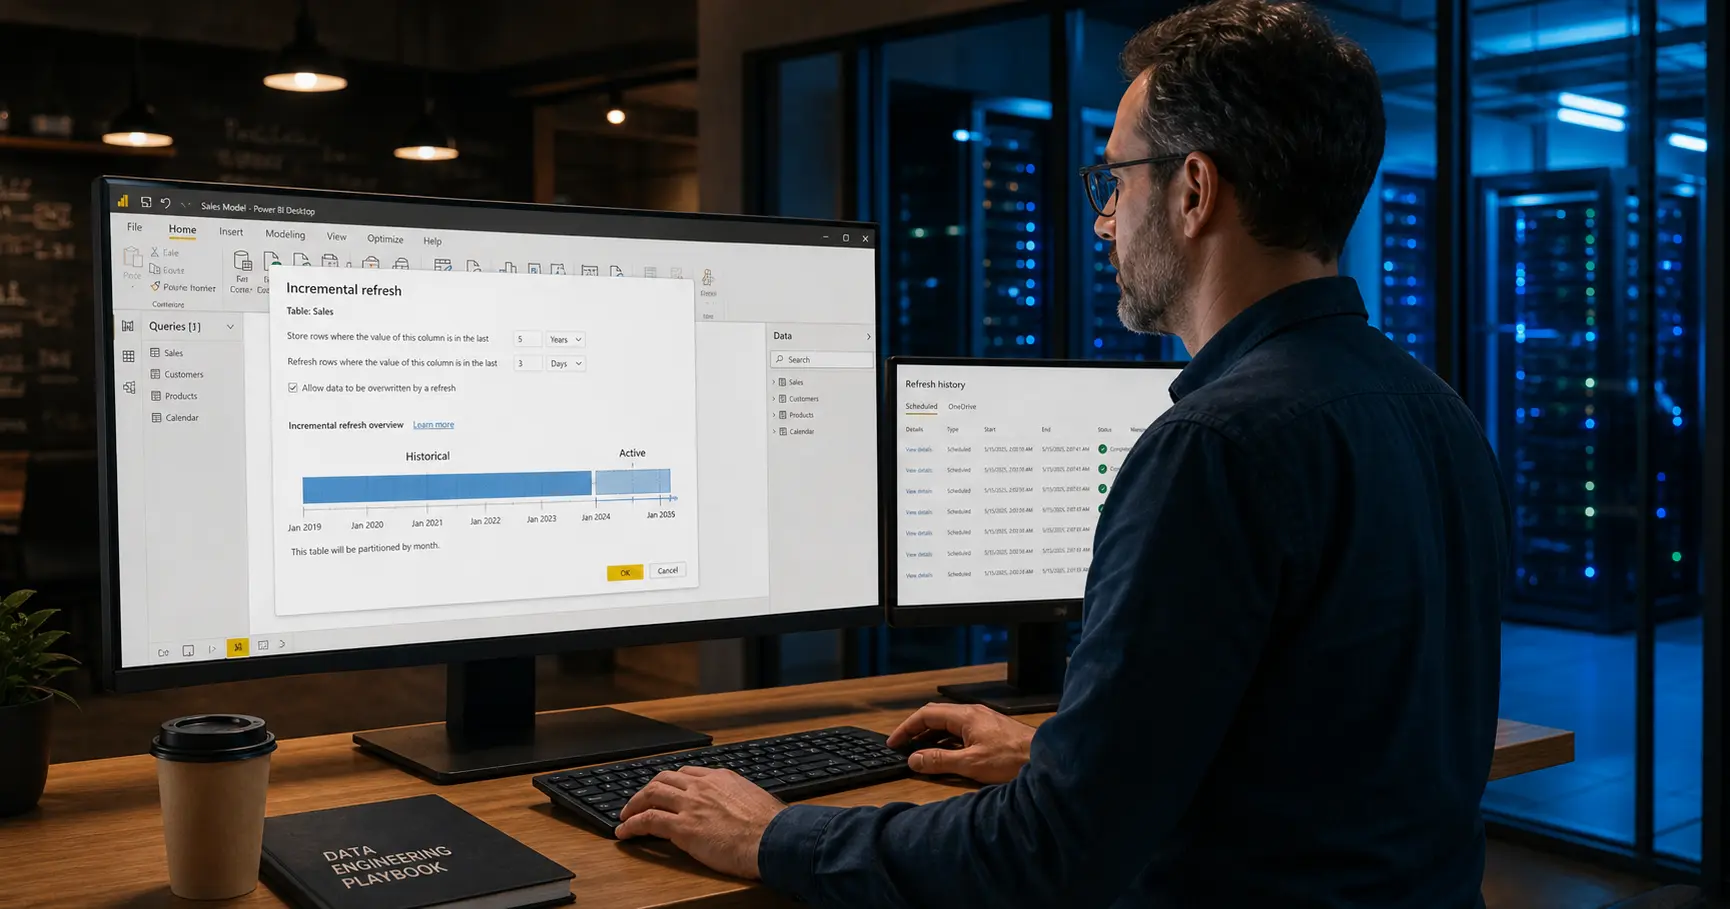
⚡ Reloading five years of history every morning is not a refresh strategy — it is a performance debt you are paying daily. This complete 2026 guide explains exactly how Power BI Incremental Refresh works, how to configure it correctly, how to protect query folding, and how to use it to cut refresh times by up to 88% — with real-world benchmark data and F-SKU capacity guidance included.
Last Updated: October 20, 2026
In the high-stakes world of enterprise data analytics, the spinning refresh wheel is the enemy of productivity. As we move through late 2026, the volume of data generated by AI-integrated business processes has reached a breaking point for traditional full-load refresh strategies. Organisations can no longer afford to reload five years of historical sales data every morning just to surface yesterday’s figures. This is the problem that Power BI Incremental Refresh was built to solve — and in 2026, mastering it is one of the most valuable technical skills a Power BI developer or data architect can possess.
Incremental refresh transforms how Power BI handles data ingestion. Instead of a monolithic “delete everything and reload” cycle, it partitions your tables and keeps historical data frozen while updating only the most recent records. The performance gains are not marginal — they are transformative. Implementation data from EPC Group across 150+ enterprise organisations shows that moving from full refresh to incremental refresh reduces average refresh times from 35 minutes to just 4 minutes — an 88% reduction. At the same time, query load on the source system drops by 90%, protecting operational databases that cannot absorb the sustained pressure of a full nightly extract.
This guide covers everything you need to configure, optimise, and maintain incremental refresh in 2026: the foundational architecture, the mandatory RangeStart and RangeEnd parameters, the query folding requirement that determines whether your policy actually works, step-by-step configuration, Hybrid Tables for real-time capability, Dataflows Gen2 integration, F-SKU capacity considerations, and the most common production pitfalls that cause incremental refresh to silently fail. Whether you are a Power BI developer building your first partitioned model or an architect designing a Fabric-based lakehouse refresh strategy, this is the guide you need.
📘 New to Power BI concepts? Before diving into incremental refresh architecture, bookmark the AI Buzz Glossary — it covers 100+ essential AI terms including VertiPaq, Delta tables, query folding, partitioning, and semantic models in plain English.
🗄️ 1. What Is Power BI Incremental Refresh? (The Architecture Explained)
At its core, Power BI Incremental Refresh is a data management strategy that partitions tables in the Power BI service — or in Microsoft Fabric OneLake — based on defined date ranges. Instead of querying your source system for all historical data on every refresh cycle, the engine is instructed to request only the data that has changed or been added since the last successful refresh. The unchanged historical partitions remain in place, untouched, reducing the scope of every subsequent refresh from “all time” to “the last few days.”
This is not a background optimisation that Power BI applies automatically. It is an explicit policy you configure on each table, defining how far back historical data is stored and how far back the engine should look for changes on each run. Once configured and published to the Power BI service, the engine takes over: it creates and manages the physical partitions inside the semantic model, ensures that each refresh cycle targets only the correct date range, and archives older partitions automatically as they age out of the refresh window.
Why Full Refresh Fails at Scale
To appreciate why incremental refresh matters, it helps to understand the specific failure modes of full refresh at enterprise scale. A full refresh is a three-phase operation: Power BI connects to the source, executes a query that retrieves the entire table (all rows, all history), loads the result into the VertiPaq in-memory engine, and discards the previous copy of the data. For a small table, this is fast and unproblematic. For a 500-million-row fact table spanning five years of transactional history, it creates three compounding problems.
The first problem is time. The Power BI service imposes an absolute timeout on dataset refresh operations. Large full refreshes frequently breach this limit, particularly on lower-tier Fabric SKUs with constrained memory. A refresh that was completing in 30 minutes six months ago may be timing out today as the dataset grows. The second problem is source load: a full extract query runs against your source database for the entire duration of the refresh window, consuming I/O and CPU that the source system may need for operational workloads during business hours. The third problem is fragility: a single failed refresh leaves the entire model serving stale data — because there is no partial fallback when the full reload fails.
Incremental refresh eliminates all three problems simultaneously. By refreshing only the most recent partition — typically the current day or the last three days — the refresh completes quickly, source load is reduced to a small filtered query rather than a full table scan, and failures affect only the current partition rather than the model’s entire data state.
🔑 2. The Prerequisites: RangeStart, RangeEnd, and Query Folding
You cannot configure Power BI Incremental Refresh correctly without understanding three foundational concepts: the RangeStart and RangeEnd reserved parameters, the filter application logic that creates the partition boundary, and the query folding requirement that determines whether the policy performs as intended. Each of these must be understood and implemented correctly — a mistake in any one of them produces a policy that either fails silently or delivers no performance improvement at all.
RangeStart and RangeEnd: The Reserved Parameters
RangeStart and RangeEnd are not just helpful labels you choose for your parameters — they are reserved keywords that the Power BI service recognises and uses to inject date filters dynamically into your Power Query M code at refresh time. You must create these parameters in Power BI Desktop with the exact names “RangeStart” and “RangeEnd” (case-sensitive) and assign them the “Date/Time” data type. Any other name or data type will prevent the engine from recognising them as partition boundaries.
During development in Desktop, you assign placeholder date values to these parameters that encompass a small, manageable subset of your data — for example, the last 7 days. This keeps the development data load fast and the model responsive during testing. When you publish the model to the Power BI service and configure the incremental refresh policy, the service overrides these placeholder values with its own dynamically calculated date ranges for each partition.
The Filter Logic: Why One Boundary Must Use “Equal To”
Once RangeStart and RangeEnd are created, you must apply a custom filter to your date column in Power Query using both parameters simultaneously. The filter logic must follow a specific pattern that avoids double-counting rows at partition boundaries. The correct structure is:
- Date is after or equal to RangeStart (using “greater than or equal to”)
- AND Date is before RangeEnd (using “strictly less than” — not “less than or equal to”)
This asymmetry — one inclusive boundary, one exclusive boundary — is deliberate. Because adjacent partitions share boundary values, using “equal to” on both sides would cause a row with a timestamp exactly at midnight to appear in two partitions simultaneously. The inclusive lower boundary, exclusive upper boundary pattern ensures every row belongs to exactly one partition.
The Rule of Query Folding: The Make-or-Break Requirement
Incremental refresh is architecturally dependent on query folding — the ability of the Power BI Power Query engine to translate your M transformation steps into a single native query (typically SQL) that executes on the source system. When query folding is intact, Power BI can send a filtered query to the source — “give me only rows where date is between RangeStart and RangeEnd” — and the source database executes that filter before returning data. When query folding is broken, Power BI must retrieve the entire table from the source and apply the filter locally. The incremental refresh policy appears to work, but the engine is downloading the full dataset on every refresh cycle, providing no performance benefit whatsoever.
Query folding breaks in predictable ways. Common causes include custom M functions that have no SQL equivalent, certain merge and join operations, adding an index column, and any transformation step that references data from two different sources simultaneously. To verify folding is intact, right-click the final step in your Power Query applied steps panel. If “View Native Query” is available and shows a SQL statement that includes your date filter, folding is intact. If “View Native Query” is greyed out, folding is broken and must be restored before incremental refresh will deliver any performance improvement.
The golden rule for incremental refresh: Keep every transformation step in your fact table query foldable. Move any non-foldable steps — custom functions, complex merges, index columns — to a separate Staging query that feeds your fact table, rather than adding them directly to the fact table query. This preserves folding on the fact table while still allowing complex transformations in your data preparation layer.
⚙️ 3. Step-by-Step Configuration for 2026
Configuring incremental refresh correctly requires a specific sequence of steps in Power BI Desktop before publishing to the service. The following walkthrough covers the complete configuration process for a standard production deployment in 2026, including the optional but recommended settings that reduce resource consumption and improve partition reliability.
Step 1: Create RangeStart and RangeEnd Parameters
In Power BI Desktop, navigate to the Power Query Editor. Select “Manage Parameters” and create two new parameters. Name the first “RangeStart” and the second “RangeEnd.” Set the data type for both to “Date/Time.” Assign placeholder dates that encompass a small sample of your data — for example, RangeStart = the first day of the current month and RangeEnd = today’s date. These values are for development only and will be overridden by the service when the policy is applied.
Step 2: Apply the Date Filter to Your Fact Table
In the Power Query Editor, select your fact table. Use “Custom Filter” to apply the two-parameter filter to your date column. The filter must use the asymmetric pattern described in Section 2: greater than or equal to RangeStart, and strictly less than RangeEnd. Confirm that the “View Native Query” option remains available after applying the filter — this confirms that query folding is intact and the filter will be pushed to the source system at refresh time.
Step 3: Configure the Incremental Refresh Policy
Close and apply your Power Query changes. In the Data pane of Power BI Desktop, right-click your fact table and select “Incremental Refresh.” The incremental refresh policy dialog presents two primary settings:
- Archive data starting: This defines how far back in time Power BI retains historical partitions. A typical enterprise setting is 3 to 5 years. Data older than this threshold is automatically removed from the model as new partitions are added.
- Incrementally refresh data starting: This defines how far back from the current date Power BI looks for changes on each refresh cycle. A typical setting is 3 to 7 days — wide enough to catch late-arriving records and data corrections, narrow enough to keep refresh cycles fast.
Step 4: Enable “Detect Data Changes” (Recommended)
The “Detect Data Changes” option is available in Power BI Premium and Fabric capacities and is strongly recommended for production deployments. When enabled, you specify a date/time column that tracks when each record was last updated — typically a “LastModifiedDate” or “UpdateTimestamp” column maintained by the source system. Before refreshing each partition, Power BI queries the maximum value of this column in that partition’s date range. If the maximum has not changed since the last refresh, the partition is skipped entirely. This further reduces capacity consumption on stable historical partitions that have not changed since the last cycle.
Step 5: Publish and Verify
Publish the model to your Power BI workspace. The first refresh after publishing will be a full load — the service must build the initial partition structure by loading all historical data within your archive window. This first refresh will take as long as a standard full refresh. Every subsequent refresh cycle will be incremental, targeting only the partition window you configured. Monitor the first several incremental refreshes in the Power BI service’s Refresh History to confirm that refresh duration and source query count match expectations.
| Configuration Setting | What It Controls | Typical Enterprise Setting | Requires Premium / Fabric? |
|---|---|---|---|
| Archive Data Starting | How much history is retained in partitions | 3 to 5 years | No (available in Pro) |
| Incrementally Refresh Starting | How far back each refresh cycle looks for changes | 3 to 7 days | No (available in Pro) |
| Detect Data Changes | Skips unchanged partitions based on a tracked column | Enabled — use LastModifiedDate or equivalent | Yes — Premium or Fabric required |
| Only Refresh Complete Periods | Prevents partial-day or partial-month partitions from being created | Enabled for monthly or weekly granularity models | No (available in Pro) |
| Get Latest Data in Real Time (Hybrid Tables) | Adds a live DirectQuery partition for the most recent period | Enabled only when sub-hour freshness is required | Yes — Premium or Fabric required |
📊 4. Performance Benchmarks: The Real-World Impact
The case for incremental refresh is not theoretical. Implementation data and independent benchmarks published in 2026 consistently demonstrate performance improvements that justify the configuration investment many times over. Understanding these numbers is useful not just for validating the approach but for building the business case when seeking approval for Premium or Fabric capacity upgrades that unlock the full feature set.
EPC Group Implementation Data (150+ Organisations)
EPC Group’s data across more than 150 enterprise Power BI implementations provides the most comprehensive real-world evidence base available. The headline finding — a reduction in average refresh time from 35 minutes to 4 minutes (88%) — is the most widely cited figure, but the source system impact is equally significant. Source system query load fell by 90% after incremental refresh was implemented across these deployments. For organisations where the Power BI refresh pipeline was competing with operational workloads on shared databases, that reduction directly translated to measurable improvements in application performance during business hours.
The same dataset also covers the impact of EPC Group’s recommended three-layer Dataflow architecture — separating extraction, transformation, and loading into distinct Dataflow Gen2 layers — which reduced total end-to-end pipeline processing time by 60 to 70% compared to single-layer Dataflow designs. This architectural approach pairs naturally with incremental refresh: each Dataflow layer processes only the incremental delta rather than the full historical dataset, compounding the efficiency gains across the pipeline.
Capacity Unit Savings on Microsoft Fabric F-SKUs
On Microsoft Fabric F-SKUs, incremental refresh has a direct and measurable impact on Capacity Unit (CU) consumption. A full refresh of a large fact table on an F4 or F8 capacity can consume a significant share of available CUs for the duration of the refresh window, causing other workloads — report queries, Dataflow pipelines, Spark jobs — to queue or throttle. Incremental refresh dramatically narrows the refresh window and the data volume processed, freeing CUs for concurrent workloads and allowing organisations to operate effectively on lower-tier SKUs.
EPC Group’s data further shows that writing to a Fabric Lakehouse via Direct Lake rather than Import reduces capacity consumption by 50 to 70% at scale — and incremental refresh amplifies this advantage by ensuring that even the import-equivalent operations involved in partition refreshes are scoped to the smallest possible data window. For organisations sizing their Fabric capacity, incremental refresh is a prerequisite for accurate CU consumption modelling — without it, any capacity estimate for a large Import model will be materially understated.
| Metric | Full Refresh | Incremental Refresh |
|---|---|---|
| Average Refresh Duration | 35 minutes (EPC Group baseline) | 4 minutes — 88% reduction |
| Source System Query Load | Full table scan on every cycle | 90% lower — filtered partition query only |
| Refresh Timeout Risk | High on large datasets | Near zero — small partitions complete quickly |
| Pipeline Processing Time (3-Layer Dataflow) | Baseline total processing time | 60–70% reduction in end-to-end pipeline time |
| Capacity Consumption (Fabric Lakehouse, at scale) | High CU utilisation during refresh window | 50–70% lower CU consumption vs Import at scale |
| Failure Impact | Full model serves stale data on any failure | Only the current partition is affected; history intact |
🌊 5. Hybrid Tables: Incremental Refresh With Real-Time Capability
For scenarios where even hourly refresh is insufficient — operational dashboards monitoring live production lines, financial trading dashboards, patient monitoring in healthcare environments — Power BI offers Hybrid Tables, an advanced configuration that extends incremental refresh with a real-time DirectQuery partition for the most recent data window.
How Hybrid Tables Work
A Hybrid Table combines three distinct storage modes in a single table object within the semantic model. Historical partitions — typically months or years of data — are stored as Import-mode partitions, giving them the full speed advantage of in-memory VertiPaq query execution. A recent Import partition — typically the last few days — is refreshed frequently on a schedule. And a real-time DirectQuery partition covers the most recent period — the current day or the current hour — querying the source system live at report interaction time.
From the report consumer’s perspective, the table behaves as a single unified dataset. A query spanning three years of history and today’s live data is satisfied seamlessly: historical rows come from in-memory partitions at sub-second speed, and today’s live transactions come from the DirectQuery partition. The user sees one result set, one table, one number. The performance trade-off is that any visual that touches the DirectQuery partition incurs source round-trip latency — so Hybrid Tables work best when the most common queries target historical ranges that are fully Import-backed, and real-time interaction is limited to a small number of purpose-built operational visuals.
Hybrid Table Licensing Requirements
Hybrid Tables require Power BI Premium Per Capacity or Microsoft Fabric capacity. They are not available on Power BI Pro or Premium Per User licences. The “Get Latest Data in Real Time” option in the incremental refresh policy dialog is the switch that activates Hybrid Table behaviour — it is only visible when the workspace is assigned to a Premium or Fabric capacity. Before designing a Hybrid Table architecture, confirm that your capacity SKU can sustain the concurrent DirectQuery load generated by the real-time partition alongside the Import partition refresh cycles. On lower F-SKUs such as F2 or F4, this concurrent load can cause visible throttling if not carefully managed.
🔄 6. Incremental Refresh in the Fabric Era: Dataflows Gen2 and OneLake
The Microsoft Fabric platform changes the incremental refresh landscape in two significant ways: it introduces Dataflows Gen2 as the recommended ETL layer for building the data pipelines that feed Power BI semantic models, and it changes how partition management works for models connected to OneLake Delta tables via Direct Lake mode. Understanding both changes is essential for Power BI architects building on Fabric in 2026.
Dataflows Gen2: The 2026 Standard
As of April 2026, Microsoft moved Dataflow Gen1 into legacy status. All new investment, new features, and new platform integrations are being built for Dataflow Gen2. For incremental refresh, this transition matters because Gen2 Dataflows integrate natively with Fabric Lakehouses, writing output directly as Delta tables in OneLake rather than into Power BI’s internal staging storage. This eliminates a data duplication step and creates a cleaner architectural separation between the data engineering layer (Dataflows Gen2) and the semantic layer (Power BI semantic models).
When building incremental refresh pipelines with Dataflows Gen2, the query folding requirement remains in full force. Gen2 Dataflows must connect to foldable source connectors for the date-based partition filter to be pushed to the source system. The most reliable approach is to ensure that the Gen2 Dataflow query applies RangeStart and RangeEnd filters as the first transformation step immediately after the source connection — before any other transformation that might break folding — and then to build all subsequent cleaning and transformation steps on top of the filtered result.
Teams still operating Gen1 Dataflows should begin planning their migration to Gen2. While Gen1 continues to function, it will receive no new features and will eventually be retired. The Power BI Dataflows guide covers the migration path and the key architectural differences between the two generations in detail.
Incremental Refresh and Direct Lake Fallback Prevention
For Fabric deployments using Direct Lake storage mode, incremental refresh at the Dataflow Gen2 layer plays a critical role in preventing the most damaging Direct Lake production risk: silent fallback to DirectQuery. As covered in the Power BI storage mode guide, Direct Lake falls back when Delta tables exceed per-SKU row or Parquet file guardrails, or when table files are not optimised with V-Order. Incremental Dataflow processing — writing only new or changed records rather than rewriting the full Delta table on each cycle — keeps Parquet file counts low and prevents the file fragmentation that triggers fallback.
A documented production client engagement illustrates the stakes: a Direct Lake model was experiencing a 40% fallback rate across user queries. After applying V-Order optimisation and running the OPTIMIZE command on the Delta tables to compact fragmented Parquet files — a direct consequence of non-incremental full rewrites on each pipeline run — the fallback rate dropped to under 3%. The incremental write pattern is the upstream discipline that keeps Delta tables compact and V-Ordered between OPTIMIZE runs, making the maintenance window less frequent and less critical.
📊 Building your Power BI knowledge systematically? The AI Buzz Power BI & Data Analytics Hub covers everything from star schemas and DAX fundamentals to Fabric architecture and Direct Lake optimisation — all in one place.
⚠️ 7. Common Pitfalls and How to Avoid Them
Incremental refresh is one of the more technically demanding Power BI features to implement correctly. The configuration dialog is simple, but the failure modes are subtle and often silent — the policy appears to function while delivering none of the performance benefits. The following pitfalls are drawn from real-world production implementations and represent the most frequent causes of incremental refresh underperformance in 2026.
Pitfall 1: Broken Query Folding (The Silent Killer)
The most common and most consequential incremental refresh failure is broken query folding. When folding breaks, Power BI downloads the entire source table on every refresh cycle and applies the partition filter locally. The refresh history shows that each cycle completed successfully, and the data in the model is correct — so there is no obvious error signal. The only indicators are that refresh times have not improved materially from the full-refresh baseline, and that source system query logs show full table scans rather than filtered queries during the refresh window.
The diagnostic check is simple: right-click the final step in your Power Query applied steps panel and confirm that “View Native Query” is available and shows a SQL statement containing your date filter predicates. Run this check every time you add a new transformation step to a fact table query. A new step that breaks folding after a successful deployment is the most common cause of incremental refresh performance degrading gradually over time as the data model evolves.
Pitfall 2: Time Zone Misalignment at Partition Boundaries
The Power BI service executes refresh operations using UTC as its system clock. If your source system stores timestamps in a local time zone — Eastern Time, Central European Time, Australian Eastern Standard Time — and your Power Query date filter is applied without a UTC conversion, the partition boundary will be misaligned by the UTC offset of your source time zone. For a source system in EST (UTC-5), this means the boundary between the current-day partition and the previous-day partition falls at 7:00 PM local time rather than midnight — causing records created between 7:00 PM and midnight to either appear in the wrong partition or be excluded entirely from the incremental refresh window until the offset corrects itself.
The correct mitigation is to convert all timestamp columns to UTC at the source system level before they reach Power Query, or to add an explicit UTC conversion as the first transformation step in your Power Query query — before any step that might break folding. Do not convert time zones after applying the RangeStart/RangeEnd filter; the filter must operate on UTC values for the partition boundaries to align correctly with the service’s refresh clock.
Pitfall 3: Applying Incremental Refresh to Non-Foldable Sources
Flat files — CSV, Excel workbooks, JSON exports — do not have a query engine capable of executing a filtered query. Power BI cannot fold the RangeStart/RangeEnd filter back to a flat file source because there is no SQL endpoint to receive it. If you configure incremental refresh on a table sourced from a flat file, the engine will download the entire file on every refresh cycle and filter it locally — indistinguishable from a broken-folding scenario in a relational source, but with no remediation available at the Power Query layer. The correct architecture for flat file sources is to land the data in a SQL database, a Fabric Lakehouse Delta table, or a Dataflows Gen2 staging layer before connecting Power BI’s incremental refresh policy. Never apply incremental refresh directly to flat file sources.
Pitfall 4: The March 2026 Desktop Version Breaking Change
A significant breaking change took effect in October 2026: Power BI Desktop versions from March 2026 or earlier can no longer save or share files directly to OneDrive and SharePoint. For teams managing incremental refresh configurations stored in PBIX files on SharePoint or OneDrive — a common pattern for developer collaboration — this change breaks the file-sharing workflow for anyone on an outdated Desktop version. Before beginning any incremental refresh configuration or migration project in late 2026, audit the Power BI Desktop versions in use across your development team and upgrade any instance running the March 2026 release or earlier to the current monthly release.
Pitfall 5: Ignoring Partition Count Growth Over Time
Incremental refresh creates a new partition for each period in your archive window. A model configured to archive 5 years of daily data will eventually contain 1,825 partitions. While Power BI manages partition creation and archiving automatically, large partition counts can slow down the framing operation in Direct Lake models and increase the overhead of metadata operations in Import models. Best practice is to use monthly or weekly partitioning for the historical archive window — reserving daily partitioning only for the active refresh window — to keep partition counts manageable as the model ages. The Power BI service supports partition granularity configuration in the advanced incremental refresh settings.
🔗 8. Incremental Refresh and Row-Level Security
Row-Level Security (RLS) and Incremental Refresh interact in ways that are not always obvious from the Power BI documentation, and misconfiguring the combination can produce security gaps or unexpected performance degradation. The key rule is that RLS filter expressions must be evaluated against the current user identity at query time — which means RLS evaluation always runs against in-memory data in Import mode partitions, regardless of which partition is being queried. This is the correct and expected behaviour, and it is fully supported in Incremental Refresh models.
Where the interaction becomes more complex is in Hybrid Table configurations where the real-time DirectQuery partition is active. RLS filter expressions that work correctly against Import partitions may behave differently — or produce errors — against the DirectQuery partition if the underlying source system uses different column names, data types, or security structures than the Power BI model. Always test RLS behaviour explicitly against the DirectQuery partition in Hybrid Table configurations, not just against historical Import partitions. The Power BI Row-Level Security complete guide covers the detailed interaction between RLS, Hybrid Tables, and Direct Lake mode.
🏁 9. Conclusion: Incremental Refresh Is a Scalability Commitment
Incremental refresh is not a single configuration setting — it is an architectural commitment to scalability. It requires query folding discipline, careful parameter implementation, UTC-aligned timestamp management, and ongoing monitoring to ensure it continues to deliver the performance improvements it was designed for. But the investment pays compounding returns: faster refresh cycles that improve data freshness for end users, reduced source system pressure that protects operational performance, lower Fabric capacity consumption that reduces cloud costs, and a more resilient refresh pipeline that isolates failures to the current partition rather than the entire model.
In 2026, with Microsoft Fabric’s Direct Lake architecture requiring Delta table discipline upstream, and with P-SKUs giving way to F-SKUs that make CU efficiency a financial priority, incremental refresh has moved from an advanced optimisation technique to a foundational production requirement for any Power BI deployment managing datasets that are growing toward and beyond the tens of millions of rows threshold. Teams that implement it correctly — with query folding verified, time zones aligned, Dataflows Gen2 handling the incremental write pipeline, and partition counts managed — will find that their semantic models scale cleanly as their data grows, without requiring capacity upgrades or disruptive model redesigns. Teams that defer it will increasingly find themselves managing refresh timeouts, source system complaints, and capacity overruns that a correct incremental refresh configuration would have prevented entirely.
For developers who have not yet explored the foundational Power BI architecture concepts that make incremental refresh possible — star schema design, relationship modelling, and DAX calculation strategy — the Power BI star schema guide and the beginner’s guide to Power BI provide the necessary groundwork before tackling partition-level performance optimisation.
📌 Key Takeaways
| ✅ | Takeaway |
|---|---|
| ✅ | Incremental refresh reduces average Power BI refresh times from 35 minutes to 4 minutes — an 88% reduction — and cuts source system query load by 90%, based on EPC Group implementation data across 150+ enterprise organisations. |
| ✅ | The RangeStart and RangeEnd parameters are reserved Power BI keywords and must be created with the exact names and the Date/Time data type — any variation prevents the service from recognising them as partition boundaries. |
| ✅ | Query folding is the non-negotiable prerequisite for incremental refresh to deliver any performance improvement — if “View Native Query” is greyed out in Power Query, the engine is downloading the entire table on every refresh cycle regardless of the partition policy. |
| ✅ | The Power BI service runs on UTC — all date filters and partition boundaries must be aligned to UTC timestamps to avoid row-level misallocation at partition boundaries, particularly for source systems in non-UTC time zones. |
| ✅ | Hybrid Tables extend incremental refresh with a real-time DirectQuery partition for the most recent period, enabling Import-speed historical queries alongside live operational visibility — but require Power BI Premium or Fabric capacity and careful source system load planning. |
| ✅ | Dataflow Gen1 entered legacy status in April 2026 — all new incremental refresh pipelines in Microsoft Fabric should be built on Dataflow Gen2, which writes natively to OneLake Delta tables and integrates directly with Fabric Lakehouse architecture. |
| ✅ | Incremental write patterns at the Dataflow Gen2 layer are essential for preventing Direct Lake fallback — a production client case showed a 40% fallback rate caused by fragmented Parquet files, which dropped to under 3% after V-Order optimisation and OPTIMIZE compaction of the Delta tables. |
| ✅ | Power BI Desktop versions from March 2026 or earlier can no longer save or share files to OneDrive and SharePoint as of October 2026 — audit Desktop versions across your development team before beginning any incremental refresh configuration or migration project. |
🔗 Related Articles
- 📖 Power BI Import vs DirectQuery vs Direct Lake: Which Storage Mode Should You Use? (2026)
- 📖 Power BI Dataflows Explained: What They Are and When to Use Them (2026)
- 📖 Power BI Star Schema Explained: How to Build a Fast, Correct Data Model (2026)
- 📖 What Is Microsoft Fabric? How It Changes Power BI for Business Teams (2026)
- 📖 Power BI Row-Level Security (RLS) Explained: A Step-by-Step Admin Guide (2026)
FAQs
1. Does Power BI Incremental Refresh require a Premium or Fabric licence?
The core incremental refresh policy — archive window, refresh window, RangeStart/RangeEnd parameters — is available with Power BI Pro licences. However, the most valuable production features require Premium or Fabric capacity: “Detect Data Changes” (which skips unchanged partitions) and Hybrid Tables (which add a real-time DirectQuery partition) are both restricted to Premium Per Capacity or Microsoft Fabric F-SKU capacities. Understanding Power BI Premium vs Pro licensing is the essential first step before scoping your incremental refresh architecture.
2. How do I know if query folding is broken in my Power Query setup?
In Power BI Desktop’s Power Query Editor, right-click the final step in your Applied Steps panel. If “View Native Query” is available and returns a SQL statement that includes your date filter predicates (referencing RangeStart and RangeEnd values), query folding is intact. If “View Native Query” is greyed out, folding is broken and incremental refresh will download the entire source table on every cycle — delivering no performance improvement. Review your Power BI Dataflows architecture and isolate non-foldable steps into a separate staging query to restore folding on your fact table.
3. Can incremental refresh be used with Direct Lake storage mode in Microsoft Fabric?
Yes, but they operate at different layers. Incremental refresh in this context applies at the Dataflow Gen2 pipeline level — writing only new or changed Delta records to OneLake rather than rewriting the full table on each cycle. This is essential for keeping Parquet file counts low and preventing the file fragmentation that causes Direct Lake to fall back to DirectQuery. The Power BI storage mode guide covers how incremental pipeline writes protect Direct Lake performance in detail.
4. How many partitions does incremental refresh create, and does it matter?
Power BI creates one partition per period within your archive window, at the granularity you configure. A model with a 5-year archive window at daily granularity will eventually contain over 1,800 partitions. For Microsoft Fabric Direct Lake models, high partition counts slow the framing metadata operation. Best practice is to use monthly granularity for the historical archive window, switching to daily granularity only for the active incremental refresh window — this keeps total partition counts manageable as the model ages.
5. What is the impact of incremental refresh on Row-Level Security?
RLS filter expressions in Power BI are evaluated at query time against the current user identity and work correctly against incremental refresh Import partitions. The complexity arises with Hybrid Tables: RLS filter expressions that work against Import partitions may behave differently against the real-time DirectQuery partition if the source system uses different column structures. Always test RLS behaviour explicitly against the DirectQuery partition in Hybrid Table configurations. The Power BI Row-Level Security guide covers the complete interaction between RLS, Hybrid Tables, and Direct Lake mode.
📧 Get the AI Buzz Weekly Digest
Weekly AI insights, tools, and strategies — delivered every Monday. Free.
Leave a Reply