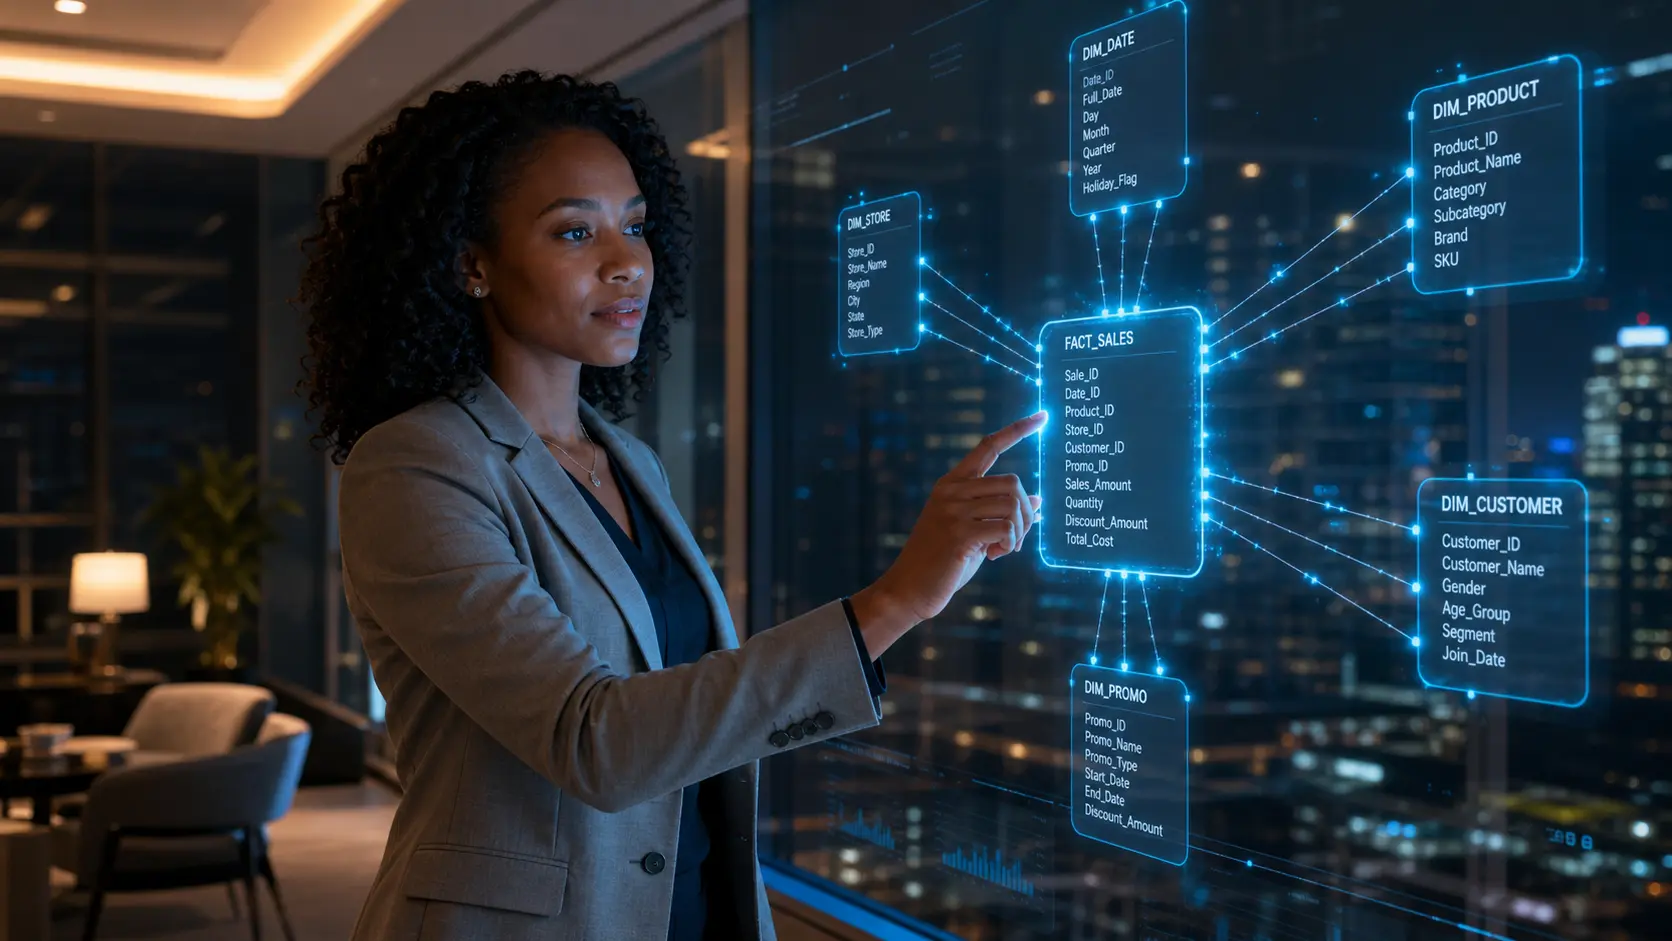
📊 Data modeling is the invisible engine of every fast report. A Power BI star schema isn’t just a design choice; it is the fundamental architectural requirement for scalable, accurate, and high-performance analytics in 2026.
Last Updated: October 12, 2026
A Power BI star schema is the industry-standard data modeling architecture designed to optimize report performance and calculation accuracy. In its simplest form, it organizes data into two distinct table types: fact tables (which store quantitative events) and dimension tables (which store descriptive attributes). When these tables are connected through one-to-many relationships, they form a “star” shape with the fact table at the center. For developers and analysts, building a star schema is the single most effective way to prevent slow visuals, ambiguous DAX results, and memory-intensive models that crash under enterprise workloads.
As we move through 2026, the importance of correct data modeling has only intensified with the adoption of Microsoft Fabric and real-time streaming analytics. Modern enterprise data environments now handle petabytes of information across distributed “OneLake” architectures. Without a rigid star schema foundation, Power BI’s VertiPaq engine cannot effectively compress data, leading to astronomical compute costs and laggy user experiences. This guide covers everything from the basic fact-dimension relationship to advanced 2026 modeling strategies for AI-assisted reporting.
In this comprehensive guide, you will learn the core components of the star schema, why flat tables are the primary cause of report failure, and a step-by-step decision framework for structuring your data model. We will also explore real-world use cases and honest limitations of the star schema approach in complex business environments. Whether you are a BI professional or a business leader navigating AI adoption, understanding this data foundation is non-negotiable for success. For a broader look at the tools involved, see our guide to Power BI for beginners.
📖 New to AI and Data terminology? Visit the AI Buzz AI Glossary — 100+ essential AI terms explained in plain English, each linking to a full in-depth guide.
📊 1. What is a Power BI Star Schema?
The star schema is a relational data modeling approach that simplifies complex business data into a scannable, logical structure. The term “star” originates from the visual layout of the model in the Power BI relationship view: a central fact table surrounded by several dimension tables. This structure is specifically optimized for the VertiPaq engine—the column-store database that powers Power BI. Unlike traditional transactional databases (OLTP) which prioritize data entry speed, the star schema prioritizes data retrieval and calculation speed (OLAP).
The Fact Table acts as the nucleus of the model. It contains the “numbers”—quantitative data like sales amounts, temperature readings, or website clicks. These tables are typically long and narrow, often containing millions or billions of rows. Every record in a fact table represents a specific business event. To keep the model efficient, fact tables avoid storing descriptive text; instead, they use “foreign keys” (IDs) to link to the surrounding dimensions. This separation allows Power BI to perform lightning-fast aggregations, such as summing total sales across multiple regions in milliseconds.
Dimension Tables are the “descriptors” that provide context to the facts. They answer the “who, what, where, when, and why” of the data. For example, while the fact table stores a sales amount, the dimension tables store information about the product name, the customer’s loyalty tier, or the store’s geographic location. These tables are usually short and wide, containing many descriptive columns but fewer rows. By filtering a dimension table, you automatically filter the related fact table, creating the intuitive “slicing and dicing” experience that users expect from modern BI reports.
🚀 2. Why it Matters in 2026: The Performance Reality
In 2026, the “flat table” approach—importing a single, massive Excel-style sheet into Power BI—has become a primary driver of technical debt. Research from Gartner indicates that 60% of Power BI performance issues in enterprise deployments are rooted in poor data modeling rather than inefficient DAX. When you use a star schema, Power BI can utilize “Relationship Filtering” which is significantly more efficient than scanning a single wide table. Correct modeling reduces memory consumption by 40–60%, allowing organizations to stay within lower-cost Fabric capacities while maintaining high-speed responsiveness.
The rise of Generative AI has further elevated the star schema’s importance. When using Microsoft Copilot in Power BI, the AI’s ability to generate accurate insights depends entirely on the clarity of the underlying model. A star schema provides a clean “semantic map” that AI models can easily interpret. If the model is a messy “spaghetti” of interconnected tables or a single flat sheet, the AI will often hallucinate or fail to join data correctly. In 2026, a clean star schema is the prerequisite for reliable AI-driven analytics.
Furthermore, the 2026 data landscape is defined by “Hybrid Connectivity.” Organizations are no longer just importing data; they are connecting to data in place via “Direct Lake” mode in Microsoft Fabric. This architecture relies on the “Parquet” file format, which is naturally optimized for columnar storage. A star schema aligns perfectly with this format, enabling zero-copy data sharing between Power BI and other tools like Snowflake or Databricks. For a comparison of these platforms, see our analysis of Fabric vs Databricks vs Snowflake.
The 2026 Power BI Reality: Flat tables are for Excel; Star Schemas are for Power BI. In a world of billion-row datasets and AI assistants, the difference between a well-modeled and poorly-modeled dataset is often a 10x difference in query speed and a 50% difference in cloud compute costs.
⚖️ 3. Comparison: Star Schema vs. Flat Tables vs. Snowflake
| Feature | Flat Table | Star Schema | Snowflake Schema |
|---|---|---|---|
| Query Speed | ⚠️ Slow on large data | ✅ Fastest (Optimized) | ❌ Slower (Many Joins) |
| DAX Ease | Simple but limited | ✅ Natural/Intuitive | ⚠️ Complex relationships |
| Memory Usage | ❌ High (Redundant text) | ✅ Low (Compressed) | ✅ Very Low (Normalized) |
| Maintenance | Simple | Moderate | ❌ Difficult / High overhead |
| AI/Copilot Fit | ⚠️ Poor (Amorphous) | ✅ Excellent (Map ready) | ⚠️ Moderate (Too many tables) |
| Best For | Small, simple sheets | 95% of PBI Reports | Specific data warehouse cases |
📊 4. Core Use Cases for Star Schema Modeling
One of the most powerful applications of the star schema is in Financial Consolidation and Reporting. In 2026, global organizations like PwC utilize star schemas to reconcile disparate ledger systems across dozens of countries. By centering a “General Ledger” fact table and surrounding it with dimensions for “Chart of Accounts,” “Currency,” and “Legal Entity,” these firms can perform real-time currency conversions and roll-ups without complex nested formulas. This architecture ensures that “Calculated Measures” always yield consistent results regardless of which filters are applied to the report. For more on calculation logic, see calculated columns vs measures.
Another critical use case is Sales and E-commerce Analytics. Retailers managing high-volume transactions across physical stores and online platforms use star schemas to track “Omnichannel” performance. The fact table stores the individual transaction lines (SKU, Price, Quantity), while dimensions provide the context for “Marketing Campaign,” “Promotion Type,” and “Fulfillment Center.” This allows marketing managers to see which campaigns are driving the most profitable sales in specific ZIP codes instantly. Without a star schema, calculating “Sales per Marketing Dollar” across different attribution models would be nearly impossible to sustain at scale.
Finally, IoT and Sensor Data Monitoring has become a major driver of modeling complexity in 2026. Companies in the energy sector center their models on “Telemetry” fact tables that receive millions of rows of sensor data every hour. The star schema allows these organizations to connect these high-velocity facts to slowly changing dimensions like “Equipment Warranty Status” and “Maintenance Schedule.” This enables predictive maintenance reporting that alerts engineers before a machine fails, saving millions in downtime. For a beginner guide to building these insights, check our complete 2026 guide to your first dashboard.
📊 Mastering Data Analytics? Browse the AI Buzz Data Analytics Hub — essential guides covering DAX formulas, dashboard design, Microsoft Fabric, and AI-powered business intelligence.
📐 5. Decision Framework: Choosing Table Types and Grain
Building a correct star schema requires a disciplined decision-making process. The most important question to answer is: What is the grain of the fact table? The “grain” represents the lowest level of detail stored in the table. For instance, is one row in your sales table a whole order, or is it an individual line item on that order? Choosing the line-item grain is almost always the correct path, as it allows you to roll up data to any higher level while maintaining the ability to drill down into specifics. If you aggregate data too early (at the source), you lose the flexibility that Power BI provides.
The second pillar of the framework is determining Dimension Cardinality. In 2026, data models are increasingly using “High Cardinality” dimensions, such as individual user IDs or specific GPS coordinates. The rule of thumb: if a descriptive attribute changes frequently (like a customer’s current location), it might actually belong in a fact table as a snapshot. If it is a stable attribute (like a customer’s date of birth), it must live in a dimension table. This ensures your “One-to-Many” relationships remain performant and prevent the dreaded “Many-to-Many” relationship types that introduce ambiguity into report totals.
| User Persona | Recommended Table Structure | Relationship Strategy |
|---|---|---|
| BI Developer | Granular fact tables (Transaction level) | Strict 1:Many; Single Direction cross-filtering. |
| Executive Analyst | Aggregated “Snapshot” fact tables | Collapsed dimensions for high-level speed. |
| Power User | Hybrid (Granular facts + specific dims) | Limited “Bi-directional” filtering for edge cases. |
| Fabric Admin | Star Schema mapped to Parquet files | Direct Lake mode; auto-generated semantic models. |
🛠️ 6. How to Implement a Star Schema: A Step-by-Step Guide
Implementation begins in Power Query, not in the Relationship view. Your first step is to identify redundant data in your source system and “De-normalize” it into dimension tables. For instance, if you have a massive table of sales that contains the full address of every customer on every row, you should move those address columns to a dedicated “Customer” dimension table. You are left with a simple “CustomerKey” in your sales table. This reduces the data footprint significantly. For a technical walkthrough of building formulas once your tables are set, see 7 DAX formulas every Power BI beginner needs to know.
The second step is to establish Relationship Cardinality. In Power BI, you must ensure that your dimension tables have a unique list of values (the “1” side) and your fact tables have multiple occurrences of those values (the “Many” side). You should almost always set your Cross-Filter Direction to “Single.” While bi-directional filtering seems convenient, it can lead to “Circular Dependencies” and ambiguous data paths that return incorrect totals in complex reports. If you find yourself needing bi-directional filtering, it is often a sign that your data modeling needs further refinement.
Finally, every Power BI star schema requires a Dedicated Date Table. In 2026, relying on Power BI’s “Auto Date/Time” feature is considered a bad practice for enterprise reporting. A custom Date table allows you to perform “Time Intelligence” calculations like “Year-to-Date” or “Same-Period-Last-Year” with total precision. It also allows you to align your reporting with your company’s specific fiscal calendar, which often differs from the standard calendar year. Without a central Date dimension, your time-based DAX measures will frequently return errors or unexpected blanks.
⚠️ 7. Honest Limitations: Where Star Schemas Struggle
Despite being the gold standard, the star schema is not a magic bullet for every scenario. One major limitation is **Maintenance Overhead.** For small teams or solo analysts, the time required to build and maintain 10+ tables versus one flat table can be significant. In 2026, while AI tools like Claude Code and Copilot can automate much of the “Join” logic, the human developer still needs to audit the results for business logic errors. If your dataset is under 100,000 rows and doesn’t require complex time intelligence, a star schema might be over-engineering.
Another challenge is Slowly Changing Dimensions (SCDs). If a dimension attribute changes over time—such as a salesperson moving from the “West” region to the “East” region—the star schema requires specific strategies to track historical performance correctly. Simply updating the dimension table will overwrite history, making it look like the salesperson was always in the “East.” Managing these “Type 2” dimensions (where you keep a history of changes) adds a significant layer of ETL (Extract, Transform, Load) complexity that requires advanced data engineering skills.
Lastly, Many-to-Many Relationships remain a persistent thorn in the side of star schema design. There are certain business realities—like a single bank account having multiple owners, or a single patient having multiple diagnoses—that do not naturally fit into a one-to-many star. While Power BI 2026 features have improved the performance of many-to-many relationships, they still introduce a risk of “Double Counting” data. Developers must use “Bridge Tables” or specific DAX measures to ensure totals remain accurate, which breaks the simplicity of the standard star model. For help with these advanced scenarios, see our guide on Power BI DAX AI assistants.
🏁 8. Conclusion: Building Your Data Legacy in 2026
The Star Schema is the bridge between raw data and business wisdom. In the 2026 landscape of AI-augmented analytics and massive Fabric-driven data lakes, the “How” of data modeling has changed, but the “Why” remains identical: speed, accuracy, and clarity. A well-designed model allows your organization to move from simply “describing” what happened in the past to “predicting” what will happen in the future with high-fidelity insights. It turns your Power BI environment from a collection of laggy charts into a high-performance decision-making machine.
As you begin your data modeling journey, remember that the star schema is a discipline, not a one-time task. It requires constant refinement as your business evolves and new data sources are integrated. By prioritizing fact-dimension separation, enforcing strict one-to-many relationships, and utilizing a dedicated date table, you are future-proofing your reports against the scaling challenges of the next decade. The 2026 consensus is clear: those who master the star schema will lead the data-driven transformations of tomorrow. For your next step, explore our guide on Power BI row-level security to protect the model you’ve built.
📌 Key Takeaways
| ✅ | Takeaway |
|---|---|
| ✅ | A Power BI star schema organizes data into central fact tables (numbers) and surrounding dimension tables (context) for maximum performance. |
| ✅ | Modeling errors are responsible for 70% of enterprise report failures in 2026; Star schemas solve this by reducing memory consumption by up to 60%. |
| ✅ | AI tools like Microsoft Copilot require a clean star schema to map semantic meanings accurately and avoid hallucinating incorrect business totals. |
| ✅ | Always use “One-to-Many” relationships with “Single Direction” filtering to prevent ambiguous data paths and DAX calculation errors. |
| ✅ | A dedicated custom Date Table is mandatory for enterprise reports to enable precise Time Intelligence and fiscal-year reporting. |
| ✅ | Define your “Grain” at the lowest level of detail (line-item) to maintain total flexibility in roll-up and drill-down analysis. |
| ✅ | The Star schema is optimized for the VertiPaq columnar engine, enabling petabyte-scale analytics in Microsoft Fabric. |
| ✅ | For very small datasets (under 100k rows), a simple flat table may be sufficient, but star schema remains the gold standard for growth. |
🔗 Related Articles
- 📖 Power BI for Beginners: The Complete 2026 Guide to Your First Dashboard
- 📖 7 DAX Formulas Every Power BI Beginner Needs to Know
- 📖 Power BI Calculated Columns vs Measures: When to Use Each (2026)
- 📖 What Is Microsoft Fabric? How It Changes Power BI for Business Teams (2026)
- 📖 Power BI Row-Level Security (RLS) Explained: A Step-by-Step Admin Guide
FAQs
1. What is the difference between a fact table and a dimension table?
A fact table stores quantitative “events” like sales amounts or temperatures, while a dimension table stores descriptive “context” like product names or store locations. Our Power BI for beginners guide covers these basic setup steps in detail.
2. Why is bi-directional filtering discouraged in star schemas?
Bi-directional filtering can create “Circular Dependencies” where Power BI doesn’t know which data path to follow for a calculation, leading to ambiguous or flat-out incorrect report totals. Using DAX measures is a safer way to achieve complex cross-filtering without breaking the model.
3. Can I use a snowflake schema instead of a star schema?
While a snowflake schema (where dimension tables are normalized into further sub-tables) saves disk space, it is generally slower in Power BI because it requires the engine to perform more “joins” to display data. Stick to the star schema for optimal performance in 95% of use cases.
4. How does Microsoft Fabric change data modeling in 2026?
Microsoft Fabric introduces “Direct Lake” mode, which allows Power BI to read Parquet files directly from OneLake without importing them. This requires a star schema structure to work effectively, as the Parquet format is natively optimized for columnar, star-based storage.
5. Does every Power BI model need a custom date table?
Yes. Relying on Power BI’s built-in “Auto Date/Time” creates hidden tables that bloat your model and prevents you from doing advanced time calculations. A custom date table is essential for accurate fiscal reporting and reliable time-intelligence DAX.
📧 Get the AI Buzz Weekly Digest
Weekly AI insights, tools, and strategies — delivered every Monday. Free.
Leave a Reply