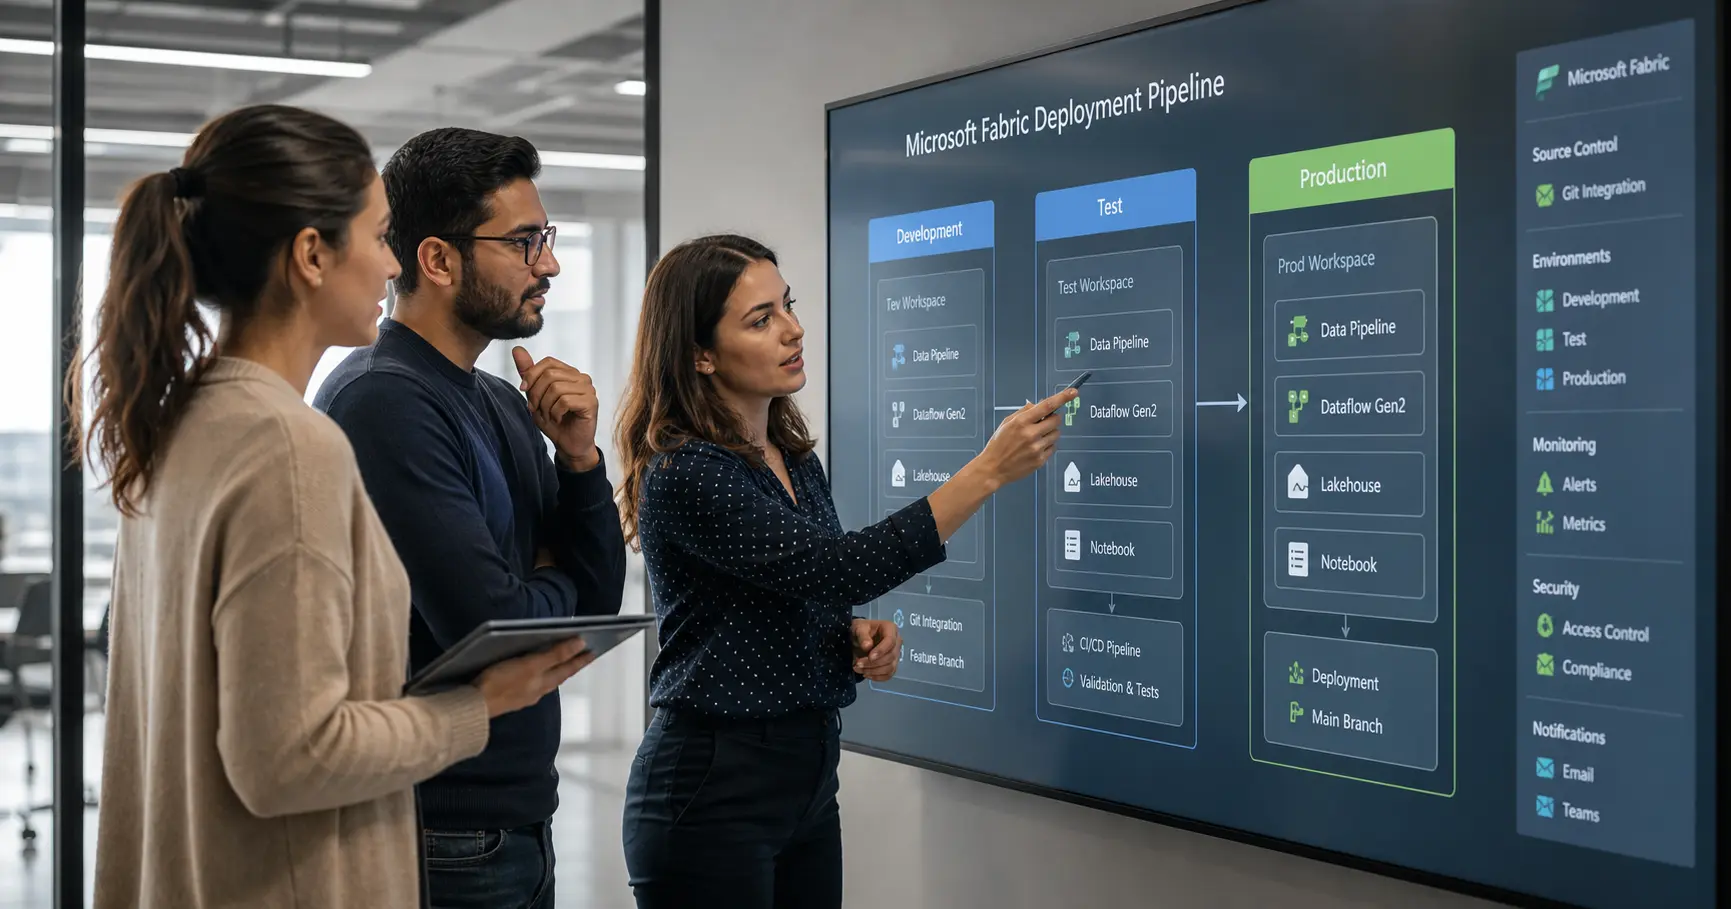
Power BI deployment pipelines are the enterprise standard for governing how reports, semantic models, and dashboards move from development through testing into production — safely, repeatably, and with a full audit trail that satisfies even the most demanding compliance requirements.
Last Updated: October 22, 2026
In 2026, deploying a Power BI report directly from a developer’s desktop into a production workspace is the analytical equivalent of pushing untested code straight to a live server. The consequences are real and recurring: a corrupted measure reaches the board deck, a misconfigured Row-Level Security role exposes sensitive payroll data to the wrong audience, or a schema change breaks a downstream AI agent that depends on a specific column name. According to Gartner’s 2026 Business Intelligence research, data quality issues originating from inadequate change management processes cost organisations an average of $12.9 million per year — a figure that underscores just how expensive the absence of a formal release process truly is.
Power BI deployment pipelines solve this problem by providing a structured, three-stage Application Lifecycle Management (ALM) framework built directly into the Microsoft Fabric ecosystem. Rather than relying on manual file exports, shared drives, and version-named PBIX files, deployment pipelines create a governed promotion chain: content moves from a Development workspace into a Test workspace for validation, and only reaches the Production workspace after it has been formally reviewed and approved. Data source connections are remapped automatically at each stage using deployment rules, eliminating the most common cause of production environments accidentally reading from test databases.
This guide provides a complete, practitioner-level reference for Power BI deployment pipelines in 2026. You will learn how the three-stage architecture works in practice, how to configure Git integration for full CI/CD capability, how to write deployment rules that handle every environment switch automatically, and how to use the Fabric REST API to automate pipeline operations at scale. By the end, you will have the architectural knowledge and the operational playbook to implement deployment pipelines across any size of enterprise — from a team of three analysts sharing a single F64 capacity to a global data engineering function managing dozens of pipelines across multiple regions.
Build Your Power BI and AI Vocabulary
From semantic models to agentic orchestration, our 100+ essential AI terms glossary gives you the language to lead data and AI conversations with confidence — free and fully searchable.
🗺️ What Are Power BI Deployment Pipelines?
A Power BI deployment pipeline is a managed, three-stage environment framework that connects a sequence of Fabric workspaces — Development, Test, and Production — into a single governed promotion chain. When a developer finishes a new report or updates a semantic model, that content does not go directly to the workspace that executives and business analysts use every day. Instead, it enters the pipeline at the Development stage, is promoted to the Test stage for structured validation, and only reaches Production after passing a formal review gate.
The pipeline preserves the full fidelity of every analytical asset — the report canvas, the semantic model schema, the data source connections, the Row-Level Security configuration, the scheduled refresh settings, and the sensitivity labels — as it moves between stages. At each promotion boundary, deployment rules automatically remap the data source connections so that the Test workspace queries a staging database and the Production workspace queries the live enterprise data warehouse. This happens without the developer having to open Power BI Desktop or manually update a connection string.
Prior to the Microsoft Fabric era, pipelines were available only on Power BI Premium Per Capacity (P-SKU) and Premium Per User (PPU) licences, which placed them out of reach for many mid-market organisations. The full migration to Fabric F-SKU capacity in 2026 has changed this. Pipeline functionality is now available to any workspace backed by a Fabric Capacity, making it the default expected architecture rather than a premium luxury. Organisations still operating on P-SKUs should be aware that P-SKUs are no longer recommended for new deployments — all new capacity planning should use F-SKU language and pricing.
Pipelines vs Manual Workspace Management
Before pipelines became the standard, Power BI teams managed releases through a combination of manual PBIX file exports, email handoffs, and shared drive folder structures with version-numbered filenames. The most common artefact of this era — a file named something like SalesReport_v4_FINAL_reviewed_USE_THIS_ONE.pbix — is a reliable indicator of a team operating without formal ALM. Pipelines eliminate every step of that process: version history is managed by Git, environment switching is managed by deployment rules, and access controls are enforced at both the workspace and pipeline permission level simultaneously.
🏗️ The Three-Stage Architecture: Development, Test, and Production
The three-stage pipeline model is not arbitrary. It maps directly to the stages of risk in the analytical lifecycle: the risk of incomplete or incorrect logic (addressed in Development), the risk of data accuracy and security configuration errors (addressed in Test), and the risk of operational failure in the live environment (mitigated by the rigour applied in both preceding stages). Each stage has a distinct purpose, a distinct set of authorised users, and a distinct set of data source connections — and none of those three dimensions should overlap between stages.
Development Stage
The Development workspace is the sandbox. Developers and data engineers build new reports, author new DAX calculated columns and measures, design new data models, and connect to development or synthetic data sources. Row counts in the Development semantic model should be deliberately limited using query parameters — loading a full decade of transactional data into a development model consumes Fabric Capacity Units unnecessarily and slows the iteration cycle. The goal of the Development stage is speed of experimentation, not completeness of data.
Test Stage
Promotion to the Test stage signals that the developer believes the content is ready for independent validation. The Test workspace is connected to a staging or UAT data environment that mirrors the structure and data types of Production as precisely as possible, populated with either fully representative data or carefully masked production data. In the Test stage, Subject Matter Experts (SMEs), QA analysts, and data stewards validate measure values against known benchmarks, check that calculated totals reconcile with source system reports, and — critically — verify that Row-Level Security role filters are behaving correctly for every defined security persona. An RLS misconfiguration that is invisible in Development can expose sensitive data to the wrong audience the moment the report reaches Production.
Production Stage
The Production workspace is the authoritative environment. It contains only content that has passed both preceding stages. Business analysts, executives, and operations users have Viewer or Contributor access; developers typically have Viewer access at most, with no direct write permissions. All content in Production is the product of a deliberate, validated release process — and that auditability is precisely what makes the pipeline architecture the correct approach for teams operating under governance frameworks that require evidence of data quality controls.
🔗 Git Integration and Full CI/CD Capability
The UI-based “Deploy” button in the pipeline interface is a valid starting point for teams new to ALM. But for any team managing more than a handful of pipeline items, or deploying with any frequency, it represents a manual bottleneck in what should be a fully automated release process. The 2026 gold standard is a CI/CD workflow in which every change to a semantic model or report is tracked as a commit in a Git repository — Azure DevOps Repos or GitHub — and pipeline promotions are triggered programmatically by a successful, automated build.
When a Fabric workspace is connected to a Git repository, Power BI serialises the workspace content into a structured folder of TMDL (Tabular Model Definition Language) files and JSON configuration files. Every schema change, every new measure, every report visual modification is reflected as a file delta in the repository. This means that the full suite of software engineering practices — pull requests, branch protection rules, mandatory peer review, automated linting — can be applied directly to Power BI analytical assets. A measure change that has not been reviewed by a second data engineer cannot merge to the release branch. A semantic model with unresolved schema conflicts cannot be promoted to Production. The pipeline enforces these gates automatically.
Recommended Branch Strategy
The recommended branch strategy for Power BI teams in 2026 is an analytics-adapted GitFlow. A protected main branch maps to the Production workspace. A release branch maps to the Test workspace. Individual developers work on short-lived feature branches, raised as pull requests against release for peer review. Once the release branch is validated in the Test workspace and formal stakeholder sign-off is recorded, a merge to main triggers the automated deployment to Production via the Fabric REST API. This keeps the entire promotion history immutable, auditable, and reversible — a revert of a merge commit restores the previous production state within minutes.
This level of version control integrity is especially important for teams whose semantic models and reports are consumed by non-human identities and AI agents. An undocumented schema change — a renamed measure, a deleted column — that breaks a human analyst’s report will be noticed and reported within hours. The same change silently breaking an automated agentic workflow may go undetected for days, compounding errors across every downstream process that depends on the data.
⚖️ Manual Deployment vs Fabric Deployment Pipelines: A Full Comparison
To understand the operational value of deployment pipelines, it is useful to compare the two approaches across every dimension that matters for enterprise analytics governance. The table below benchmarks the manual PBIX file workflow — still in use at a significant proportion of Power BI installations — against a fully implemented Fabric deployment pipeline with Git integration.
| Capability | Manual PBIX Workflow | Fabric Deployment Pipeline + Git |
|---|---|---|
| Version Control | Manual file naming (report_v4_FINAL_USE_THIS.pbix) | Native Git commit history, branching, and pull request workflow |
| Data Source Switching | Manual update in Desktop or Service — high error risk | Automated deployment rules — zero manual intervention required |
| RLS Validation | Ad hoc, frequently skipped under deadline pressure | Mandatory Test stage gate — RLS verified before every Production promotion |
| Rollback Capability | Recover the last saved PBIX file — often days out of date | Revert any Git commit — full state recovery in minutes |
| Audit Trail | Email chains and shared drive timestamps — not auditor-friendly | Immutable Git log plus Fabric Activity Events API — auditor-ready |
| Capacity Governance | Disjointed per-workspace F-SKU allocation — no unified view | Unified F-SKU governance across all three pipeline stages |
| Peer Review | Informal or absent — dependent on team culture | Enforced via Git branch protection and mandatory pull request approvals |
| Deployment Frequency | Limited by manual effort — typically weekly or less | Multiple daily deployments via REST API automation — safely |
⚙️ Deployment Rules: The Engine That Powers Every Pipeline
Deployment rules are the mechanism that allows the same semantic model to point at a development database in the Dev stage and the enterprise production data warehouse in the Prod stage — without the developer ever opening Power BI Desktop to manually change a connection string. Rules are defined at the pipeline level, scoped to specific items, and applied automatically every time a promotion is triggered.
Data Source Rules
Data source rules allow pipeline administrators to specify that when a semantic model is promoted from Test to Production, a specific connection property — the server hostname, the database name, the warehouse URL — should be overwritten with the production-appropriate value. A typical rule specifies that the ServerName parameter transitions from sql-uat.contoso.database.windows.net to sql-prod.contoso.database.windows.net upon promotion. Without this rule, the Production semantic model silently queries the UAT database — returning test data to real business users, with no error message to signal that anything is wrong.
Parameter Rules
Parameter rules operate on any M-query parameter defined within the semantic model, not just connection strings. They are significantly more powerful than they appear at first glance. Teams use parameter rules to control the historical date range used by incremental refresh policies by environment — a shorter window in Development to minimise capacity consumption, a full rolling window in Production. Parameter rules are also used to toggle feature flags controlling which experimental measures are exposed in which stage, and to specify the Lakehouse URL when deploying models that use Direct Lake storage mode against a OneLake endpoint.
The single most important architectural practice for any team planning to use deployment pipelines is this: every value that will differ between environments must be externalised as a named M-query parameter from the first day of model development. A model with hardcoded connection strings cannot have deployment rules applied to it. Retrofitting parameters into a complex model that is already in production is one of the most expensive and disruptive forms of analytical technical debt — requiring a full republish from Desktop, a pipeline reconfiguration, and a re-mapping of all existing deployment rules.
Reality check: If your Power BI model has even one hardcoded server name or database string, your deployment pipeline will fail at the first environment boundary. Build with parameters from day one — there is no cheaper time to do it than before the first line of DAX is written.
⚡ Automating Pipelines via the Fabric REST API
For teams managing large numbers of pipeline items or executing multiple deployments per day, the Fabric REST API provides programmatic control over every pipeline action available in the UI. API-driven automation removes the human bottleneck from the release process entirely: deployments are triggered automatically as a post-step in an Azure Pipelines YAML workflow or a GitHub Actions workflow, conditioned on the successful completion of all preceding validation steps.
Using the Fabric Deployment Pipelines REST API, operations teams can trigger selective deployments — promoting only specified items from a stage rather than the entire workspace — which is essential for managing large pipelines where only a subset of items have changed in a given release. The API also exposes the full deployment history for each pipeline, enabling automated audit reporting without requiring manual extraction from the Fabric portal.
Service Principal Authentication
All API-driven pipeline operations should authenticate using a service principal registered in Microsoft Entra ID, not a personal user account. Service principal authentication means that automated deployments are not tied to any individual employee’s credentials, are not disrupted by password changes or account deactivation, and provide a clean, identifiable entity in the Fabric Activity Events log for every action taken. The service principal should be granted the minimum pipeline and workspace permissions necessary to execute its designated operations — Fabric Capacity Admin rights are not required for pipeline automation and should never be assigned to a service principal performing deployment tasks.
Conditional Deployment Logic
The Fabric REST API enables conditional logic that is impossible to express through the UI’s Deploy button. An automation script can query the semantic model refresh history via the API, confirm that the most recent refresh completed with zero errors and returned a row count within the expected tolerance range, and only then trigger the promotion to Production. If the refresh failed, or if the row count deviates beyond the defined threshold — a signal of possible upstream data quality failure — the script halts the pipeline and triggers an alert to the on-call data engineer. This creates a self-guarding release process that catches data quality issues before they reach the Production workspace.
Explore the Full Power BI & Data Analytics Hub
From star schema design to composite model architecture and enterprise capacity governance, our Power BI hub covers the full analytical lifecycle for modern data teams. Browse the complete Power BI and Data Analytics guide collection →
🔐 Security, Permissions, and Separation of Duties
Pipeline permissions and workspace permissions are separate systems, and this distinction is one of the most frequently misunderstood aspects of deployment pipeline governance. A user can have Admin rights on the Development workspace and still be completely unable to trigger a promotion to Production if they have not been explicitly granted Pipeline Admin rights for that pipeline stage. This separation is not a bug — it is the foundation of a sound separation of duties model.
The recommended enterprise permission model for 2026 operates on the principle of least privilege across both dimensions simultaneously. Developers hold Member or Contributor rights in the Development workspace, allowing them to publish content from Power BI Desktop. They hold Viewer rights in the Test and Production workspaces — sufficient to see what is live, but insufficient to modify anything directly. A designated Release Manager, or a service principal configured for CI/CD automation, is the only identity authorised to trigger the promotion from Test to Production. In a mature pipeline organisation, no individual developer ever touches the Production workspace directly.
Compliance Implications for Regulated Environments
For teams operating in financial services, healthcare, public sector, or any other regulated domain, the pipeline’s immutable deployment history — accessible via the Fabric Activity Events API — provides a defensible evidence trail demonstrating that every report in Production was promoted through a validated release process. When combined with Row-Level Security governance at the semantic model level and the Fabric sensitivity label framework at the item level, this evidence trail satisfies the data access control documentation requirements of multiple regulatory frameworks.
As organisations extend analytical reporting into the governance of AI systems, the pipeline audit trail is also becoming the primary mechanism for demonstrating that AI agents are consuming only data assets that have passed a formal validation process. Teams working on agentic AI governance frameworks in 2026 are increasingly specifying that any dataset consumed by an autonomous agent must have a verifiable pipeline promotion history as a prerequisite for agent access authorisation.
🚨 Common Pitfalls and How to Avoid Them
Even experienced Power BI architects encounter avoidable failures when implementing deployment pipelines at scale. The following failure modes represent the highest-frequency issues observed across enterprise deployments in 2025 and 2026, and in every case the root cause is architectural rather than operational.
Schema Mismatch Errors
The most common deployment failure occurs when a report is promoted to the next stage but the underlying semantic model has drifted out of sync — either because the model was promoted at a different time, or because a developer made a direct change to the model in the destination workspace. The result is a schema mismatch: the report references a table, column, or measure that does not exist in the destination model. The resolution is architectural: always keep reports and their underlying semantic models at the same pipeline stage, and always promote the semantic model before or simultaneously with the reports that depend on it. Never allow direct edits to a semantic model in the Test or Production workspace.
Direct Lake Fallback on Deployment
When deploying semantic models that use Direct Lake storage mode, the deployment rule must correctly remap the model to the production Lakehouse endpoint. If the data source rule is missing or incorrectly configured, Direct Lake will fail to bind to the correct Delta tables in OneLake and will automatically fall back to DirectQuery mode. This fallback is silent — no error appears in the Fabric portal, and end-users simply experience slower query responses. Sub-second Direct Lake queries become multi-second DirectQuery queries overnight. Always verify the storage mode of every table in the Production semantic model immediately after a Direct Lake deployment, and monitor the composite model aggregation hit rate to confirm that fallback rates have not increased post-deployment.
Sensitivity Label Gaps in Production
Sensitivity labels assigned in the Development workspace are not automatically preserved through pipeline promotions by default. Without explicit configuration to carry labels through the promotion chain, content can arrive in Production without the appropriate classification — a confidentiality or regulatory compliance violation in any organisation operating under a mandatory data classification policy. Pipeline administrators must configure label preservation as part of the pipeline setup, not as an afterthought.
📊 F-SKU Capacity Planning Across Pipeline Stages
Every workspace in a deployment pipeline must be backed by a Fabric Capacity (F-SKU) or Power BI Premium Per User (PPU) licence. In practice, most organisations assign all three pipeline workspaces to the same Fabric Capacity and rely on dynamic Capacity Unit (CU) allocation to manage the workload. This works well for teams with sequential development and testing cycles, where the three stages are rarely under heavy load simultaneously.
For organisations managing very large semantic models — particularly those using composite models with Import-mode aggregation tables at billion-row scale — the Development workspace should be on a separate, lower-tier capacity than Production. A heavy development refresh competing for CUs with the Production environment will cause user-facing query latency on the live reports. An F16 or F32 for Development and Test, paired with an F64 or F128 for Production, is a common configuration for enterprise analytics functions operating at this data scale. The Microsoft Fabric Capacity Metrics app provides a per-item CU breakdown across all workspaces on a given capacity and is an essential tool for identifying pipeline-triggered operations consuming disproportionate resources.
🔮 The Future of Power BI ALM: Automated Testing and AI-Assisted Releases
The next maturity frontier for Power BI deployment pipelines is automated, data-aware testing — the ability to assert, before a promotion is permitted, that key measures in the new version of a semantic model return values within an acceptable tolerance of the previous version. This is the analytical equivalent of unit testing in software development, applied to DAX business logic rather than application code.
Community-built tooling, including the Best Practice Analyser within Tabular Editor, is already being integrated into Power BI CI/CD pipelines to run automated quality checks on semantic model metadata before a promotion is triggered — flagging measures without descriptions, detecting unused tables, and identifying relationships with ambiguous cross-filter direction. Microsoft is expected to expose native test assertion capabilities through the Fabric REST API in 2027, allowing teams to store a suite of expected measure values as a YAML configuration file in Git and run those assertions as an automated gate in every pipeline promotion.
At the same time, the broader shift toward AI-augmented analytics in Power BI means that pipelines will increasingly need to govern AI-generated content — Copilot-authored reports, natural-language measure descriptions, AI-suggested visual layouts — as first-class pipeline items subject to the same validation standards as hand-crafted analytical assets. The teams that build robust pipeline disciplines today are building the governance infrastructure that will make AI-assisted analytics safe and auditable as those capabilities continue to mature through 2027 and beyond.
📌 Key Takeaways
| ✅ | Takeaway |
|---|---|
| ✅ | Deployment pipelines are the 2026 baseline — not a premium extra. With P-SKUs retired for new deployments, any workspace on Fabric F-SKU capacity can implement a governed Dev-Test-Prod pipeline as the default way to manage analytical content. |
| ✅ | Deployment rules are the non-negotiable core of every pipeline. Data source rules and parameter rules must be configured from day one. Hardcoded connection strings cannot be governed by rules and will cause every environment boundary to fail silently. |
| ✅ | Git integration transforms pipelines from a UI tool into a full CI/CD system. Branch protection, mandatory pull request review, and automated build triggers bring software engineering rigour to analytical asset management for the first time. |
| ✅ | Pipeline permissions and workspace permissions are entirely separate systems. A developer with Admin rights on the Development workspace cannot promote to Production without explicit Pipeline Admin rights on that stage — by design. This separation of duties is the governance backbone of a compliant release process. |
| ✅ | Direct Lake deployments require explicit data source rules for every Lakehouse endpoint. A missing or incorrect rule triggers silent fallback to DirectQuery mode — no error, just significantly degraded query performance that may go undetected without post-deployment storage mode verification. |
| ✅ | The Fabric REST API enables fully automated, conditional pipeline promotions. Service principal-authenticated deployments triggered by Azure Pipelines or GitHub Actions — conditioned on refresh success and data quality validation — eliminate the human bottleneck from the release process entirely. |
| ✅ | The pipeline audit trail is becoming a core requirement for AI governance. As agentic AI frameworks mature, regulators and internal risk teams are requiring evidence that AI agents consume only analytically validated, pipeline-promoted data assets — making the deployment pipeline the frontline of AI data governance. |
🔗 Related Articles
- 📖 Power BI Import vs DirectQuery vs Direct Lake: The 2026 Storage Mode Comparison
- 📖 Power BI Incremental Refresh Explained: Optimising Large Dataset Refreshes
- 📖 Power BI Composite Models and Aggregations: A Performance Architecture Guide
- 📖 What Is Microsoft Fabric? The Unified Data Platform Explained for 2026
- 📖 Power BI Row-Level Security: A Complete Implementation Guide
FAQs
1. Which Power BI license is required to use deployment pipelines in 2026?
Deployment pipelines are a Premium feature. In the current Fabric-centric landscape, you need a workspace assigned to either a Power BI Premium Per User (PPU) license or a Microsoft Fabric Capacity (F-SKU). Full automation through APIs generally requires an F64 SKU or higher.
2. Can I use deployment pipelines with Power BI Pro?
No, Power BI Pro users cannot create or manage deployment pipelines. However, a Pro user can be a viewer of the content in a Production workspace if that workspace is backed by an F-SKU capacity. For the management of the lifecycle itself, PPU or Fabric Capacity is mandatory.
3. How do deployment pipelines handle Row-Level Security (RLS)?
The pipeline preserves the RLS roles defined in your semantic model metadata. However, you must ensure that the users or security groups assigned to those roles in the “Test” workspace are also assigned in the “Production” workspace. It is highly recommended to validate RLS roles in the Test stage before finalizing the deployment.
4. Does Git integration replace the need for deployment pipelines?
No, they are complementary. Git integration handles version control and code-level changes (the “what”), while deployment pipelines handle the promotion between environments and data source swapping (the “where”). Using both together provides a complete CI/CD solution.
5. What happens to my data when I deploy a report?
Deploying a report only updates the metadata (the visual layout and report settings). If you deploy a semantic model, it replaces the metadata of the destination model. The actual data is not “moved” from Dev to Prod; instead, the deployment rules tell the destination model to refresh its data from the production source.
📧 Get the AI Buzz Weekly Digest
Weekly AI insights, tools, and strategies — delivered every Monday. Free.
Leave a Reply