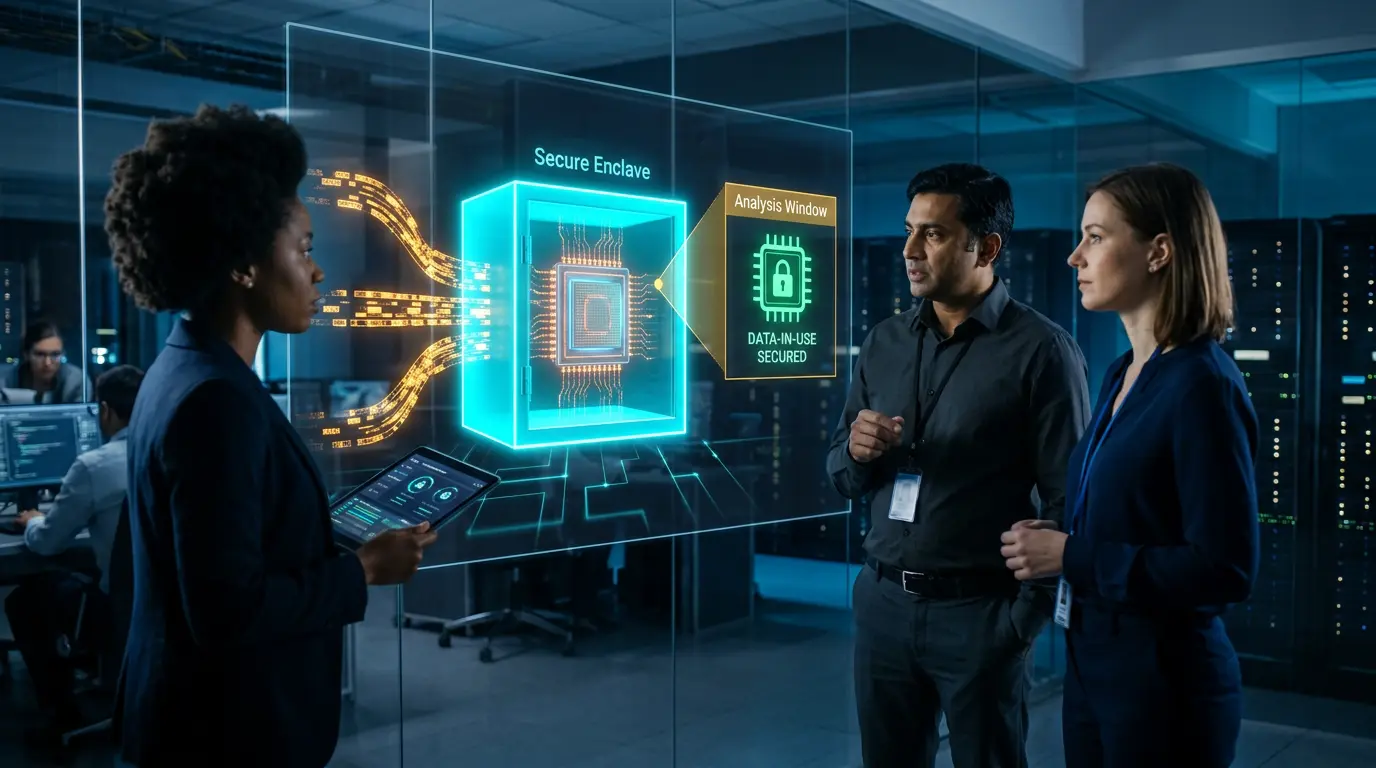
🔐 Most encryption protects data at rest and in transit — but leaves data completely exposed while it is being processed. Confidential Computing closes that gap. This guide covers how Trusted Execution Environments work, why confidential computing is now central to AI governance and regulatory compliance in 2026, which cloud platforms support it, and how to evaluate whether your AI pipeline needs it.
Last Updated: October 10, 2026
Every organization that handles sensitive data understands the importance of encryption. Data at rest — stored in databases, file systems, and backups — is encrypted. Data in transit — moving across networks and APIs — is encrypted with TLS. These protections are baseline requirements, and virtually every organization with a functioning security program has them in place. But there is a critical gap in this encryption model that is particularly dangerous for AI workloads: what happens to data when it is actually being processed?
When a computer processes data — when a machine learning model is running inference, when an AI is analyzing a patient’s medical record, when a financial model is processing a transaction — that data must be decrypted and loaded into memory. In conventional computing environments, this creates a window of vulnerability: the data exists in plaintext in the processor’s memory, accessible to anyone with sufficient access to the underlying hardware or hypervisor. For most workloads, this risk is managed through strong access controls. For the most sensitive AI workloads — those processing medical records, financial data, legal documents, classified information, or proprietary business intelligence — this vulnerability is unacceptable.
Confidential Computing closes this gap. According to the Confidential Computing Consortium’s technical framework, Confidential Computing uses hardware-based security mechanisms to protect data while it is actively being processed — in what the industry calls a Trusted Execution Environment (TEE). The TEE creates a protected enclave in the processor where data and code execute in an isolated environment that is protected even from the cloud provider’s infrastructure administrators, the hypervisor, and the operating system itself.
This guide covers the technical mechanisms, AI use cases, hardware and cloud implementations, 2026 regulatory drivers, and governance framework for Confidential Computing in 2026. For related AI infrastructure topics, see our guides on Edge AI (AI processing at the network edge), Physical AI (robots and autonomous systems), Sovereign AI and Resilience (protecting workflows from cloud dependency), and Small Language Models (efficient models for on-device deployment).
📖 New to AI terminology? Visit the AI Buzz AI Glossary — 100+ essential AI terms explained in plain English, each linking to a full in-depth guide.
1. 🔐 Why Confidential Computing Matters More in 2026 Than Ever Before
The case for Confidential Computing has strengthened significantly in 2026 — driven by three converging forces: a more aggressive AI threat landscape, tighter regulatory requirements that explicitly address data-in-use protection, and the explosive growth of AI workloads processing regulated data in cloud environments. Organizations that treated confidential computing as a specialized capability for defense and intelligence contexts in 2023 are now being asked to deploy it across healthcare, financial services, and legal AI workloads by regulators, auditors, and enterprise procurement teams.
Three specific 2026 threat vectors make this urgency concrete. First, AI model theft during inference: attackers are increasingly targeting model weights during inference — a proprietary model representing hundreds of millions of dollars in training compute is exposed during every API call in a standard cloud environment. Second, prompt injection in multi-tenant environments: in shared cloud infrastructure, cross-tenant data leakage during LLM inference is a documented attack surface — prompts containing sensitive data can potentially be observed by co-tenants or infrastructure operators. Third, regulatory data residency requirements: the EU AI Act, GDPR, and HIPAA all require demonstrable data protection during processing — not just at rest — and standard cloud encryption cannot satisfy this requirement for data in use.
The shift is visible in enterprise procurement. Security questionnaires from healthcare networks, financial institutions, and government agencies now routinely include questions about confidential computing capabilities for AI vendors processing sensitive data. Shadow AI — employees using unauthorized AI tools that route sensitive data through uncontrolled platforms — creates exactly the data-in-use exposure that confidential computing prevents. Our Shadow AI guide covers the governance controls that work alongside confidential computing to address unsanctioned AI tool use. For a structured assessment of whether your current AI stack has a data-in-use gap, use the AI Audit Checklist.
2. 🎯 The Problem Confidential Computing Solves
To understand why Confidential Computing matters for AI, it helps to map the full threat surface of a conventional AI workload in a cloud environment — and identify the specific gap that existing security controls leave unaddressed.
The Three States of Data and Their Protections
| Data State | Where It Occurs | Standard Protection | Remaining Vulnerability |
|---|---|---|---|
| Data at Rest | Stored in databases, file systems, object storage | AES-256 encryption, access controls | Key management risk; privileged administrator access |
| Data in Transit | Moving across networks and APIs | TLS 1.3 encryption, certificate management | Certificate authority risk; TLS termination exposure |
| Data in Use | Loaded into CPU memory during active processing | Access controls only — no encryption protection | Exposed to hypervisor, OS, cloud provider, and physical memory attacks |
The “Data in Use” row represents the critical gap — and it is particularly significant for AI workloads because AI processing is computationally intensive, long-running, and frequently involves the most sensitive data an organization holds. A large language model running inference on medical records may process that data in memory for extended periods. A fraud detection AI analyzing financial transactions processes an enormous volume of sensitive financial data continuously. In a conventional cloud environment, all of this data exists in plaintext in memory — accessible to anyone with sufficient privilege on the underlying infrastructure.
The Threat Actors That Concern Organizations Most: For many organizations, the threat is not external hackers — their cloud infrastructure security is strong enough to prevent most external intrusion. The threat that Confidential Computing addresses is the privileged insider at the cloud provider, the rogue administrator with hypervisor access, the nation-state actor that has compromised cloud infrastructure, and the software supply chain attack that installs a kernel module designed to exfiltrate data from memory. None of these threats can be addressed by conventional encryption alone.
3. 🏗️ How Confidential Computing Works: Trusted Execution Environments
Confidential Computing uses hardware-enforced isolation to create protected execution environments — enclaves — within the processor where data and code are protected by the hardware itself rather than by software controls that privileged users can bypass.
The Core TEE Architecture
A Trusted Execution Environment works by dividing the processor’s execution environment into two distinct zones:
- The Normal World (Rich Execution Environment): The conventional computing environment where the operating system, hypervisor, and standard applications run. This environment can be configured and controlled by cloud providers, system administrators, and application operators — making it potentially accessible to anyone with sufficient privilege.
- The Secure World (Trusted Execution Environment): A hardware-isolated enclave where sensitive code and data execute. The CPU’s hardware security mechanisms prevent any software running in the Normal World — including the operating system, the hypervisor, and even the cloud provider’s management infrastructure — from accessing the memory or execution state of code running in the TEE.
The isolation is enforced by the processor hardware — not by software that could be bypassed by a privileged user. Even if an attacker has complete control of the host operating system and hypervisor, they cannot read the contents of a TEE’s protected memory or observe its execution state.
Remote Attestation: Proving the TEE is Trustworthy
One of the most powerful capabilities of Confidential Computing is remote attestation — the ability to cryptographically prove to a remote party that a specific piece of code is running in a genuine TEE, that it has not been tampered with, and that it is operating on hardware with the required security properties.
Remote attestation works as follows:
- The TEE generates a cryptographic measurement — a hash — of the code and configuration loaded into the enclave.
- This measurement is signed by the processor’s hardware attestation key — a private key that is burned into the processor during manufacturing and that only the processor hardware can access.
- The signed measurement is presented to the remote party — for example, a healthcare data provider deciding whether to share sensitive patient data with an AI system.
- The remote party verifies the signature against the processor manufacturer’s public attestation certificate — confirming that the measurement was genuinely produced by a legitimate TEE hardware component and that the code running in the TEE matches what was expected.
Remote attestation enables a new model of data sharing: a data owner can share sensitive data with an AI system running in a TEE — not because they trust the operator of that AI system, but because they have cryptographic proof that the AI code is running in a genuine, unmodified TEE that cannot expose the data to anyone, including the AI system’s operator.
TEE vs. Homomorphic Encryption vs. Secure Multi-Party Computation
Confidential Computing using TEEs is not the only technical approach to protecting data in use — but it is the most mature and production-ready in 2026. Understanding how it compares to alternatives helps organizations select the right approach for their specific AI workload requirements.
| Technology | How It Works | 2026 Maturity | Performance Cost | Best For |
|---|---|---|---|---|
| TEE (Confidential Computing) | Hardware-isolated execution environment — CPU enforces isolation | ✅ Production-ready | Low–Medium (5–15%) | AI inference, training, model IP protection |
| Homomorphic Encryption | Mathematical operations performed directly on encrypted data | ⚠️ Limited use cases | Very High (100–10,000x) | Simple aggregations on encrypted data only |
| Secure Multi-Party Computation | Computation split across multiple parties — no single party sees full data | ⚠️ Complex to deploy | High (10–100x) | Multi-party key management, threshold signing |
4. ☁️ Confidential Computing in Cloud AI Environments
All three major cloud providers — Microsoft Azure, Google Cloud, and Amazon Web Services — offer Confidential Computing services in 2026. Understanding the specific offerings and their AI applicability is essential for organizations evaluating deployment options.
Microsoft Azure Confidential Computing
Azure offers the broadest Confidential Computing portfolio of any major cloud provider — including Confidential Virtual Machines based on AMD SEV-SNP, Intel TDX Confidential VMs, and Azure Confidential Ledger for tamper-evident data storage. For AI workloads, Azure’s confidential GPU computing capability — which extends confidential computing protections to GPU memory, enabling AI model inference to occur in a protected hardware environment — represents the most significant 2026 advancement for large model deployment.
Microsoft’s integration of Confidential Computing with Azure AI services enables organizations to run inference on large language models against sensitive data — with cryptographic guarantees that neither Microsoft nor other tenants can access the data during processing. Azure Confidential Computing carries FedRAMP High authorization — making it the most commonly referenced confidential computing pathway for federal agency AI deployments. According to IBM’s confidential computing research, hardware-enforced TEE isolation is now the industry baseline for regulated AI workload protection.
Google Cloud Confidential Computing
Google Cloud’s Confidential VM service — based on AMD SEV-SNP — provides VM-level memory encryption for AI workloads. Google’s Confidential Space service extends this to enable secure multi-party computation scenarios — where multiple organizations can contribute sensitive data to a shared AI model without any party being able to access the other parties’ raw data.
This multi-party computation capability is particularly significant for AI training scenarios where multiple organizations want to train a shared model on their combined data — without sharing the raw data itself. A consortium of banks wanting to train a shared fraud detection model on their combined transaction data, without sharing that data with each other, is the canonical use case. Google Confidential GKE Nodes allow running containerized AI workloads in TEEs without application code changes — the lowest friction path for ML teams migrating existing Kubernetes-based AI pipelines.
AWS Nitro Enclaves
AWS Nitro Enclaves provide isolated compute environments within EC2 instances — using the Nitro security chip to create enclaves with no persistent storage, no interactive access, and restricted network connectivity. Nitro Enclaves are designed for processing highly sensitive data with cryptographic attestation — enabling AI workloads that must demonstrate to data owners that their data is being processed in a trusted, isolated environment. AWS takes a different architectural approach from Intel TDX and AMD SEV-SNP — isolated virtual machines rather than CPU-level TEEs — with lower performance overhead but fewer hardware attestation options for cross-cloud verification scenarios.
| Provider | TEE Technology | Confidential AI Offering | FedRAMP / Regulated |
|---|---|---|---|
| Microsoft Azure | Intel TDX / AMD SEV-SNP | Azure Confidential VMs, Confidential GPU Computing | ✅ FedRAMP High |
| Google Cloud | AMD SEV-SNP / Intel TDX | Confidential VMs, Confidential GKE Nodes, Confidential Space | ✅ FedRAMP High |
| AWS | AWS Nitro Enclaves (custom model) | Nitro Enclaves, Nitro System | ✅ FedRAMP High |
| IBM Cloud | IBM Secure Execution (s390x) | IBM Hyper Protect Services | ✅ FedRAMP Moderate |
(Authorization status as of October 2026 — verify current status at marketplace.fedramp.gov before procurement)
🔐 What Is Confidential Computing for AI Workloads — and How Does It Protect Data in Use?
Most data protection guidance focuses on two states of data: data at rest (encrypted in storage) and data in transit (protected by TLS across networks). For the majority of business applications, this two-layer approach is sufficient. But AI workloads break that model — because AI processing is the moment when sensitive data is most exposed. When a model runs inference on a medical record, a fraud detection system analyzes a transaction, or a legal AI parses a confidential contract, that data must be fully decrypted and loaded into processor memory to be worked on. In a standard cloud environment, that means the data exists in plaintext in RAM — visible in principle to anyone with privileged access to the underlying infrastructure.
Confidential computing for AI workloads solves this specifically. It does not simply extend at-rest or in-transit encryption into the processing layer — it replaces the software-trust model with a hardware-trust model. Rather than relying on cloud provider access controls (which can be bypassed by privileged insiders, compromised hypervisors, or nation-state actors with infrastructure access), confidential computing uses the processor itself as the security boundary. The hardware creates and enforces an isolated region — a secure enclave — where AI code and data execute, and where the processor’s own circuitry prevents anything outside the enclave from reading its contents, regardless of how much software-level privilege that external party holds.
Trusted Execution Environment (TEE) — Plain English: A TEE is a hardware-protected zone inside a processor where code runs and data is processed in complete isolation. No operating system, no hypervisor, no cloud administrator, and no co-tenant on shared infrastructure can read what is happening inside a TEE. The protection is enforced by the processor hardware — not by software policies that a privileged user could override.
For AI workloads specifically, TEEs protect three distinct assets that are all present during active processing. First, inference inputs — the sensitive data sent to the model (patient records, financial transactions, legal documents) — which exist in memory during every inference call. Second, model weights — the trained parameters representing the AI model itself, which may represent significant intellectual property and are loaded into memory at inference time. Third, intermediate computations — the activation values and attention states produced during transformer model inference, which can in some cases leak information about both the input data and model architecture. TEEs protect three critical AI assets simultaneously: training data, model weights, and inference queries.
The distinction between confidential computing and conventional cloud encryption is not a matter of degree — it is a matter of trust architecture. Conventional cloud encryption trusts the cloud provider’s key management and access control systems to prevent unauthorized access. Confidential computing removes the cloud provider from the trust chain entirely: composite attestation across CPU TEE and NVIDIA H100/H200 GPU confidential computing, with attestation-gated key release patterns, means the cloud provider cannot access the data even in principle. This is the architectural shift that makes confidential computing relevant to regulated AI workloads where the threat model includes the infrastructure operator — not just external attackers. For a complementary approach that protects individual privacy in model outputs rather than the processing environment itself, see our guide on Differential Privacy for AI.
In 2026, the practical availability of this protection has expanded significantly. Generative AI has become the dominant adoption driver: training and inference workloads increasingly touch proprietary model weights and regulated training data simultaneously, and confidential GPU support — NVIDIA H100 and, more recently, RTX PRO 6000 Blackwell — has made TEE protection practical for AI workloads rather than just batch cryptographic operations. What was a specialized security control for the most sensitive defense and intelligence AI workloads two years ago is now a deployable cloud service for healthcare, financial services, and legal AI pipelines.
🏗️ Which Product Categories Provide Secure Enclave or Confidential Computing for Sensitive AI Workloads?
The confidential computing market for AI workloads has matured from a single hardware category into a layered product ecosystem spanning cloud infrastructure, containerized deployment, on-premises hardware, and GPU-level protection. Understanding which product category addresses which layer of your AI pipeline — and which combinations are required for full data-in-use protection — is the first procurement decision organizations face.
The most important architectural point for AI teams: CPU-level confidential computing alone is insufficient for GPU-accelerated AI workloads. If your model runs on a GPU — which is true for virtually every large language model and most modern transformer-based AI systems — you need GPU-level confidential computing in addition to CPU TEE protection. A complete confidential computing deployment for AI inference requires a hardware-backed TEE at the CPU layer (AMD SEV-SNP or Intel TDX), a CC-capable GPU (H100 or H200 in confidential mode), and an attestation chain that gates key release rather than trusting the VM at boot. Each layer without the others leaves a gap in the protection model.
| Category | Example Products (2026) | FedRAMP Status | Best For |
|---|---|---|---|
| Cloud Confidential VMs | Azure DCasv6/ECasv6, GCP C3 (AMD SEV-SNP), Azure Intel TDX DCesv6 | Verify: marketplace.fedramp.gov | General AI workloads; lowest-friction migration from standard VMs |
| Confidential Containers | Azure Confidential Containers (ACC), Google Confidential GKE Nodes, AWS Nitro Enclaves | Verify: marketplace.fedramp.gov | Containerized inference pipelines; Kubernetes-based ML workflows |
| On-Premises TEE Hardware | Intel TDX (4th+ Gen Xeon), AMD SEV-SNP (EPYC Milan/Genoa/Turin) | N/A — on-premises | Regulated data that cannot leave premises; air-gapped environments |
| GPU Confidential Computing | NVIDIA H100/H200 (Hopper CC mode), NVIDIA B200/GB200 (Blackwell), GCP a3-highgpu with Intel TDX + H100 | N/A — hardware feature | LLM inference, transformer model training, any GPU-accelerated AI on sensitive data |
| Multiparty Clean Rooms | Azure Confidential Clean Rooms (preview, June 2026), Google Confidential Space | Verify: marketplace.fedramp.gov | Multi-org AI training without raw data sharing; consortium model development |
(FedRAMP authorization status as of October 2026 — always verify current status at marketplace.fedramp.gov before procurement decisions)
A critical procurement distinction: AWS, Azure, and GCP have converged on the same broad goal but diverged sharply on architecture. AWS builds confidentiality into the Nitro System by default and layers isolated enclaves on top; Azure and GCP both offer discrete “Confidential VM” products built on AMD SEV-SNP and Intel TDX. This means a lift-and-shift migration from Azure Confidential VMs to AWS Nitro Enclaves is not straightforward — the attestation models, enclave boundaries, and application compatibility profiles differ materially. Organizations should evaluate cloud provider lock-in risk alongside the security properties themselves.
For GPU-accelerated AI specifically, the hardware generation requirement is non-negotiable. Confidential computing for GPU inference is supported on NVIDIA H100 SXM5 and PCIe (Hopper architecture), H200 SXM5, and Blackwell-generation B200 and GB200 — older A100 or consumer GPUs do not support GPU confidential computing at all, so teams must verify the specific SKU before provisioning, not just the GPU family name. Google Cloud’s a3-highgpu instances, confirmed generally available since July 2025, pair Intel TDX with NVIDIA H100 for containerized confidential AI workloads — one of the most accessible entry points for ML teams running Kubernetes-based inference pipelines.
For organizations managing AI supply chain risk alongside data-in-use protection, confidential computing integrates directly with software supply chain security controls — attestation measurements verify not just that a TEE is present, but that the specific, signed, audited model code is what is running inside it. Our guide to AI Supply Chain Security covers how attestation integrates with model signing and provenance verification across the full AI pipeline.
☁️ Which Managed AI Platforms Support Confidential Computing for Private Model Training and Secure Data Processing?
The most significant shift in the confidential computing for AI market in 2026 is the emergence of managed AI platform services that layer confidential computing protections directly into AI inference and training APIs — removing the requirement for ML teams to configure raw TEE infrastructure themselves. Rather than standing up a confidential VM and deploying a model server manually, organizations can increasingly invoke confidential computing protections through managed AI platform controls. The trade-off is that managed services provide less visibility into the attestation chain — a factor that matters for the most sensitive regulated workloads.
Azure AI Confidential Inferencing
Microsoft has been the most active cloud provider in bringing confidential computing to managed AI services. Azure AI Confidential Inferencing — currently in preview expansion — extends TEE protection to Azure OpenAI inference calls, so that customer prompts and model completions are protected during processing even from Microsoft infrastructure personnel. Microsoft has committed to expanding confidential inferencing to support a broader range of models and other scenarios including confidential Retrieval-Augmented Generation (RAG), confidential fine-tuning, and confidential model pre-training. For organizations using RAG pipelines to ground LLMs in sensitive internal documents — a pattern that creates a significant regulated data exposure surface — confidential RAG represents the most complete technical solution available in 2026. This connects directly to the privacy surface discussed in our Retrieval-Augmented Generation guide.
In February 2026, Microsoft launched general availability of AMD SEV-SNP DCasv6 and ECasv6 confidential VMs in Azure Government, and announced general availability of Azure Intel TDX confidential VMs across the DCesv6, DCedsv6, ECesv6, and ECedsv6 series — giving regulated-industry AI teams a production-ready foundation for confidential AI workloads with FedRAMP-relevant authorization. In May 2026, Microsoft announced general availability of Azure Integrated HSM (AIH), strengthening hardware-backed key protection for sensitive and regulated workloads.
Google Cloud Confidential AI
Google Cloud’s confidential AI offering centers on Confidential GKE Nodes and Confidential Space — the latter enabling multi-party computation scenarios where multiple organizations contribute data to a shared AI model without any party being able to observe another’s inputs. Google has added support for accelerator-optimized instances for securely running AI and ML workloads, including configurations with NVIDIA RTX PRO 6000 GPU on 5th Generation AMD EPYC Turin processors with AMD SEV. One important limitation: Google’s TPUs do not yet support confidential computing — organizations running TPU-accelerated AI workloads on Google Cloud cannot currently achieve GPU-level TEE protection for those workloads and should factor this into hardware selection decisions.
OpenAI Private Intelligence (Announced October 2026)
OpenAI is expanding its zero-data-retention infrastructure with a new initiative called Private Intelligence, pairing an enhanced privacy-preserving safety review system with a forthcoming confidential-computing architecture designed to make AI inference itself more private and verifiable — unveiled at OpenAI’s DevDay 2026, as data leakage and IP exposure concerns became more concrete for enterprise customers. Private Inference, combining confidential computing with strict verifiable controls, is coming this fall. For organizations using the OpenAI API for sensitive workloads, this represents the first move by a frontier model provider toward hardware-backed inference privacy — a development that changes the vendor evaluation calculus for enterprise AI procurement teams.
AWS Nitro for AI Workloads
AWS Nitro Enclaves provide isolated compute environments within EC2 instances with no persistent storage and restricted network connectivity — designed for processing highly sensitive data with cryptographic attestation before any model weights or inference inputs are decrypted. AWS also offers attestation that cryptographically verifies trusted software is running before model weights are decrypted. AWS’s approach differs architecturally from Intel TDX and AMD SEV-SNP: Nitro uses isolated virtual machines rather than CPU-level memory encryption, which produces lower performance overhead but limits cross-cloud attestation verification options for organizations requiring multi-cloud confidential computing.
When NOT to Use Confidential Computing
Confidential computing is not the right control for every AI workload — and deploying it unnecessarily adds cost, complexity, and latency without corresponding security benefit. Avoid confidential computing when:
- The data being processed is not sensitive: AI workloads using only public data, anonymized data, or non-regulated internal data do not benefit from confidential computing — standard cloud security controls are sufficient and significantly cheaper.
- Budget constraints make the hardware premium prohibitive: Confidential GPU hardware (H100/H200 in CC mode) carries a meaningful cost premium over standard GPU instances. For development, testing, and non-production AI environments, this cost is not justified by the security benefit.
- Latency requirements cannot absorb even marginal overhead: For ultra-low-latency inference workloads where even 1–3% throughput reduction breaks SLA targets, evaluate application-layer controls and data minimization approaches before adding TEE overhead.
- The primary threat is application-layer attacks: Confidential computing protects the infrastructure layer — it does not prevent prompt injection, insecure output handling, or model inversion attacks on inference outputs. These require application-layer controls covered in our guide to AI Privacy by Design.
5. 🏥 The AI Use Cases That Require Confidential Computing
Confidential Computing is not necessary for every AI workload — but for specific categories of AI deployment, it is increasingly a baseline requirement rather than an advanced option.
Healthcare AI: Protected Patient Data Processing
Healthcare AI — diagnostic models, clinical decision support, drug discovery, genomic analysis — requires processing some of the most sensitive personal data in existence. HIPAA in the United States, GDPR in the EU, and equivalent regulations globally impose stringent requirements on how patient data is protected during processing.
Confidential Computing enables healthcare organizations to use cloud AI infrastructure for clinical workloads without exposing patient data to cloud provider personnel or infrastructure administrators — addressing one of the most significant barriers to cloud AI adoption in healthcare. A hospital system using AI for radiology image analysis can run that analysis on cloud GPU infrastructure with cryptographic guarantees that the patient images are protected during processing — satisfying HIPAA’s minimum necessary and safeguarding requirements. This connects to the broader healthcare AI applications covered in our guide on AI in Healthcare and MedTech.
Financial Services AI: Protecting Trading and Transaction Data
Financial services AI — fraud detection, risk modeling, algorithmic trading, credit scoring — processes data whose exposure carries both regulatory consequences and competitive intelligence risks. Trading algorithms represent significant intellectual property; transaction data reveals customer financial behavior patterns that could be exploited if accessed by competitors or adversaries.
Confidential Computing enables financial institutions to run AI workloads on cloud infrastructure without exposing proprietary model logic or customer financial data to infrastructure operators. The remote attestation capability also enables financial institutions to prove to regulators that their AI processing occurs in a verified, tamper-resistant environment — supporting compliance with regulatory requirements for algorithmic transparency and data protection.
Multi-Party AI Training: Collaborative Learning Without Data Sharing
One of the most significant AI challenges is that the best models require the most data — but the most valuable data is often siloed in organizations that cannot share it due to competitive, regulatory, or privacy constraints. Confidential Computing enables a new paradigm: multiple organizations contribute their data to a shared AI training process that runs in a TEE, where no party can access another’s raw data, but all parties benefit from a model trained on the combined dataset.
Practical applications include:
- Consortium banks jointly training a fraud detection model on their combined transaction data — improving detection rates for all participants without sharing customer financial data
- Healthcare networks jointly training diagnostic AI on patient data from multiple hospital systems — producing more accurate models than any single institution’s data could support
- Competing retailers collaborating on supply chain optimization AI — sharing anonymized demand signals without exposing proprietary sales data
This connects to the collaborative learning paradigm covered in our guide on Federated Learning — Confidential Computing and Federated Learning are complementary approaches to the data sharing problem, with Confidential Computing providing stronger security guarantees at higher computational cost.
Government and Defense AI: Classified Data Processing
Government AI systems processing classified or sensitive national security information face the most stringent data protection requirements of any AI deployment context. Confidential Computing provides the hardware-based isolation required to process classified data in computing environments that must remain accessible to legitimate users while being demonstrably secure against insider threats and infrastructure compromises. Our guide to AI Data Loss Prevention covers the complementary prompt-level controls that work alongside confidential computing for government AI pipelines.
AI Model Intellectual Property Protection
The AI model itself — not just the data it processes — can be the sensitive asset requiring protection. A proprietary AI model representing years of development and significant competitive advantage can be protected using Confidential Computing: the model weights are loaded into a TEE, and inference is served from within the protected environment. External users can query the model but cannot extract the model weights — protecting the intellectual property of the model developer even when inference is served on shared infrastructure.
6. 🔗 Confidential Computing and the Broader AI Security Architecture
Confidential Computing is most powerful when it is integrated into a broader AI security architecture rather than deployed as an isolated control. Its relationship with other AI security approaches creates a layered defense that addresses the full threat surface of sensitive AI workloads.
| Security Approach | What It Protects | How It Complements Confidential Computing |
|---|---|---|
| Confidential Computing | Data in use — during active AI processing in memory | The core “data in use” protection that other approaches cannot provide |
| Federated Learning | Raw training data — never leaves the data owner’s environment | Reduces data movement; CC protects the aggregation server where model updates are combined |
| Differential Privacy | Individual privacy in model outputs and training gradients | DP protects against inference attacks on model outputs; CC protects data during training computation |
| NIST Cyber AI Controls | Broader AI system security posture | NIST framework maps Confidential Computing to PROTECT function controls for AI data in use |
| Secure RAG Architecture | Knowledge base data accessed during RAG retrieval at inference time — a regulated privacy surface under GDPR Article 5 | CC TEE can protect RAG retrieval process — ensuring retrieved documents are not exposed to infrastructure operators |
7. ⚡ Performance Considerations and Trade-offs
Confidential Computing introduces performance overhead — the hardware security mechanisms that protect data in use consume CPU cycles and add latency that conventional processing does not incur. Understanding these trade-offs is essential for organizations evaluating whether Confidential Computing is appropriate for specific AI workloads.
Performance Overhead by Technology
- Intel SGX: Historically the most constrained — early SGX implementations had limited enclave memory (128MB–256MB EPC) that required complex paging strategies for larger workloads. More recent implementations support larger EPC sizes but remain best suited for smaller, latency-sensitive AI tasks rather than large model inference.
- AMD SEV-SNP and Intel TDX: VM-level approaches with significantly lower performance overhead — typically 5–15% for most workloads — because they protect the entire VM rather than requiring application code to be specially compiled for enclave execution.
- GPU Confidential Computing: The newest and most significant capability for AI workloads — NVIDIA’s H100 and H200 GPUs support Confidential Computing with approximately 5–8% performance overhead for typical transformer model inference, making it practical for large language model deployments where data sensitivity justifies the overhead.
When the Performance Trade-off is Justified
The performance overhead of Confidential Computing is justified when:
- The regulatory cost of a data breach exceeds the operational cost of the performance overhead — virtually always true for healthcare, financial services, and legal AI workloads
- The competitive cost of model intellectual property exposure exceeds the cost of the performance overhead — true for proprietary AI models representing significant R&D investment
- The data owner requires cryptographic proof of data protection as a condition of data sharing — true for cross-organizational AI training initiatives
- Regulatory requirements mandate specific technical controls for data in use — increasingly true under emerging AI-specific regulation in 2026
8. ✅ Confidential Computing Implementation Checklist
Use this checklist during AI Audit and vendor evaluation, cloud provider selection, and AI architecture review to assess whether Confidential Computing is appropriate and correctly implemented for your specific AI workloads.
| ☐ | Control | What to Verify |
|---|---|---|
| ☐ | Workload Classification | AI workloads processing sensitive personal, financial, health, or classified data are identified and assessed for Confidential Computing requirements |
| ☐ | Hardware TEE Verification | Cloud provider infrastructure supports validated TEE hardware (AMD SEV-SNP, Intel TDX, or equivalent) for target AI workloads |
| ☐ | Remote Attestation Implementation | Remote attestation is implemented and verified before sensitive data is shared with AI processing environments — attestation without verification is security theatre |
| ☐ | Memory Encryption Verification | VM memory encryption is enabled and verified for all Confidential Computing workloads — not just at-rest encryption |
| ☐ | Key Management Architecture | Encryption keys for confidential workloads are managed in hardware security modules (HSMs) accessible only to the TEE — not to cloud provider administrators |
| ☐ | GPU Confidential Computing | For large model AI workloads, GPU Confidential Computing capability is verified — CPU TEE alone does not protect data processed on GPU |
| ☐ | Supply Chain Integrity | AI model code loaded into TEE is verified against known-good hashes before sensitive data is exposed — preventing supply chain attacks on the trusted code |
| ☐ | Regulatory Alignment | Confidential Computing controls are mapped to applicable regulatory requirements (HIPAA, GDPR, EU AI Act, SR 26-2) in the AI compliance audit record |
| ☐ | Performance Monitoring | Performance overhead of Confidential Computing is monitored and remains within acceptable SLA parameters for production AI workloads |
9. 🌐 Confidential Computing and AI Governance Frameworks
Confidential Computing addresses specific technical requirements referenced in multiple major AI governance and data protection frameworks — understanding these connections helps organizations justify Confidential Computing investments to governance and compliance stakeholders.
- EU AI Act: High-risk AI systems require “appropriate cybersecurity measures” and technical safeguards for data protection. Confidential Computing provides hardware-enforced technical safeguards that satisfy the most stringent interpretation of these requirements for AI systems processing personal data. See our EU AI Act guide for the full compliance context.
- GDPR Article 25 (Privacy by Design): Confidential Computing is one of the most technically robust implementations of Privacy by Design for AI processing — embedding data protection at the hardware level rather than relying solely on organizational and software controls.
- HIPAA: The HIPAA Security Rule’s technical safeguard requirements for access controls and integrity controls are satisfied with exceptional rigor by Confidential Computing implementations — providing cryptographic proof that PHI access is restricted to authorized code executing in a verified TEE.
- NIST AI RMF: The GOVERN and PROTECT functions of the NIST AI RMF map directly to Confidential Computing controls — particularly for AI systems in the “high risk” category where data sensitivity and potential harm justify the strongest available technical protections.
10. ⚖️ 2026 Regulatory Drivers — When Confidential Computing Moves From Optional to Required
The 2026 regulatory landscape has elevated confidential computing from a best-practice recommendation to a verifiable compliance requirement for regulated AI workloads. Understanding which regulations drive which requirements — and mapping them to your specific AI pipeline — is the governance work that turns a confidential computing investment into a documentable compliance control.
EU AI Act (August 2026 — Active)
High-risk AI systems under the EU AI Act must implement “appropriate technical and organizational measures” to protect data integrity and confidentiality throughout the AI lifecycle — including during processing. For AI systems classified as high-risk (medical devices, recruitment tools, credit scoring, critical infrastructure, law enforcement AI), confidential computing provides the strongest available technical evidence of processing-level data protection for conformity assessments. Article 50’s transparency obligations — requiring disclosure when AI generates content consumers might mistake for human-created — are complementary: they address output transparency while confidential computing addresses processing integrity. See the full compliance requirements in our EU AI Act Explained guide.
GDPR Article 32
GDPR requires “appropriate technical measures” to ensure data security — and the standard interpretation increasingly includes data-in-use protection for AI systems processing personal data at scale. Standard cloud encryption covers at-rest and in-transit but not in-use. Confidential computing is increasingly cited in GDPR audit responses and Data Protection Impact Assessments as the mechanism for addressing the data-in-use gap for AI inference pipelines processing EU personal data.
HIPAA Security Rule (US Healthcare)
Protected Health Information (PHI) processed through AI inference pipelines must be protected throughout the processing lifecycle under HIPAA’s technical safeguard requirements. AI inference on PHI in standard cloud environments without confidential computing creates audit exposure — particularly for cloud-based diagnostic AI, clinical decision support, and patient data analytics where PHI is processed continuously in shared infrastructure.
Colorado AI Act — SB 26-189 (Effective January 1, 2027)
Colorado’s SB 26-189, signed into law May 14, 2026 and effective January 1, 2027, requires high-risk AI systems making consequential decisions to implement technical safeguards, conduct bias assessments, and maintain audit trails. Confidential computing’s tamper-evident processing model directly supports the audit trail requirement — providing cryptographic evidence of what code ran, on what data, in what environment — supporting both bias audit and human oversight documentation requirements. Full coverage of all applicable 2026 US state regulations: AI Regulation in 2026.
US Federal SR 26-2 (April 2026)
The Federal Reserve’s model risk management framework for AI in financial services — effective April 17, 2026 — specifically addresses data integrity during inference as a model risk dimension. Financial institutions using AI for credit decisions, fraud detection, and risk modeling must validate and monitor AI systems in production — and confidential computing’s attestation capability provides cryptographic evidence that the production model is running as validated, on protected data, without tampering. See our AI Risk Assessment 101 guide for the full SR 26-2 governance framework.
11. 🛠️ Deploying Confidential Computing — What Every Team Needs to Know First
Understanding the technical and operational considerations before deployment prevents the most common implementation failures — particularly the ones that create a false sense of security without delivering the actual protections confidential computing is designed to provide.
Application Compatibility
Most existing AI and ML frameworks — PyTorch, TensorFlow, HuggingFace Transformers — run inside TEEs without code changes when using Confidential VM approaches (Azure Confidential VMs, Google Confidential GKE). Enclave-specific approaches (AWS Nitro, older Intel SGX) may require application refactoring to partition sensitive code and data into the enclave. For most ML teams, Google Confidential GKE and Azure Confidential VMs offer the lowest-friction migration path from existing containerized workloads.
The Attestation Integration Requirement
Confidential computing without attestation is incomplete. If you cannot verify what code is running inside the TEE, you cannot make trust decisions based on its outputs — and data owners cannot safely send sensitive data to the enclave. Attestation must be integrated into your data pipeline: clients verify TEE state before sending sensitive data; the attestation check is not optional. Managed attestation services — Azure Attestation, AWS Nitro Attestation, Google Attestation Verifier — handle most of the cryptographic complexity and are the recommended starting point for teams new to confidential computing deployment.
Human-in-the-Loop Governance Remains Required
Confidential computing protects the technical processing environment — it does not substitute for human governance of AI decisions. An AI system making consequential decisions about patients, loan applicants, or job candidates must still have human oversight and appeal mechanisms regardless of whether it runs in a TEE. Confidential computing and human-in-the-loop governance are complementary, not substitutes. Our guide to Human-in-the-Loop AI covers the approval gate framework that governs AI decisions alongside the technical protections confidential computing provides.
When NOT to Use Confidential Computing
- Non-sensitive workloads with no regulatory data requirements: standard cloud encryption is sufficient — the performance overhead is not justified
- Rapid prototyping and development environments: the deployment complexity is not warranted until you are processing real regulated data in production
- Ultra-latency-sensitive inference workloads where even 5–8% overhead breaks your SLA: evaluate other data protection controls and architecture options first
- Workloads where the primary risk is application-layer vulnerabilities (prompt injection, insecure output handling): confidential computing addresses infrastructure-level threats, not application-layer attacks — see our Improper Output Handling guide for application-layer controls
🏁 Conclusion: The New Baseline for Sensitive AI Workloads
Confidential Computing is moving from a specialized capability used by the most security-conscious organizations to a baseline expectation for AI workloads processing sensitive data. The convergence of regulatory pressure — EU AI Act, HIPAA, GDPR, SR 26-2, and Colorado SB 26-189 — enterprise procurement requirements, and readily available cloud-native Confidential Computing services has made the deployment friction minimal and the security benefit unambiguous.
For organizations in healthcare, financial services, legal, government, and any other domain where the sensitivity of AI-processed data is not in doubt, the question is no longer whether to implement Confidential Computing for sensitive AI workloads — it is how to prioritize the implementation across the portfolio of AI systems that genuinely require it. The encryption story for AI data is complete only when data at rest, data in transit, and data in use are all protected — and Confidential Computing is what closes the final gap. Build your attestation infrastructure, verify your TEE hardware, confirm GPU confidential computing support for your model architecture, map your controls to your regulatory requirements, and treat confidential computing as the foundation layer it has become for any AI pipeline processing data that cannot afford to be exposed.
🔗 Explore the AI Governance & Security Hub
Confidential Computing is one piece of a complete AI security stack. Explore our full coverage of AI governance, data protection, model risk, and compliance frameworks — including implementation guides, checklists, and regulatory mapping.
📌 Key Takeaways
| ✅ | Takeaway |
|---|---|
| ✅ | Confidential Computing protects data in use — the one state of data that conventional encryption (at rest and in transit) does not cover — by isolating processing inside hardware-enforced Trusted Execution Environments that the cloud provider, hypervisor, and OS cannot access. |
| ✅ | Trusted Execution Environments use hardware-enforced isolation — protection that cannot be bypassed by operating systems, hypervisors, or cloud provider administrators — enforced by the processor itself, not by software controls. |
| ✅ | Remote attestation allows remote parties to cryptographically verify that the correct code is running inside a genuine TEE before sending sensitive data. Confidential computing without attestation is incomplete — attestation is what makes the trust model valid. |
| ✅ | The three major TEE implementations — AMD SEV-SNP, Intel TDX, and Intel SGX — are all available across Azure, Google Cloud, and AWS with FedRAMP High authorization, varying performance profiles, and different optimal AI use cases. VM-level approaches (TDX, SEV-SNP) are the recommended starting point for most AI workloads. |
| ✅ | Confidential Computing enables multi-party AI training — where multiple organizations contribute data to a shared model training process without any party accessing another’s raw data — unlocking AI collaboration that data privacy constraints previously made impossible. |
| ✅ | GPU Confidential Computing on NVIDIA H100/H200 hardware — supporting large language model inference inside a TEE with ~5–8% performance overhead — is the most significant 2026 advancement for AI workloads specifically, making confidential LLM inference practical at production scale. |
| ✅ | EU AI Act (August 2026) requires high-risk AI systems to implement technical data protection during processing. GDPR Article 32, HIPAA, Colorado SB 26-189 (effective January 1, 2027), and US Federal SR 26-2 (effective April 17, 2026) all create data-in-use protection requirements that standard cloud encryption cannot satisfy — confidential computing is the primary technical solution. (Note: Virginia HB 2094 was vetoed — no Virginia AI Act is enacted.) |
| ✅ | Performance overhead is 5–15% for VM-level approaches and 5–8% for GPU Confidential Computing — acceptable for regulated workloads where the compliance cost of a data breach far exceeds the operational cost of the overhead. Not justified for non-sensitive, development, or ultra-latency-sensitive workloads. |
| ✅ | Do not deploy confidential computing without attestation — and do not treat it as a substitute for human-in-the-loop governance. Confidential computing protects the infrastructure layer; human oversight governs the decision layer. Both are required for compliant, trustworthy AI in regulated environments. |
| ✅ | Any AI pipeline processing PHI, PII, financial data, legal records, or classified information that does not use confidential computing has an unaddressed audit exposure in data-in-use protection — one that regulators, auditors, and enterprise procurement teams are increasingly identifying and requiring remediation. |
| ✅ | For AI workloads, TEEs protect three critical assets simultaneously: inference inputs (sensitive data sent to the model), model weights (the trained parameters representing the AI’s intellectual property), and intermediate computations (activation values and KV cache produced during processing). CPU-level TEE alone is insufficient for GPU-accelerated AI — GPU confidential computing on NVIDIA H100/H200 hardware is required for full data-in-use protection of large language model workloads. |
| ✅ | Key residual risk: Confidential computing protects data during processing inside the TEE — it does not prevent model inversion attacks on inference outputs, prompt injection at the application layer, or membership inference attacks that attempt to reconstruct training data from model responses. These require separate application-layer controls; confidential computing and AI Privacy by Design are complementary, not substitutes. |
🔗 Related Articles
- 📖 Differential Privacy Explained: How AI Systems Protect Individual Data (2026)
- 📖 AI Privacy by Design: How to Build Privacy Into GenAI and RAG Systems
- 📖 Zero Trust Security for AI Systems: A Practical Implementation Guide (2026)
- 📖 AI Supply Chain Security: How to Secure Your AI Model Pipeline (2026)
- 📖 DPIA for AI Systems: A Step-by-Step Compliance Guide (2026)
❓ Frequently Asked Questions: Confidential Computing
1. Does Confidential Computing protect data from the cloud provider itself?
Yes. The primary goal of a Trusted Execution Environment (TEE) is to ensure that even a cloud admin or a compromised host operating system cannot see the data being processed. It effectively creates a “no-go zone” for everyone except the authorized AI agent.
2. Does Confidential Computing slow down AI performance?
There is usually a small “performance tax.” Because data must be encrypted and decrypted as it moves in and out of the secure enclave, latency can increase by 5% to 15%. For most high-stakes finance or healthcare apps, this is an acceptable trade-off for total privacy.
3. Can Confidential Computing prevent AI hallucinations?
No. Confidential Computing only protects data privacy and integrity; it does not improve the “intelligence” of the model. To solve the accuracy problem, you still need to implement Explainable AI (XAI) and robust retrieval-augmented generation (RAG) frameworks.
4. Is Confidential Computing the same as Homomorphic Encryption?
No. Homomorphic Encryption allows you to calculate data while it stays encrypted, which is mathematically intense and very slow. Confidential Computing decrypts the data inside a secure hardware “bunker,” making it fast enough for real-time multi-agent systems.
5. Does my company need a special policy to use Confidential Computing?
Yes. While the tech is secure, you still need a Corporate AI Policy to define who has the “keys” to the enclave. Even the most secure bunker is useless if an unauthorized employee has the credentials to look inside.
📧 Get the AI Buzz Weekly Digest
Weekly AI insights, tools, and strategies — delivered every Monday. Free.
Leave a Reply