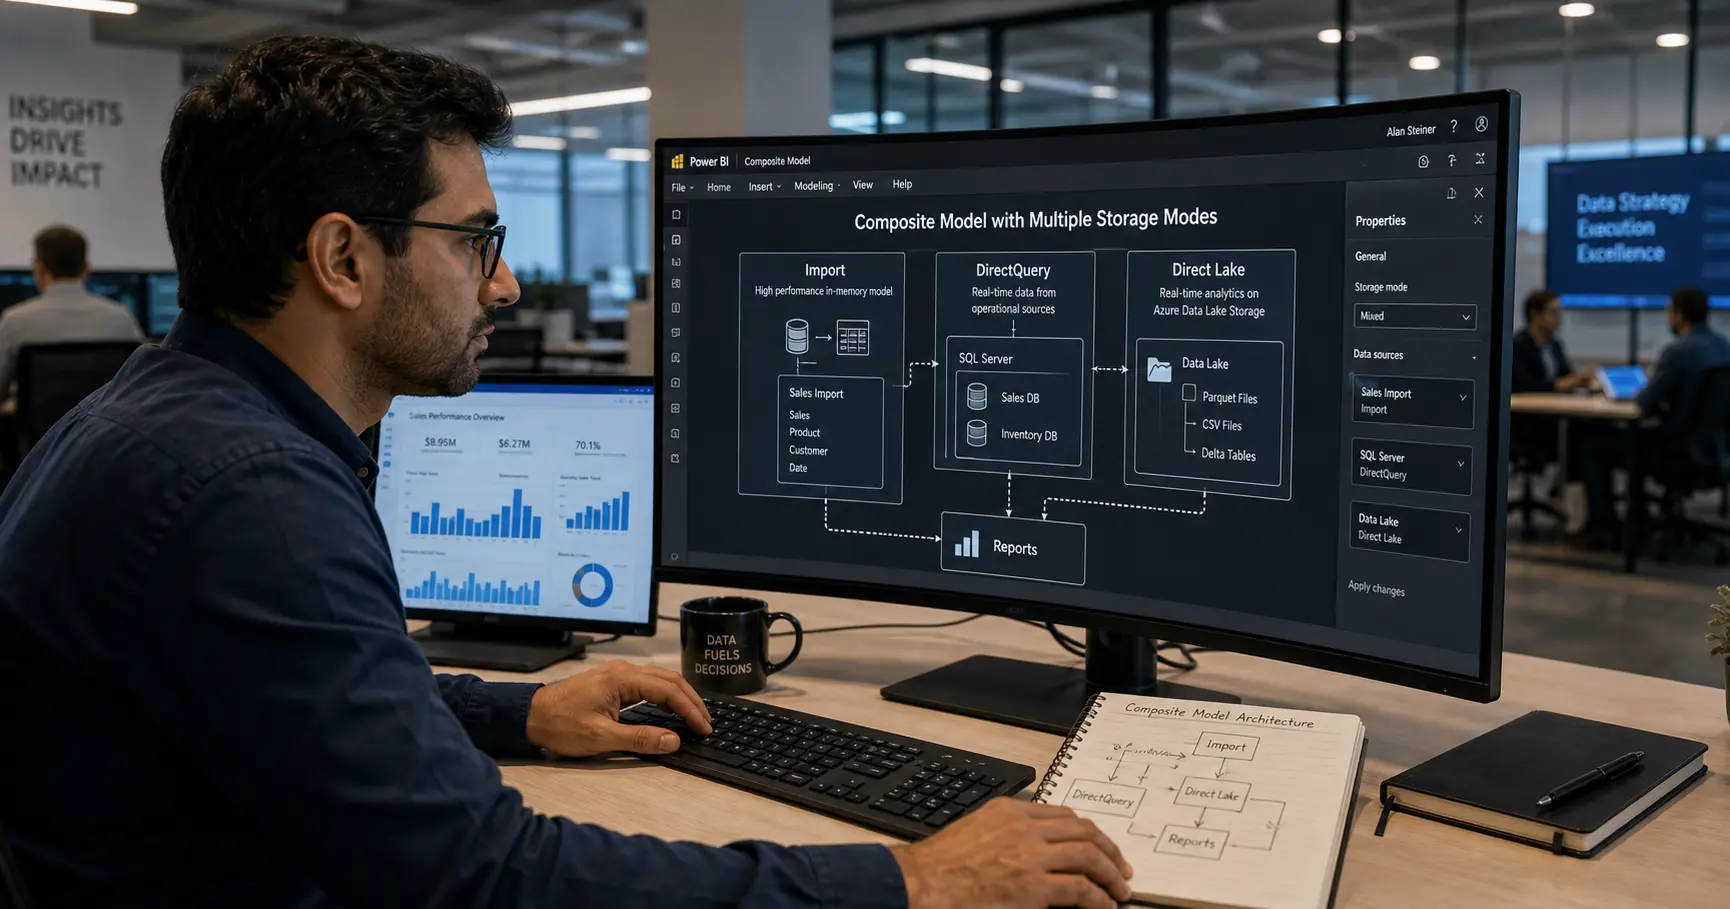
⚡ Billions of rows. Sub-second dashboards. No full refresh required. This guide explains exactly how Power BI composite models and aggregations work — and gives you the 2026 decision framework for when to use them, how to build them, and how to avoid the pitfalls that kill performance in production.
Last Updated: October 21, 2026
Every Power BI developer eventually hits the same wall. The dataset is too large to import cleanly, pure DirectQuery is too slow for executives who expect instant visuals, and the organization has neither the refresh budget nor the memory capacity to brute-force the problem. For years, this was the trade-off that defined large-scale Power BI projects: you either accepted stale data or slow reports. In 2026, Power BI composite models with aggregations are the standard architectural answer — and understanding them is now a core skill for any serious BI professional.
This article explains what composite models are, how aggregations work inside them, and how the arrival of Direct Lake on OneLake (GA March 2026) has changed the decision framework. You will learn the four storage modes that composite models combine, the aggregation design methodology used by enterprise teams, the specific 2026 guidance on Direct Lake composite model support, and the step-by-step process for configuring aggregations in Power BI Desktop. This is not a conceptual overview — it is a practical implementation guide built for data professionals working at scale.
By the end of this article you will be able to make a confident, data-backed decision about whether a composite model is the right architecture for your workload, design an aggregation table that delivers sub-second performance on billion-row fact tables, and avoid the five most common configuration mistakes that force unnecessary fallback to DirectQuery detail. According to EPC Group’s Power BI Performance Optimization research across 150+ enterprise organizations, splitting large models into Import-mode dimensions and DirectQuery facts delivers 40–60% model size optimization and 50–70% query performance improvement compared to flat table designs — making composite models one of the highest-ROI architectural decisions in the Power BI stack.
📘 New to Power BI terminology? Before diving in, bookmark the AI Buzz Glossary — 100+ essential AI terms explained in plain English. Storage modes, VertiPaq, and semantic models are all covered.
⚙️ 1. What Are Power BI Composite Models?
A composite model is a Power BI semantic model that combines two or more storage modes in a single dataset. Before composite models existed, every table in a Power BI model had to use the same connectivity approach — you were either fully in Import mode, fully in DirectQuery, or fully in Live Connection. That constraint forced a binary choice: fast but stale, or fresh but slow. Composite models eliminate this trade-off entirely.
In a composite model, the four storage modes — Import, DirectQuery, Dual, and Direct Lake — can coexist in the same semantic model, each assigned at the individual table level. A typical enterprise composite model places large fact tables in DirectQuery (keeping them live and unbounded by memory limits), places dimension tables in Dual mode (cached for fast filtering, but also capable of being queried live), and adds Import-mode aggregation tables that pre-compute the summary statistics most users actually need. The result is a model that behaves like Import for 80–95% of dashboard interactions while maintaining DirectQuery access to full transaction detail when users drill through.
The business case is straightforward. EPC Group recommends composite models for datasets between 1GB and 10GB, and DirectQuery only when real-time data is a genuine business requirement that justifies the performance trade-off. For datasets that exceed Import mode’s practical limits — fact tables with hundreds of millions or billions of rows — a composite model with aggregations is the architectural standard, not the exception.
The 2026 Composite Model Reality: Pure Import mode is fast but capacity-constrained. Pure DirectQuery is unbounded but slow. Composite models with aggregations are the production-grade middle path — delivering Import-like performance for the vast majority of queries while preserving DirectQuery precision for drill-through scenarios. This is the architecture pattern Microsoft’s own benchmark data confirms at billion-row scale.
The Four Storage Modes in a Composite Model
Understanding how the four storage modes interact is the foundation of composite model design. Each mode has a specific role, and assigning the wrong mode to the wrong table is the most common source of poor composite model performance.
| Mode | Speed | Data Freshness | Best Assigned To | Composite Role |
|---|---|---|---|---|
| Import | Fastest — VertiPaq in-memory | Stale between refreshes | Dimensions, aggregation tables, small facts | Aggregation layer |
| DirectQuery | Slower — source query per visual | Real-time — always current | Large fact tables, live source requirements | Detail fallback layer |
| Dual | Import speed when cached | Import freshness when cached | Dimensions joined to DirectQuery facts | Dimension layer — mandatory |
| Direct Lake | Near-Import on warm data | Near real-time via OneLake | Large Fabric Lakehouse facts | Fabric fact layer (OneLake only) |
Weak Relationships — The Cross-Source Constraint You Must Understand
When tables in a composite model come from different sources or use different storage modes, Power BI creates what it calls a weak relationship. Unlike a strong relationship — which can enforce referential integrity and supports bidirectional filtering — a weak relationship cannot guarantee that every key in the fact table exists in the dimension table. This matters because weak relationships change how DAX evaluates filters, and bidirectional filtering across weak relationships is a common source of unexpectedly slow queries. The practical rule is simple: avoid bidirectional cross-mode relationships unless you have a specific analytical requirement that cannot be solved another way, and always verify the relationship type in Model View before publishing.
📊 2. How Aggregations Work Inside Composite Models
Aggregations are the performance engine of a composite model. An aggregation table is a pre-computed summary of a DirectQuery fact table, stored in Import mode inside the same semantic model. When a user loads a dashboard visual, Power BI’s query engine — before sending any query to the source database — checks whether the aggregation table can answer the question. If the aggregation grain matches the query grain, the visual is served entirely from VertiPaq in-memory storage. No network call. No source database hit. Sub-second response time regardless of how large the underlying fact table is.
This automatic query routing is what makes aggregations powerful. The intelligence is built into the Power BI engine — the user does not need to know or interact with the aggregation layer. They simply click a slicer or expand a drill-down, and Power BI silently decides whether to serve the result from the fast aggregation table or fall back to the DirectQuery detail table. When a query requires finer granularity than the aggregation provides — for example, drilling to an individual transaction or filtering by a column that is not in the aggregation — Power BI automatically falls back to the DirectQuery source. This fallback is seamless and invisible to the end user.
According to a Microsoft Fabric community benchmark on billion-row Databricks datasets, a composite model with aggregations was the fastest and most consistent pattern tested — staying sub-100ms on queries that the aggregation tables could resolve. That benchmark tested four architectures: Direct Lake on OneLake, Direct Lake on mirrored Unity Catalog tables, pure DirectQuery, and a composite model with Import-mode aggregations. The composite model won on consistency for high-concurrency dashboard workloads.
The Aggregation Design Rule
Microsoft’s official composite model guidance provides a clear sizing rule: an aggregation table’s row count should be at least a factor of 10 smaller than the underlying DirectQuery table. If your fact table has 1 billion rows, the aggregation table should contain no more than 100 million rows. This ratio ensures the performance gain from the aggregation is worth the cost of creating and maintaining it. In practice, well-designed aggregations at monthly or daily grain on large fact tables typically achieve a compression ratio of 100:1 or better — meaning a 1-billion-row fact table produces an aggregation table of 10 million rows or fewer.
Multi-Level Aggregation Hierarchies
For very large or analytically complex datasets, a single aggregation table is often not enough. Enterprise teams commonly implement multi-level aggregation hierarchies: a daily aggregation table for detailed trend analysis, a monthly aggregation table for executive dashboard summaries, and the full DirectQuery fact table for transaction-level drill-through. Power BI evaluates each incoming query against all available aggregation tables and automatically selects the most granular aggregation that can still satisfy the query. This means that a monthly-grain query is served by the smallest, fastest aggregation table, while a daily-grain query automatically steps down to the daily aggregation — with the DirectQuery table as the final fallback for transaction detail.
| Aggregation Layer | Storage Mode | Grain Example | Serves |
|---|---|---|---|
| AggSales_Monthly | Import | Month, Product Category, Region | Executive dashboards, KPI cards |
| AggSales_Daily | Import | Day, Product, Customer Segment | Analyst trend reports, daily ops |
| FactSales (full) | DirectQuery | Individual transaction row | Drill-through, audit, compliance |
🔧 3. How to Configure Aggregations in Power BI Desktop — Step by Step
Configuring aggregations correctly is not complicated, but the sequence matters. Skipping any step — particularly the Manage Aggregations mapping dialog — results in a model where Power BI never routes queries to the aggregation table, and every visual silently falls back to the slower DirectQuery source. The steps below cover the full configuration workflow.
Step 1: Identify Which Queries Are Slowest
Before building an aggregation table, open Performance Analyzer in Power BI Desktop (View → Performance Analyzer → Start Recording) and interact with your report. Performance Analyzer records the duration of every visual query, broken down into DAX query time, visual display time, and other. Sort by DAX query time descending — the slowest visuals are your aggregation candidates. Export the results to a table and identify the common grouping columns: if most of your slow visuals group by Month and Product Category, that is your first aggregation grain. Aggregation tables built without this analysis frequently miss the most common query patterns and deliver no measurable performance improvement.
Step 2: Create the Aggregation Table in Your Source or Power Query
The aggregation table itself is a simple pre-aggregated summary of the DirectQuery fact table, created at the grain you identified in Step 1. In SQL, a monthly sales aggregation looks like this:
SELECT
    DateKey,
    ProductKey,
    CustomerSegmentKey,
    SUM(SalesAmount) AS TotalSalesAmount,
    SUM(Quantity) AS TotalQuantity,
    COUNT(*) AS TransactionCount
FROM
    FactSales
GROUP BY
    DateKey,
    ProductKey,
    CustomerSegmentKey
This query reduces a billion-row transaction table to a manageable summary. Load this aggregation table into your Power BI model as an Import mode table — set the Storage Mode to Import explicitly in the Properties pane. Never set aggregation tables to DirectQuery or Dual; the entire performance benefit of an aggregation depends on it being cached in VertiPaq.
Step 3: Set Dual Mode on All Dimension Tables
This step is the one most developers skip — and skipping it is the single most common reason composite model aggregations fail to fire. All dimension tables that join to a DirectQuery fact table must be set to Dual storage mode, not Import. In Dual mode, Power BI caches the dimension data in VertiPaq (giving Import-speed filtering) while also allowing the dimension to participate in DirectQuery queries when the fact table needs to be queried live. Without Dual mode on dimensions, Power BI cannot route queries to the aggregation table — it falls back to DirectQuery for every visual, regardless of whether an aggregation table exists.
Step 4: Configure the Aggregation Mappings
In Power BI Desktop, right-click the aggregation table in the Fields pane and select Manage Aggregations. This opens the aggregation mapping dialog. For each column in your aggregation table, specify the summarization function (Sum, Count, Min, Max, GroupBy) and map it to its corresponding column in the DirectQuery detail table. GroupBy mappings tell Power BI which grain columns the aggregation represents — these are the columns that determine whether an incoming query can be served by the aggregation or must fall back to detail. Sum and Count mappings tell Power BI which measure columns are pre-computed. Complete mappings are mandatory — a partial mapping means Power BI cannot guarantee the aggregation will satisfy a given query, and it will default to DirectQuery fallback.
Step 5: Validate Aggregation Hits Using DAX Studio
After configuration, validate that queries are actually hitting the aggregation table. Open DAX Studio, connect to your Power BI model, and run a test query against the measures served by your aggregation. In the query plan output, look for a Storage Engine scan on the aggregation table name — not the DirectQuery fact table. If you see the fact table name in the storage engine scan, the aggregation is not firing. Common causes: a dimension table is not in Dual mode, the aggregation mapping is incomplete, or a visual is grouping by a column that is not in the aggregation grain. The Performance Analyzer in Power BI Desktop also shows “Direct query” in the DAX query results when an aggregation is not being used — use this as a quick production check before publishing.
⚖️ 4. Composite Models vs Direct Lake — The 2026 Decision Framework
With Direct Lake on OneLake reaching general availability in March 2026, the storage mode decision tree has become more complex for teams running on Microsoft Fabric. Direct Lake is not a replacement for composite models with aggregations — it is a third architectural option with its own trade-offs, and the right choice depends on your specific workload, data volume, and Fabric capacity SKU.
The key distinction is this: Direct Lake reads column segments from Delta tables in OneLake on demand, without loading the entire dataset into memory. This gives near-Import performance without the refresh cycle — and it works beautifully for large Fabric Lakehouse workloads where the data is already in Delta format. However, Direct Lake in 2026 has meaningful modeling constraints that composite models do not share. As confirmed by Microsoft’s current Fabric documentation, user-defined aggregations are not supported in Direct Lake mode. Direct Lake on SQL analytics endpoints cannot participate in composite models at all. And Direct Lake models do not support calculated columns or Power Query transforms — two capabilities that many enterprise semantic models depend on.
The practical implication is that Direct Lake and composite models serve different scenarios, and they can also work together. As of June 28, 2026, Direct Lake on OneLake supports composite models that combine Direct Lake fact tables with Import-mode dimension tables. This hybrid pattern — Direct Lake facts plus Import dimensions — gives you the refresh advantages of Direct Lake (no full data copy into VertiPaq, near-real-time framing) while maintaining the modeling flexibility of Import for dimension tables that require calculated columns, Power Query transforms, or complex relationship logic.
The 2026 Decision Rule: If your data is in Microsoft Fabric OneLake as properly optimized Delta tables, start with Direct Lake. If you need user-defined aggregations, calculated columns, or are sourcing data from outside Fabric, composite models with aggregations remain the correct architecture. For billion-row workloads where both freshness and sub-second performance are required, a hybrid Direct Lake fact plus Import dimension composite model is the 2026 standard pattern.
Direct Lake Composite Model Support — June 2026 Update
The June 28, 2026 Tabular Editor documentation confirms that Direct Lake support in composite models is mode-dependent. Direct Lake on OneLake can participate in composite models and combine with Import-mode tables. Direct Lake on SQL analytics endpoints, however, remains more constrained — you cannot combine Direct Lake on SQL endpoint storage mode tables with DirectQuery or Dual storage mode tables within the same semantic model. You can, however, use Power BI Desktop to create a composite model on a Direct Lake semantic model and extend it with new tables using Import, DirectQuery, or Dual storage mode. Understanding this distinction prevents one of the most frustrating dead-ends in 2026 Fabric development: attempting to add a DirectQuery table to a Direct Lake on SQL endpoint model and discovering the composite model feature is unavailable.
| Scenario | Recommended Architecture | Why | Fabric Required? |
|---|---|---|---|
| Large Fabric Lakehouse, Delta tables, no calc columns needed | Direct Lake (pure) | No refresh cost, near-real-time framing | Yes — F2 minimum |
| Fabric Lakehouse facts + complex dimensions with calc columns | Direct Lake facts + Import dimensions (composite) | Preserves Direct Lake refresh advantage while enabling full dimension modeling | Yes — F2 minimum |
| Billion-row external source (Azure SQL, Synapse, Databricks) | Composite model: DQ facts + Import aggs + Dual dims | Sub-second for 80–95% of queries; DQ fallback for detail | No — works with Premium or Pro + gateway |
| Dataset under 1GB, refresh budget available | Pure Import mode | Simplest architecture, fastest queries, no complexity cost | No |
| Real-time source, governance prohibits data copy | Composite model: DQ facts + Import aggs | Aggregations serve most queries; live DQ for drill-through | No — works on-premises with gateway |
🌊 5. Composite Models on Microsoft Fabric — Capacity and Concurrency
Running composite models on Microsoft Fabric introduces capacity-specific considerations that do not apply to on-premises or standard Power BI Premium deployments. Understanding how Fabric’s CU (Capacity Unit) smoothing works for different storage modes is essential for teams designing composite models at enterprise scale — particularly for high-concurrency dashboard environments.
On Fabric, DAX queries against Import-mode or Direct Lake tables are counted as interactive operations and smoothed over a 5 to 64-minute window depending on your F-SKU. Queries against DirectQuery fact tables in a composite model, however, consume some interactive CUs but the SQL queries generated against the Fabric Warehouse engine are counted as background operations and smoothed over 24 hours. This means that composite models with DirectQuery fact tables can actually handle significantly more concurrent users than pure Import or pure Direct Lake models on the same Fabric capacity — because the smoothing window for background operations is twelve to 288 times longer than for interactive operations, dramatically reducing peak CU consumption.
The F-SKU guardrails confirmed in SP External Sources remain critical context for composite model planning. At F2–F32, the row and Parquet file limits per table (300 million rows, 1,000 Parquet files) may affect Direct Lake fact tables in hybrid composite models — though these limits do not apply to DirectQuery tables, which query the source rather than loading into the model. At F64 and above, Direct Lake table limits expand to 1.5 billion rows per table with 25GB memory, enabling Direct Lake to serve as the primary fact layer for very large models without composite model complexity. Teams at F32 and below running billion-row workloads will frequently find that a composite model with DirectQuery facts is the more practical architecture than Direct Lake alone.
The Incremental Refresh and Composite Model Connection
One architectural pattern that combines two of the most powerful Hub 6 techniques is using incremental refresh on Import-mode aggregation tables within a composite model. Aggregation tables need to stay current as the underlying DirectQuery fact table grows. Without incremental refresh, refreshing a monthly aggregation table requires reprocessing all historical data on every cycle — inefficient and slow. With incremental refresh configured on the aggregation table, only the most recent partitions are refreshed on each cycle. The EPC Group benchmark data confirms that incremental refresh reduces refresh times from 35 minutes to 4 minutes (an 88% reduction) for large datasets — and that improvement applies equally to aggregation tables as it does to full Import fact tables. This combination of composite model architecture plus incremental refresh on aggregation tables is the production-grade performance pattern for enterprise Power BI in 2026.
📊 Explore the Full Power BI & Data Analytics Hub
This article is part of AI Buzz’s Power BI learning path for data professionals. Explore our complete library of Power BI guides — from star schema design to Fabric capacity planning — at the Power BI & Data Analytics Hub.
⚠️ 6. The 5 Most Common Composite Model Mistakes (and How to Fix Them)
Composite models are powerful, but they have a reputation for being difficult to get right in production. Most of that reputation is earned by the same five configuration mistakes appearing repeatedly across enterprise implementations. Each one is avoidable with the right checklist.
Mistake 1: Dimension Tables Left in Import Mode Instead of Dual
This is the most common and most damaging mistake. When dimension tables are set to Import mode instead of Dual mode, Power BI cannot route queries through the aggregation layer — every visual defaults to DirectQuery fallback, the aggregation table is never used, and the entire performance benefit of the composite model is lost. The fix is straightforward: open the Properties pane for every dimension table that joins to a DirectQuery fact table and confirm the Storage Mode is set to Dual. After changing to Dual, refresh the model and re-validate with DAX Studio or Performance Analyzer that aggregation tables are now being hit.
Mistake 2: Incomplete Aggregation Mappings
Power BI requires that every column in the aggregation table is explicitly mapped in the Manage Aggregations dialog. A common mistake is mapping the measure columns (Sum, Count) but forgetting to set GroupBy mappings for every grouping column — including foreign key columns that link to dimensions. If the mapping is incomplete, Power BI cannot guarantee the aggregation will return correct results for a given query, and it defaults to the DirectQuery fact table instead. Always verify every column in the aggregation table has a mapping before publishing.
Mistake 3: Bidirectional Relationships Crossing Storage Modes
Bidirectional cross-filter relationships between Import and DirectQuery tables create weak relationships that degrade query performance and can produce unexpected filter behavior. The rule is: use single-direction relationships for all cross-mode relationships, with filters flowing from dimension to fact. Reserve bidirectional filtering for within-mode relationships where referential integrity can be enforced. If a particular visual requires bidirectional filtering across modes, use DAX CROSSFILTER() to apply it explicitly within a measure rather than enabling it globally in the relationship settings.
Mistake 4: No Columnstore Index on the DirectQuery Source
Aggregation tables serve 80–95% of queries, but the DirectQuery fallback must still perform acceptably for drill-through scenarios. The most common cause of unacceptably slow DirectQuery fallback is the absence of appropriate indexing on the source database. For SQL Server and Azure SQL sources, a columnstore index on the fact table is the single highest-ROI database optimization for Power BI DirectQuery workloads. For Azure Synapse, ensure the distribution is hash-distributed on the most common join key. For Databricks, apply Z-ordering and OPTIMIZE on the Delta tables before Power BI queries them. Ignoring source database optimization turns drill-through from a rare fallback into a reliability problem.
Mistake 5: Building Aggregations Without Monitoring Query Patterns First
Aggregation tables built on assumptions — rather than actual query pattern analysis — frequently cover the wrong grain and deliver no measurable performance improvement. The correct sequence is always: measure first with Performance Analyzer, identify the grain of the slowest queries, build the aggregation to match that grain, then validate that the aggregation fires using DAX Studio. Aggregation tables that take more than five minutes to refresh should themselves be considered for incremental refresh partitioning. Start with the most common query grain — almost always a date hierarchy combined with one or two high-cardinality dimension columns — and expand from there based on monitoring data.
🏁 7. Conclusion — When Composite Models Are the Right Answer
Power BI composite models with aggregations are not a workaround for a Power BI limitation — they are a deliberate architectural pattern that reflects how modern enterprise analytics actually works. Most dashboard users most of the time are looking at summary-level data: monthly sales totals, regional performance comparisons, category-level trends. A tiny fraction of interactions require transaction-level detail. Composite models match the architecture to that reality: Import-speed VertiPaq for the 80–95% of queries that can be answered at aggregation grain, with live DirectQuery precision available the moment a user needs to drill to the underlying detail.
In 2026, the decision framework has become richer with the general availability of Direct Lake on OneLake. Teams on Microsoft Fabric have a genuine three-way choice — pure Direct Lake, a Direct Lake plus Import hybrid composite model, or a traditional DirectQuery plus Import aggregation composite model — each optimized for a different combination of data location, freshness requirement, modeling complexity, and Fabric capacity tier. Teams not on Fabric retain the DirectQuery plus aggregation composite model as a well-proven, production-grade architecture that works with any Power BI capacity including Pro with gateway. The complexity of composite models is real, but it is manageable with the right design sequence: profile first, design aggregations to match actual query patterns, set Dual mode on dimensions without exception, validate with DAX Studio, and monitor aggregation hit rates in production. Done correctly, composite models transform large-scale Power BI deployments from a performance problem into a performance advantage.
📌 Key Takeaways
| ✅ | Takeaway |
|---|---|
| ✅ | Composite models combine Import, DirectQuery, Dual, and Direct Lake storage modes in a single semantic model — eliminating the binary choice between fast-stale and slow-fresh data. |
| ✅ | Aggregations are Import-mode pre-computed summary tables that Power BI automatically uses when a query can be resolved at the aggregation grain — delivering sub-100ms response on billion-row fact tables confirmed by Microsoft’s Fabric benchmark data. |
| ✅ | Dimension tables MUST be set to Dual storage mode — not Import — when joined to DirectQuery fact tables. Leaving dimensions in Import mode prevents aggregation routing and negates all performance gains. |
| ✅ | Microsoft’s official guidance requires aggregation tables to be at least 10x smaller in row count than the underlying DirectQuery fact table — a 1-billion-row fact table should have an aggregation of no more than 100 million rows. |
| ✅ | As of June 28, 2026, Direct Lake on OneLake supports composite models combining Direct Lake facts with Import dimensions — but Direct Lake on SQL analytics endpoints cannot participate in composite models with DirectQuery or Dual tables. |
| ✅ | EPC Group data across 150+ organizations confirms that splitting large models into Import dimensions and DirectQuery facts delivers 40–60% model size optimization and 50–70% query performance improvement versus flat table designs. |
| ✅ | Always validate aggregation configuration with DAX Studio before publishing — if the storage engine scan references the DirectQuery fact table name rather than the aggregation table, the aggregation is not firing and must be debugged before going live. |
| ✅ | Applying incremental refresh to Import-mode aggregation tables reduces aggregation refresh times by up to 88% (EPC Group benchmark: 35 minutes to 4 minutes) — making composite models viable even for near-real-time aggregation requirements. |
🔗 Related Articles
- 📖 Power BI Import vs DirectQuery vs Direct Lake: Which Storage Mode Should You Use? (2026)
- 📖 Power BI Incremental Refresh Explained: The Ultimate 2026 Performance Guide
- 📖 Power BI Star Schema Explained: How to Build a Fast, Correct Data Model (2026)
- 📖 What Is Microsoft Fabric? How It Changes Power BI for Business Teams (2026)
- 📖 Power BI Dataflows Explained: What They Are and When to Use Them (2026)
🧠 Frequently Asked Questions: Power BI Composite Models and Aggregations
1. What is a composite model in Power BI and when should I use one?
A composite model is a Power BI semantic model that combines multiple storage modes — Import, DirectQuery, Dual, and Direct Lake — in a single dataset. Use one when your fact tables are too large for Import mode but pure DirectQuery is too slow for your users. Our Power BI Import vs DirectQuery vs Direct Lake guide walks through the full storage mode decision framework.
2. Why are my aggregations not firing in Power BI?
The most common cause is dimension tables set to Import mode instead of Dual mode. When dimensions are in Import mode, Power BI cannot route queries through the aggregation layer and falls back to DirectQuery for every visual. Set all dimension tables joined to DirectQuery fact tables to Dual storage mode, then validate using DAX Studio to confirm the aggregation table appears in the storage engine query plan.
3. Do Power BI composite models work with Microsoft Fabric Direct Lake?
Yes, but with important constraints. As of June 28, 2026, Direct Lake on OneLake supports composite models combining Direct Lake fact tables with Import-mode dimension tables. Direct Lake on SQL analytics endpoints cannot participate in composite models with DirectQuery or Dual tables. See our Microsoft Fabric overview for full Fabric architecture context.
4. How large should my aggregation table be relative to my fact table?
Microsoft’s official guidance recommends the aggregation table contain at least 10 times fewer rows than the underlying DirectQuery fact table. For a 1-billion-row fact table, the aggregation table should have no more than 100 million rows. In practice, well-designed monthly or daily aggregations on large fact tables typically achieve 100:1 compression or better, keeping aggregation tables small and fast.
5. Can I use incremental refresh on aggregation tables inside a composite model?
Yes, and it is strongly recommended for any aggregation table that covers historical data. Applying Power BI incremental refresh to Import-mode aggregation tables means only the most recent partitions are processed on each refresh cycle, rather than reprocessing all historical aggregation data. EPC Group benchmark data confirms incremental refresh reduces refresh times by up to 88% on large datasets — a benefit that applies equally to aggregation tables.
📧 Get the AI Buzz Weekly Digest
Weekly AI insights, tools, and strategies — delivered every Monday. Free.
Leave a Reply